本页还没有译文
本页 65 段还没译成Español,下面显示的是英文原文。Database migrations
还没翻译译自英文(supabase.com)本页 65 段都还没译
Supabase is a flexible platform that lets you decide how you want to build your projects. You can use the Dashboard directly to get up and running, or use a proper local setup. We suggest you work locally and deploy your changes to a linked project on the Supabase Platform.
Develop locally using the CLI to run a local Supabase stack. You can use the integrated Studio Dashboard to make changes, then capture your changes in schema migration files, which can be saved in version control.
Alternatively, if you're comfortable with migration files and SQL, you can write your own migrations and push them to the local database for testing before sharing your changes.
Looking for the full end-to-end workflow?
This page is a focused tutorial on migrations. If you want to move an existing platform project to local development, or set up a reproducible project from scratch and take it all the way to a remote deploy, see the Local development workflow guide. It covers both starting points, the daily development loop, pushing to production, cleaning up generated migrations, and troubleshooting.
Database migrations
Database changes are managed through "migrations." Database migrations are a common way of tracking changes to your database over time.
For this guide, we'll create a table called employees and see how we can make changes to it.
-
Create your first migration file
To get started, generate a new migration to store the SQL needed to create our
employeestablesupabase migration new create_employees_table
-
Add the SQL to your migration file
This creates a new migration: supabase/migrations/<timestamp> _create_employees_table.sql.
To that file, add the SQL to create this
employeestablecreate table employees ( id bigint primary key generated always as identity, name text, email text, created_at timestamptz default now() );
-
Apply your migration
Now that you have a migration file, you can run this migration and create the
employeestable.Use the
resetcommand here to reset the database to the current migrationssupabase db reset
-
Modify your employees table
Now you can visit your new
employeestable in the Dashboard.Next, modify your
employeestable by adding a column for department. Create a new migration file for that.supabase migration new add_department_to_employees_table
-
Add a new column to your table
This creates a new migration file: supabase/migrations/<timestamp> _add_department_to_employees_table.sql.
To that file, add the SQL to create a new department column
alter table if exists public.employees
add department text default 'Hooli';
Add sample data
Now that you are managing your database with migrations scripts, it would be great have some seed data to use every time you reset the database.
For this, you can create a seed script in supabase/seed.sql.
-
Populate your table
Insert data into your
employeestable with yoursupabase/seed.sqlfile.insert into public.employees (name) values ('Erlich Bachman'), ('Richard Hendricks'), ('Monica Hall');
-
Reset your database
Reset your database (apply current migrations), and populate with seed data
supabase db reset
You should now see the employees table, along with your seed data in the Dashboard! All of your database changes are captured in code, and you can reset to a known state at any time, complete with seed data.
Diffing changes
This workflow is great if you know SQL and are comfortable creating tables and columns. If not, you can still use the Dashboard to create tables and columns, and then use the CLI to diff your changes and create migrations.
Create a new table called cities, with columns id, name and population. To see the corresponding SQL for this, you can use the supabase db diff --schema public command. This will show you the SQL that will be run to create the table and columns. The output of supabase db diff will look something like this:
Diffing schemas: public
Finished supabase db diff on branch main.

create table "public"."cities" (
    "id" bigint primary key generated always as identity,
    "name" text,
    "population" bigint
);
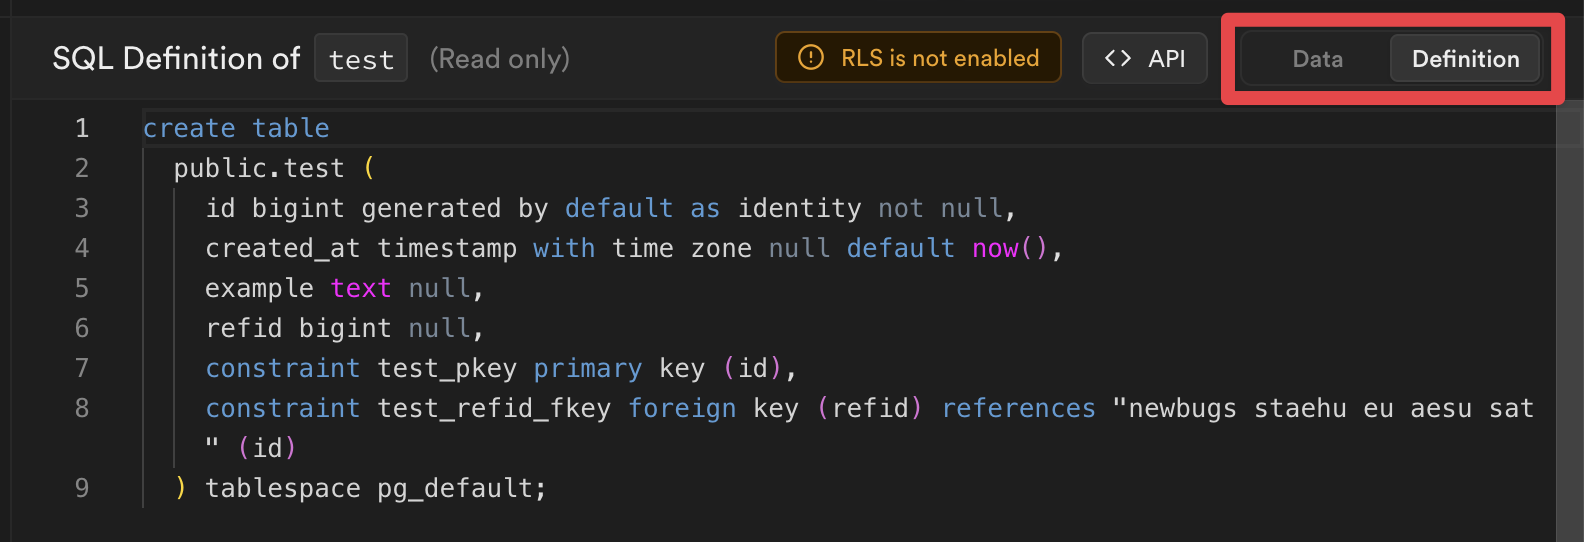
Alternately, you can view your table definitions directly from the Table Editor:
You can then copy this SQL into a new migration file, and run supabase db reset to apply the changes.
The last step is deploying these changes to a live Supabase project.
Deploy your project
You've been developing your project locally, making changes to your tables via migrations. It's time to deploy your project to the Supabase Platform and start scaling up to millions of users! Head over to Supabase and create a new project to deploy to.
Sign in to the Supabase CLI
supabase loginnpx supabase loginLink your project
Associate your local project with your remote project using supabase link.
supabase link --project-ref <project-id>
# You can get <project-id> from your project's dashboard URL: https://supabase.com/dashboard/project/<project-id>
Note
If your remote database already has schema changes that aren't in your local migrations (for example, tables you created directly in the Dashboard), capture them before you push:
supabase db pull
supabase db reset
db pull writes those changes to a <timestamp>_remote_schema.sql migration so your local and remote histories line up, and db reset re-applies your migrations locally to confirm they're consistent. For a brand-new remote project with nothing in it yet, skip this step.
Deploy database changes
Deploy any local database migrations using db push:
supabase db pushVisiting your live project on Supabase, you'll see a new employees table, complete with the department column you added in the second migration above.
Deploy Edge Functions
If your project uses Edge Functions, you can deploy these using functions deploy:
supabase functions deploy <function_name>Use Auth locally
To use Auth locally, update your project's supabase/config.toml file that gets created after running supabase init. Add any providers you want, and set enabled to true.
[auth.external.github]
enabled = true
client_id = "env(SUPABASE_AUTH_GITHUB_CLIENT_ID)"
secret = "env(SUPABASE_AUTH_GITHUB_SECRET)"
redirect_uri = "http://localhost:54321/auth/v1/callback"
As a best practice, any secret values should be loaded from environment variables. You can add them to .env file in your project's root directory for the CLI to automatically substitute them.
SUPABASE_AUTH_GITHUB_CLIENT_ID="redacted"
SUPABASE_AUTH_GITHUB_SECRET="redacted"
For these changes to take effect, you need to run supabase stop and supabase start again.
If you have additional triggers or RLS policies defined on your auth schema, how you pull them locally depends on your project's diff engine.
Which diff engine your project uses depends on config.toml. If it contains an [experimental.pgdelta] section with enabled = true, your project uses pg-delta. If the section is missing or enabled is false, your project uses the legacy migra engine. See Diff engines for how the two differ and how to switch.
On pg-delta, a plain supabase db pull captures your customizations automatically. Triggers on managed tables (such as a trigger on auth.users calling a function in public) and RLS policies on auth tables are included in the diff.
On the legacy migra engine, the initial pull's pg_dump skips the auth schema, but the diff pass that follows appends your triggers and RLS policies there to the same migration. Older CLI versions excluded the auth schema entirely and printed a message saying so. If you see that message, capture existing customizations once with an explicit pull:
supabase db pull --schema authSync storage buckets
On the pg-delta engine, your RLS policies on storage.objects and storage.buckets are also captured automatically by a plain supabase db pull. On the legacy migra engine, the diff pass that follows the initial pg_dump appends them to the same migration. If an older CLI prints a message that the storage schema was excluded, capture existing policies once with an explicit pull:
supabase db pull --schema storageThe buckets and objects themselves are rows in the storage tables so they won't appear in your schema. You can instead define them via supabase/config.toml file. For example,
[storage.buckets.images]
public = false
file_size_limit = "50MiB"
allowed_mime_types = ["image/png", "image/jpeg"]
objects_path = "./images"
This will upload files from supabase/images directory to a bucket named images in your project with one command.
supabase seed bucketsSync any schema with --schema
You can synchronize your database with a specific schema using the --schema option as follows:
supabase db pull --schema <schema_name>Caution
Using --schema
If the local supabase/migrations directory is empty, the db pull command will ignore the --schema parameter.
To fix this, you can pull twice:
supabase db pull
supabase db pull --schema <schema_name>
Limitations and considerations
The local development environment is not as feature-complete as the Supabase Platform. Here are some of the differences:
- You cannot update your project settings in the Dashboard. This must be done using the local config file.
- The CLI version determines the local version of Studio used, so make sure you keep your local Supabase CLI up to date. We're constantly adding new features and bug fixes.