本页只译了一部分
本页 29 段里还有 2 段没译成简体中文,没译的段落显示英文原文。SDE 级联
机器翻译译自英文(docs.typesafe.ai)本页 29 段里 2 段还没译
文档索引
在以下地址获取完整的文档索引:https://docs.typesafe.ai/llms.txt 使用此文件可以在进一步探索之前发现所有可用页面。
SDE 级联
使用两阶段结构化数据提取级联(mini → verify → reasoning)以极低的成本获得大型推理模型的大部分质量。
- 概述
- 大型推理模型能很好地提取结构化数据,但速度慢且昂贵
- 小型模型便宜,但容易出错
- 级联(cascade)能以极低的成本获得大部分质量
- 我们使用的模型及其价格(每 1M token 的美元数,输入 / 输出;标准费率核查于 2026 年 9 月 15 日):
- 第 0 级(迷你):
gpt-5.4-mini为 $0.75 / $4.50 - 第 1 级(推理):
gpt-5.5为 $5.00 / $30.00(大约是迷你版的 7 倍) - 验证器:TypeSafe
jev-1.12为 $0.042 / $0.00(输出 token 免费; 公布的 Jev 定价)
- 第 0 级(迷你):
- 算法
- 使用廉价/小型模型进行提取。
- 验证使用 TypeSafe 原语:每个字段的 是/否("Noul 问题"
问题
- (例如,“此值是否不存在于源中?”,“是否从无关文本中照搬?”),每个都返回 P(存在问题)。
- 如果验证器信号触发,则升级到昂贵的推理模型;否则保留廉价答案。
- 本 Cookbook
- 逐步演示一个真实示例,然后展示 100 个提示词之间的权衡
- 注意:这两个提取级别使用文本模式的 OpenAI
- 我们不使用结构化输出、工具调用或 json 模式,因为:
- 遵循 schema 的错误不是我们预期 LLM 会犯的错误(很容易为此生成合成数据)
- 如果 LLM 确实未能遵循 schema,它几乎总是非常困惑,所以约束解码并不能解决根本问题
- 但我们鼓励你尝试!
Setup
- 安装依赖项(TypeSafe 验证器客户端托管在 TypeSafe 的包索引中):
pip install openai datasets jsonschema ipython "typesafe-sdk>=0.5.7" cooksafe --extra-index-url https://pypi.typesafe.ai/- 然后在环境中设置
OPENAI_API_KEY和TYPESAFE_API_KEY
import json
import os
from pathlib import Path

import jsonschema
from cooksafe import JsonCache, make_playground_link
from datasets import load_dataset
from IPython.display import Markdown, display
from openai import OpenAI
from typesafe_sdk import Noul, NoulCriteria, TypeSafeClient

MINI = "gpt-5.4-mini"  # rung 0: cheap + fast
REASONING = "gpt-5.5"  # rung 1: strong, run with reasoning_effort="high"
TS_MODEL = "jev-1.12"  # the TypeSafe verifier model
FIRE_T = 0.7  # escalate if any per-field P(wrong) exceeds this; also the "<== FIRES" display marker

oai = OpenAI()

ts = TypeSafeClient(api_key=os.environ["TYPESAFE_API_KEY"], timeout=30.0)
步骤 1:数据
我们选择了一个名为 scrapegraphai 的 Hugging Face 数据集
SCRAPEGRAPHAI_REVISION = "4bb9fba1dff9181c5acdb60a5a26fea62fa54fe9"
row = load_dataset(
    "scrapegraphai/scrapegraphai-100k",
    revision=SCRAPEGRAPHAI_REVISION,
    split="train",
)[516]
schema = json.loads(row["schema"])
prompt = row["prompt"]
content = row["content"]

print(
    f"""
PROMPT
===========
{prompt}

SCHEMA
===========
{json.dumps(schema, indent=2)}

CONTENT
===========
{content}
""".strip()
)
PROMPT
===========
Find registration open date fall semester for New York University in New York, NY for the 2024-2025 school year.
SCHEMA
===========
{
"properties": {
"registration_open_date": {
"description": "The date that registration opens for the fall semester. MUST be in the format mm/dd/yyyy. For example, for a college in the 2024-2025 school year, it might be something like 09/05/2024. Return a blank string if you are unsure.",
"title": "Registration Open Date",
"type": "string"
},
"description": {
"description": "A brief description of the registration open date. For example, 'Registration opens for the fall semester'.",
"title": "Description",
"type": "string"
}
},
"required": [
"registration_open_date",
"description"
],
"title": "RegistrationOpen",
"type": "object"
}
CONTENT
===========
Skip to content Skip to current page navigation
[ ](https://www.nyu.edu/)
Search Site
[ ](https://www.nyu.edu/)
* [ Academics](https://www.nyu.edu/academics.html)
* [ Admissions](https://www.nyu.edu/admissions.html)
* [ Research](https://www.nyu.edu/research.html)
* [ University Life](https://www.nyu.edu/life.html)
* [ About](https://www.nyu.edu/about.html)
All NYU
# Mobile Navigation
[ ](https://www.nyu.edu/)
Search Site
* [Academics](https://www.nyu.edu/academics.html)
* [Admissions](https://www.nyu.edu/admissions.html)
* [Research](https://www.nyu.edu/research.html)
* [University Life](https://www.nyu.edu/life.html)
* [About](https://www.nyu.edu/about.html)
All NYU
Info for
* Back to main menu
* Info for
* [Students](https://www.nyu.edu/students.html)
* [Faculty](https://www.nyu.edu/faculty.html)
* [Alumni](https://www.nyu.edu/alumni.html)
* [Employees](https://www.nyu.edu/employees.html)
* [Community](https://www.nyu.edu/community.html)
[Log In](http://home.nyu.edu/)
Info for
* [Students](https://www.nyu.edu/students.html)
* [Faculty](https://www.nyu.edu/faculty.html)
* [Alumni](https://www.nyu.edu/alumni.html)
* [Employees](https://www.nyu.edu/employees.html)
* [Community](https://www.nyu.edu/community.html)
[Log In](https://home.nyu.edu/)
Search Site Search
# Events Calendar
Search Events
Apply Reset
* [About the Events Calendar ](https://www.nyu.edu/employees/resources-and-services/media-and-communications/digital-communications/university-events-calendar.html)
* [Events Calendar Tutorial ](https://www.nyu.edu/employees/resources-and-services/media-and-communications/digital-communications/university-events-calendar/tutorials.html)
* [Report issue or provide feedback ](https://nyu.service-now.com/sp?id=sc_cat_item&sys_id=7698dd2a98bcf4004c8c03063d84e274)
Search Filters Calendar
New York University
Equal Opportunity and Non-Discrimination at NYU - New York University is committed to maintaining an environment that encourages and fosters respect for individual values and appropriate conduct among all persons. In all University spaces--physical and digital--programming, activities, and events are carried out in accordance with applicable law as well as University policy, which includes but is not limited to its Non-Discrimination and Anti-Harassment Policy.
Unless otherwise noted, all content copyright New York University. All rights reserved.
* [Search](https://search.nyu.edu/)
* [Campus Map](https://www.nyu.edu/map.html)
* [Events](https://events.nyu.edu/)
* [Contact Us](https://www.nyu.edu/contact-us.html)
* [Give](https://www.nyu.edu/about/giving.html)
* [Copyright & Fair Use](https://www.nyu.edu/copyright-and-fair-use.html)
* [Privacy](https://www.nyu.edu/privacy.html)
* [Accessibility](https://www.nyu.edu/accessibility.html)
* [Feedback](https://www.nyu.edu/#feedback.html)
* [New York Campus](https://www.nyu.edu/)
* [Abu Dhabi Campus](https://nyuad.nyu.edu/)
* [Shanghai Campus](https://shanghai.nyu.edu/)
* [](https://facebook.com/)
* [](https://linkedin.com/)
* [](https://x.com/)
* [](https://instagram.com/)
* [](https://youtube.com/)- 此行是一个 NYU 事件日历页面(“2024 年秋季普查日期”):
- Schema 仅要求两个字段:
registration_open_date和description - 提示抓取仅捕获了日历导航和模板文本:没有注册日期或描述
- 注意 Schema 的
description字段甚至在其字段描述中自带了一个 示例 值(“秋季学期开始注册”)
- Schema 仅要求两个字段:
- 因此,行为良好的提取器应拒绝编造页面不包含的字段
- 让我们看看小型模型是否能做得正确!
步骤 2:使用小型模型提取(文本模式)
- 注意:
gpt-5.4-mini对此输入非常随机 —— 即使在temperature=0时,它几乎每次运行都会捏造不同的description。为了可复现的操作步骤,我们 硬编码了一个本笔记本其余部分解释的标准捏造(且验证器将其标记为 P(wrong) > 0.8)。真正的管道将直接采用extract(MINI, prompt, schema, content, temperature=0)。
EXTRACT_SYSTEM = (
    "You extract structured data from documents. Return only values supported by the text. "
    "Follow any value format specified by the schema or its field descriptions."
)


# LLM and TypeSafe calls are cached to ``json_cache.json``, which ships with the cookbook, so
# re-rendering reproduces the published results with no API spend; delete the file to re-run live.
json_cache = JsonCache(Path("json_cache.json"))


@json_cache
def extract(
    model: str,
    prompt: str,
    schema: dict,
    content: str,
    *,
    reasoning_effort: str | None = None,
    temperature: float | None = None,
) -> dict:
    user = (
        f"{prompt}\n\nReturn ONLY a JSON object matching this JSON Schema:\n"
        f"{json.dumps(schema, indent=2)}\n\nDocument:\n{content}"
    )
    kwargs = {
        "model": model,
        "messages": [
            {"role": "system", "content": EXTRACT_SYSTEM},
            {"role": "user", "content": user},
        ],
    }
    if reasoning_effort:
        kwargs["reasoning_effort"] = reasoning_effort
    if temperature is not None:
        kwargs["temperature"] = temperature
    text = oai.chat.completions.create(**kwargs).choices[0].message.content
    # The prompt asks for ONLY a JSON object, so parse the reply as-is -- no regex fishing a
    # substring out of a malformed reply. If ``json.loads`` fails, treat it as an empty extraction
    # (the record-level analog of NaN): every field reads as absent, which the verifier flags and the
    # gate escalates -- the safe direction. Schema-following errors are rare here (see the overview).
    try:
        return json.loads(text)
    except (ValueError, json.JSONDecodeError):
        return {}


# Hard-coded canonical fabrication (see note above); a real pipeline would use extract(MINI, prompt, schema, content, temperature=0).
mini_record = {
    "registration_open_date": "",
    "description": "Registration opens for the fall semester",
}
print("mini extraction:\n", json.dumps(mini_record, indent=2))

# The record is a perfect fit for the JSON Schema -- and still wrong. Schema validation is necessary
# but not sufficient: it catches structural errors, never semantic ones. That gap is the whole point.
print("\nschema-valid:", jsonschema.Draft202012Validator(schema).is_valid(mini_record))
mini extraction:
{
"registration_open_date": "",
"description": "Registration opens for the fall semester"
}
schema-valid: True
- 记录是 schema 有效 的(上一行打印
True),但它是错误的:registration_open_date留空,这与页面一致:页面未说明日期- 但
description是捏造的:页面从未描述注册日期,因此迷你模型捏造了一个看似合理的答案。它可能会重复 schema 自己的示例,“秋季学期注册开放”,或叙述“...在文档中未找到” - JSON-Schema 检查无法发现这一点。廉价模型会产生这种自信且符合 schema 的捏造数据,捕获它们需要语义验证器
步骤 3:使用 TypeSafe 进行验证
- 验证器是 TypeSafe;对于每个字段,我们构建一个
Noul问题:- 一个狭窄的是/非问题,构建方式使得
true= 有问题(升级)
- 一个狭窄的是/非问题,构建方式使得
- TypeSafe 返回每个问题的校准后
noul=P(true),在一个 system_one 调用中完成 - 问题集:
- 一个整体
__overall__::judge头(“此记录应升级吗?”)。我们计算并展示它以对比整体记录判断与每个字段的头部,但步骤 4 中的门控不使用它——升级由每个字段的问题组驱动。 - 每个字段的问题组
- 非空字段获取完整的头部集
- 空字段(null / "" / [])仅获取
absence_wrong头部
- (完整管道还具有针对整个容器的
spurious头部和整体difficulty分数;此处未显示,以便将本教程限于这两个门控头部)
- 一个整体
- TypeSafe 方式:分解
- 注意如何以编程方式分解所有内容,这就是 TypeSafe 方式。
- 分解最大化了每个提示的智能,并使算法可调且可解释。
-
# metric -> (question, NoulCriteria)
MAIN_QUESTIONS = {
    "name_desc_mismatch": (
        "Does the `extracted_field` fail to match the field at `path` or the `description` in the "
        "`field_spec`? If the `description` is empty, judge against the `path` alone.",
        NoulCriteria(
            true="the `extracted_field` does not match the field name or its `description`",
            false="the `extracted_field` matches the field name and `description`",
        ),
    ),
    "type_mismatch": (
        "Does the `extracted_field` violate the `type` declared in the `field_spec`?",
        NoulCriteria(
            true="the `extracted_field` violates the declared `type`",
            false="the `extracted_field` conforms to the declared `type`",
        ),
    ),
    "unreasonable": (
        "Is the `extracted_field` one that a reasonable person would not have extracted for this "
        "`field_spec`?",
        NoulCriteria(
            true="a reasonable person would not have extracted this value",
            false="the extraction is reasonable",
        ),
    ),
    "hallucinated": (
        "Is the `extracted_field` unsupported by, or absent from, the source text?",
        NoulCriteria(
            true="the `extracted_field` is a hallucination -- not supported by, or absent "
            "from, the source text",
            false="the `extracted_field` is supported by the source text",
        ),
    ),
    "off_target": (
        "Does the source text fail to genuinely report the thing the `field_spec` describes, so the "
        "value was pulled from incidental text?",
        NoulCriteria(
            true="the source does not genuinely provide this field -- the value was pulled "
            "from incidental text",
            false="the source genuinely reports this field",
        ),
    ),
    "incomplete": (
        "Does the `extracted_field` fail to capture a value the source supports (note whether the "
        "`field_spec` is `required`)?",
        NoulCriteria(
            true="the field is wrongly empty, null, or missing a value the source supports",
            false="the field captures the value the source supports",
        ),
    ),
    "format_violation": (
        "Does the `extracted_field` violate the format or constraints implied by the `description`, "
        "the schema `type`, and the extraction instructions (e.g. date format, units, enum membership)?",
        NoulCriteria(
            true="the `extracted_field` violates the implied format or constraints",
            false="the `extracted_field` satisfies the format and constraints",
        ),
    ),
}
ABSENCE_QUESTION = (
    "The `extracted_field` is empty, null, or an empty collection. Does the source text contain the "
    "information the `field_spec` describes, making the empty result wrong?"
)
ABSENCE_CRITERIA = NoulCriteria(
    true="a value was wrongly omitted", false="returning nothing is correct"
)

# The pipeline also asks one holistic, whole-record head: "should this be escalated?"
OVERALL_JUDGE = (
    "Is this extracted record an incorrect extraction -- some value unsupported by the source or "
    "not conforming to the schema, required information missing or wrong, or some field hallucinated -- "
    "so it should be escalated to a smarter model?"
)
OVERALL_JUDGE_CRITERIA = NoulCriteria(
    true="the record is an incorrect extraction",
    false="the record is a correct extraction",
)


def is_empty(v) -> bool:
    return v is None or (isinstance(v, (str, list, dict)) and len(v) == 0)


def field_spec(name: str) -> dict:
    """Minimal spec pulled from the schema (unwrapping anyOf/null for optional fields)."""
    p = schema["properties"][name]
    branches = p.get("anyOf") or []
    typ = p.get("type") or next(
        (b["type"] for b in branches if b.get("type") != "null"), "unknown"
    )
    return {
        "path": name,
        "type": typ,
        "description": p.get("description", ""),
        "required": name in schema.get("required", []),
    }


def build_questions(record: dict) -> dict[str, Noul]:
    """The verify question set: one holistic ``__overall__::judge`` head plus a per-field battery,
    keyed ``field::metric`` (mirrors build_verify_prompts)."""
    questions: dict[str, Noul] = {
        "__overall__::judge": Noul(
            instructions=OVERALL_JUDGE, criteria=OVERALL_JUDGE_CRITERIA
        ),
    }
    for name, value in record.items():
        spec = field_spec(name)
        if is_empty(value):
            questions[f"{name}::absence_wrong"] = Noul(
                instructions={
                    "field_spec": spec,
                    "extracted_field": value,
                    "main_question": ABSENCE_QUESTION,
                },
                criteria=ABSENCE_CRITERIA,
            )
            continue
        for metric, (question, criteria) in MAIN_QUESTIONS.items():
            if metric == "type_mismatch" and spec["type"] == "unknown":
                continue
            questions[f"{name}::{metric}"] = Noul(
                instructions={
                    "field_spec": spec,
                    "extracted_field": value,
                    "main_question": question,
                },
                criteria=criteria,
            )
    return questions


@json_cache
def verify(record: dict) -> dict[str, float | str]:
    """Run the whole Noul battery over a record in one TypeSafe call; return ``{field::metric: P(true)}``."""
    state = {
        "system_message": EXTRACT_SYSTEM,
        "instruction": "Extract the structured record from this document",
        "source_text": row["content"],
        "schema": schema,
        "extraction": record,
    }
    questions = build_questions(record)
    answers = ts.system_one(state=state, questions=questions, model=TS_MODEL).answers
    return {qid: ans.noul for qid, ans in answers.items()} | {
        "playground_link": make_playground_link(state, questions)
    }
对小型提取结果运行整个问题组
checks = verify(mini_record)
playground_link = checks.pop("playground_link")
display(
    Markdown(
        f"🔗 [Open this verification in the TypeSafe playground]({playground_link})"
    )
)

print(f"{'qid':<40}{'P(wrong)':>9}")
print("-" * 50)
for fld, p in sorted(checks.items(), key=lambda c: -c[-1]):
    flag = "  <== FIRES" if p > FIRE_T else ""
    print(f"{fld:<40}{p:>9.2f}{flag}")
qid P(wrong)
--------------------------------------------------
description::hallucinated 0.95 <== FIRES
description::off_target 0.85 <== FIRES
description::unreasonable 0.58
__overall__::judge 0.56
description::incomplete 0.16
registration_open_date::absence_wrong 0.14
description::format_violation 0.10
description::name_desc_mismatch 0.08
description::type_mismatch 0.02
在 TypeSafe playground 中打开此验证 →
- TypeSafe 将信号集中在实际错误的字段上。
- 我们的结果是经过校准的:在错误的字段上评分高,在正确的字段上评分低,在看似有问题但并非明显错误的字段上评分中等
- 这就是 TypeSafe 验证器相比粗略的“这一切好吗?”评判能为你带来的优势
步骤 4:升级门控
- 现在我们在
any_flag上进行门控:如果 任何 字段标志超过FIRE_T(0.7,上述设置并与步骤 3 中的<== FIRES标记共享),则升级 - 这是一个
max式门控(如果 任何 字段触发则升级),而非平均值,因此一个自信的红旗就足以触发升级,而不是被平均成沉默
# any_flag is a per-field gate: the holistic __overall__ head is shown above but not part of it
fired = {
    qid: p
    for qid, p in checks.items()
    if not qid.startswith("__overall__") and p > FIRE_T
}
escalate = bool(fired)

print(
    f"any_flag gate (threshold {FIRE_T}): {'ESCALATE' if escalate else 'ACCEPT cheap result'}"
)
for qid, p in sorted(fired.items(), key=lambda c: -c[1]):
    print(f"  fired: {qid}  (P={p:.2f})")
any_flag gate (threshold 0.7): ESCALATE
fired: description::hallucinated (P=0.95)
fired: description::off_target (P=0.85)
步骤 5:升级至推理模型
由于触发了信号,我们为强模型(gpt-5.5,reasoning_effort="high"付费)
final_record = (
    extract(REASONING, prompt, schema, content, reasoning_effort="high")
    if escalate
    else mini_record
)

print("mini      :", json.dumps(mini_record))
print("reasoning :", json.dumps(final_record))
print("\nfield-level diff (mini -> final):")
for name in mini_record:
    if mini_record[name] != final_record.get(name):
        print(f"  {name}: {mini_record[name]!r}  ->  {final_record.get(name)!r}")
mini : {"registration_open_date": "", "description": "Registration opens for the fall semester"}
reasoning : {"description": "", "registration_open_date": ""}
field-level diff (mini -> final):
description: 'Registration opens for the fall semester' -> ''
- 改进之处
- 推理模型丢弃了虚构的
description,返回"" - 它识别出页面从未描述注册日期,并拒绝编造一个
- 级联将自信但符合 schema 的虚构内容转变为诚实的空字段
- 它仅为此单项支付推理模型费用,这正是因为验证器指示它这样做
- 推理模型丢弃了虚构的
步骤 6:在 100 个提示中的表现
- 这些是 TypeSafe 的内部结果,由上述通用方法生成:
- 相同的
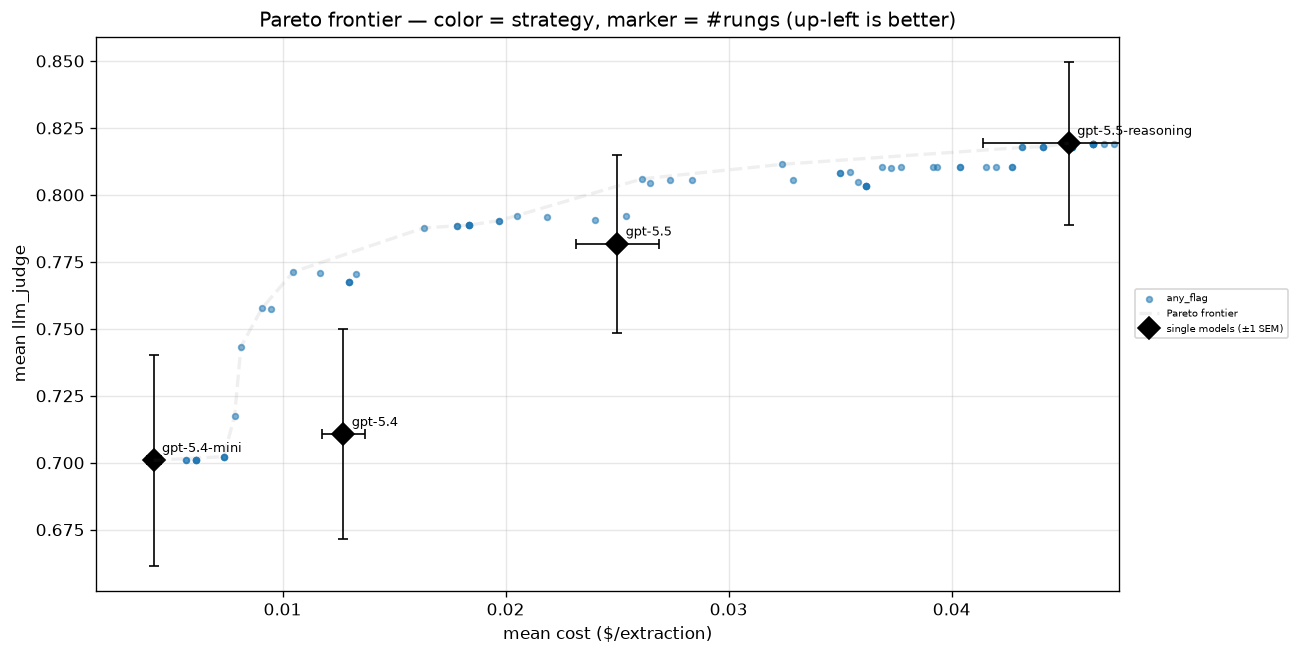
extract → verify → escalate循环,gpt-5.4-mini → gpt-5.5-reasoning,对每个字段头进行any_flag门控,运行于 100 个 scrapegraphai 提示词之上 - 每个项目的廉价级别提取均由 TypeSafe 评分;门控阈值(“cut”)在 0→1 之间扫描,每个生成的配置都绘制在(成本,质量)空间中
- 该图表是历史快照;其成本未按当前 Jev 费率重新计算
- 相同的
- 如何解读:
- 黑菱形 = 四个模型独立运行(成本随能力上升;最强模型
gpt-5.5-reasoning位于右上,质量 ≈0.81,成本 ≈$0.10/提取) - 蓝点 = 多个门控阈值下的级联;虚线是帕累托前沿
- 级联前沿位于每个单独模型的左上方:扫描门控让你以一小部分成本获得顶级模型的大部分质量
- 廉价阶梯以近零成本处理简单项,仅已标记项支付推理模型费用
- 黑菱形 = 四个模型独立运行(成本随能力上升;最强模型
附录 A:什么是好的验证器信号
- 级联的效果取决于其验证器;区分有用信号与无用信号的关键在于:
- 狭窄且有据可依。
- 针对源数据中某个字段进行一个可验证的是/非判断(例如,“此值在源数据中缺失吗?”),而不是模糊的“此提取结果好吗?”。
- 模糊的问题会导致模糊、未校准的分数。
- 错误 = TRUE,且有明确标准。
- 将每个问题构建为 升级 情况对应
true,并明确说明true/false的含义。
- 将每个问题构建为 升级 情况对应
- 每个字段独立判断,然后用
max聚合。- 每个字段的标志能定位错误,并保持稀疏和强信号。
max(“任何标志触发”)确保一个自信的红旗触发升级,而不是被平均成沉默。
- 独立且便宜。
- 专门用于判断输出的验证器(此处为 TypeSafe)能捕捉提取器自身的盲点。
- 它必须便宜,否则就没有节省下来的成本可供利用。
- 区分度高 / 已校准。
- 好的信号在真实错误上高,在正确项上低,因此单一阈值能清晰区分接受与升级。
- 正是这种区分度将帕累托曲线推向左上方。
- 狭窄且有据可依。
AI 翻译查看英文原文