本页还没有译文
本页 34 段还没译成简体中文,下面显示的是英文原文。Stores
还没翻译译自英文(docs.langchain.com)本页 34 段都还没译
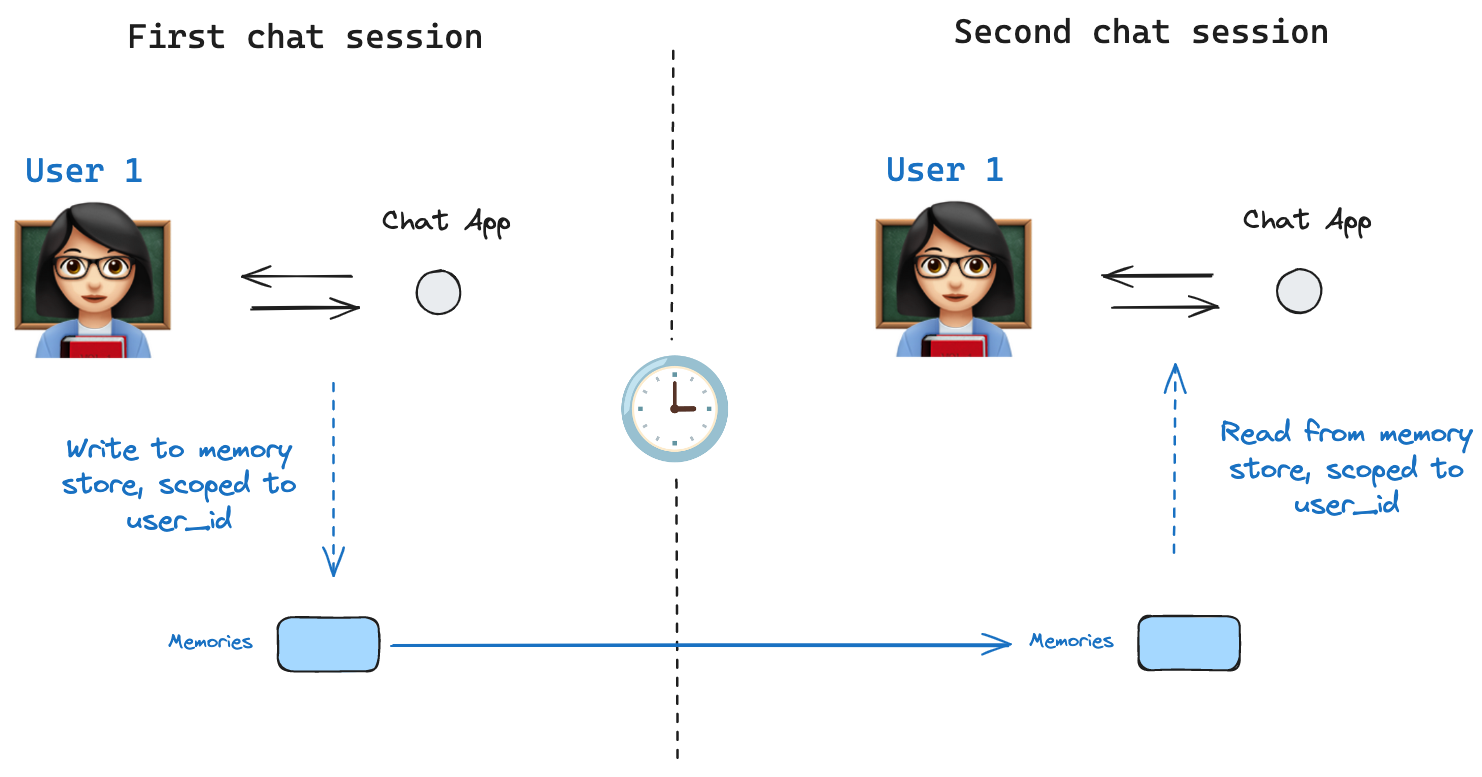
Stores let agents persist information across threads, including user preferences, accumulated knowledge, and facts that should survive beyond a single conversation. Unlike checkpointers, which save the full graph state scoped to one thread, stores hold arbitrary key-value data accessible from any thread.
Info
Agent Server handles stores automatically When using the Agent Server, you do not need to implement or configure stores manually. The API handles all storage infrastructure for you behind the scenes.
Note
InMemoryStore is suitable for development and testing. For production, use a persistent store like PostgresStore, MongoDBStore, RedisStore, or UpstashStore. All implementations extend BaseStore, which is the type annotation to use in node function signatures.
Note
See store integrations for the full list of available providers.
Basic usage
The following code snippet shows the InMemoryStore in isolation without using LangGraph:
import { InMemoryStore } from "@langchain/langgraph";

const memoryStore = new InMemoryStore();
Memories are namespaced by a tuple, which is (<user_id>, "memories") in the following example. The namespace can be any length and represent anything, does not have to be user specific.
const userId = "1";
const namespaceForMemory = [userId, "memories"];
Use the store.put method to save memories to the namespace in the store. Specify the namespace, as defined above, and a key-value pair for the memory: the key is simply a unique identifier for the memory (memory_id) and the value (a dictionary) is the memory itself.
import { v7 as uuid7 } from "uuid";
const memoryId = uuid7();
const memory = { food_preference: "I like pizza" };
await memoryStore.put(namespaceForMemory, memoryId, memory);
Read out memories from your namespace using the store.search method, which returns memories for a given user as a list, up to the limit argument (default 10). With InMemoryStore, items are returned in insertion order, so the most recent memory is last in the list; other backends may order memories differently (see Listing items in a namespace).
const memories = await memoryStore.search(namespaceForMemory);
memories[memories.length - 1];

// {
//   value: { food_preference: 'I like pizza' },
//   key: '07e0caf4-1631-47b7-b15f-65515d4c1843',
//   namespace: ['1', 'memories'],
//   createdAt: '2024-10-02T17:22:31.590602+00:00',
//   updatedAt: '2024-10-02T17:22:31.590605+00:00'
// }
The attributes it has are:
-
value: The value of this memory -
key: A unique key for this memory in this namespace -
namespace: A tuple of strings, the namespace of this memory typeNote
While the type is
tuple, it may be serialized as a list when converted to JSON (for example,['1', 'memories']). -
createdAt: Timestamp for when this memory was created -
updatedAt: Timestamp for when this memory was updated
Listing items in a namespace
Calling store.search with no query and no filter returns the items stored under the namespace prefix, up to limit. Use this to enumerate everything in a namespace when you don't need semantic ranking.
// Return up to 100 items stored under ["alice", "memories"].
const items = await store.search(["alice", "memories"], { limit: 100 });
Three behaviors to keep in mind:
namespace_prefixmatches by prefix, not exactly.("alice",)also returns items under("alice", "memories"),("alice", "preferences"), and so on. To restrict to a single level, pass the full namespace or filter the returned items client-side onitem.namespace.- Results past
limitare silently truncated. There is no overflow signal—setlimitabove your expected maximum, or paginate withoffset. - Default ordering depends on the store backend.
PostgresStoreandAsyncPostgresStorereturn results ordered byupdated_atdescending (most recently updated first).InMemoryStorereturns results in insertion order (most recently inserted last). Do not rely on a specific order across implementations; sort client-side onitem.updated_atif order matters.
To page through a large namespace:
const pageSize = 50;
let offset = 0;
while (true) {
  const page = await store.search(["alice", "memories"], { limit: pageSize, offset });
  if (page.length === 0) break;
  for (const item of page) {
    // ...
  }
  offset += pageSize;
}
To discover which namespaces exist (for example, to iterate over every user before listing their memories), use store.listNamespaces:
// All namespaces that start with ["alice"], truncated to two levels deep.
const namespaces = await store.listNamespaces({ prefix: ["alice"], maxDepth: 2 });
Semantic search
Beyond simple retrieval, the store also supports semantic search, allowing you to find memories based on meaning rather than exact matches. To enable this, configure the store with an embedding model:
import { OpenAIEmbeddings } from "@langchain/openai";

const store = new InMemoryStore({
  index: {
    embeddings: new OpenAIEmbeddings({ model: "text-embedding-3-small" }),
    dims: 1536,
    fields: ["food_preference", "$"], // Fields to embed
  },
});
Now when searching, you can use natural language queries to find relevant memories:
// Find memories about food preferences
// (This can be done after putting memories into the store)
const memories = await store.search(namespaceForMemory, {
  query: "What does the user like to eat?",
  limit: 3, // Return top 3 matches
});
You can control which parts of your memories get embedded by configuring the fields parameter or by specifying the index parameter when storing memories:
// Store with specific fields to embed
await store.put(
  namespaceForMemory,
  uuid7(),
  {
    food_preference: "I love Italian cuisine",
    context: "Discussing dinner plans",
  },
  { index: ["food_preference"] } // Only embed "food_preferences" field
);

import { v7 as uuid7 } from "uuid";
// Store without embedding (still retrievable, but not searchable)
await store.put(
  namespaceForMemory,
  uuid7(),
  { system_info: "Last updated: 2024-01-01" },
  { index: false }
);
Using in LangGraph
The memoryStore works hand-in-hand with the checkpointer: the checkpointer saves state to threads, as discussed above, and the memoryStore allows you to store arbitrary information for access across threads. Compile the graph with both the checkpointer and the memoryStore as follows.
import { MemorySaver } from "@langchain/langgraph";

// We need this because we want to enable threads (conversations)
const checkpointer = new MemorySaver();

// ... Define the graph ...

// Compile the graph with the checkpointer and store
const graph = workflow.compile({ checkpointer, store: memoryStore });
Then invoke the graph with a thread_id, as before, and also with a user_id, which serves as the namespace for memories for this particular user as before.
// Invoke the graph
const userId = "1";
const config = { configurable: { thread_id: "1" }, context: { userId } };

// First let's just say hi to the AI
for await (const update of await graph.stream(
  { messages: [{ role: "user", content: "hi" }] },
  { ...config, streamMode: "updates" }
)) {
  console.log(update);
}
You can access the store and the userId from any node with the runtime argument. You can use it to save memories:
import { StateSchema, MessagesValue, Runtime } from "@langchain/langgraph";
import { v7 as uuid7 } from "uuid";

const MessagesState = new StateSchema({
  messages: MessagesValue,
});

const updateMemory: GraphNode<typeof MessagesState> = async (state, runtime) => {
  // Get the user id from the config
  const userId = runtime.context?.user_id;
  if (!userId) throw new Error("User ID is required");

  // Namespace the memory
  const namespace = [userId, "memories"];

  // ... Analyze conversation and create a new memory
  const memory = "Some memory content";

  // Create a new memory ID
  const memoryId = uuid7();

  // We create a new memory
  await runtime.store?.put(namespace, memoryId, { memory });
};
You can also access the store from any node and use the store.search method to get memories. Memories are returned as a list of objects that can be converted to a dictionary.
memories[memories.length - 1];
// {
//   value: { food_preference: 'I like pizza' },
//   key: '07e0caf4-1631-47b7-b15f-65515d4c1843',
//   namespace: ['1', 'memories'],
//   createdAt: '2024-10-02T17:22:31.590602+00:00',
//   updatedAt: '2024-10-02T17:22:31.590605+00:00'
// }
You access the memories and use them in model calls.
const callModel: GraphNode<typeof MessagesState> = async (state, runtime) => {
  // Get the user id from the config
  const userId = runtime.context?.user_id;

  // Namespace the memory
  const namespace = [userId, "memories"];

  // Search based on the most recent message
  const memories = await runtime.store?.search(namespace, {
    query: state.messages[state.messages.length - 1].content,
    limit: 3,
  });
  const info = memories.map((d) => d.value.memory).join("\n");

  // ... Use memories in the model call
};
If you create a new thread, you can still access the same memories so long as the user_id is the same.
// Invoke the graph
const config = { configurable: { thread_id: "2" }, context: { userId: "1" } };

// Let's say hi again
for await (const update of await graph.stream(
  { messages: [{ role: "user", content: "hi, tell me about my memories" }] },
  { ...config, streamMode: "updates" }
)) {
  console.log(update);
}
When you use LangSmith locally (e.g., in Studio) or hosted, the base store is available to use by default and you do not need to specify it during graph compilation. To enable semantic search, however, you do need to configure the indexing settings in your langgraph.json file. For example:
{
    ...
    "store": {
        "index": {
            "embed": "openai:text-embeddings-3-small",
            "dims": 1536,
            "fields": ["$"]
        }
    }
}
See the deployment guide for more details and configuration options.
Next steps
- Add a custom store to Agent Server — deploying your implementation
- Checkpointers — thread-scoped state persistence