本页还没有译文
本页 69 段还没译成한국어,下面显示的是英文原文。Subgraphs
还没翻译译自英文(docs.langchain.com)本页 69 段都还没译
This guide explains the mechanics of using subgraphs. A subgraph is a graph that is used as a node in another graph.
Subgraphs are useful for:
- Building multi-agent systems
- Reusing a set of nodes in multiple graphs
- Distributing development: when you want different teams to work on different parts of the graph independently, you can define each part as a subgraph, and as long as the subgraph interface (the input and output schemas) is respected, the parent graph can be built without knowing any details of the subgraph
Setup
npm install @langchain/langgraphTip
Set up LangSmith for LangGraph development Sign up for LangSmith to quickly spot issues and improve the performance of your LangGraph projects. LangSmith lets you use trace data to debug, test, and monitor your LLM apps built with LangGraph—read more about how to get started with LangSmith.
Define subgraph communication
When adding subgraphs, you need to define how the parent graph and the subgraph communicate:
| Pattern | When to use | State schemas |
|---|---|---|
| Call a subgraph inside a node | Parent and subgraph have different state schemas (no shared keys), or you need to transform state between them | You write a wrapper function that maps parent state to subgraph input and subgraph output back to parent state |
| Add a subgraph as a node | Parent and subgraph share state keys—the subgraph reads from and writes to the same channels as the parent | You pass the compiled subgraph directly to add_node—no wrapper function needed |
Call a subgraph inside a node
When the parent graph and subgraph have different state schemas (no shared keys), invoke the subgraph inside a node function. This is common when you want to keep a private message history for each agent in a multi-agent system.
The node function transforms the parent state to the subgraph state before invoking the subgraph, and transforms the results back to the parent state before returning.
import { StateGraph, StateSchema, START } from "@langchain/langgraph";
import * as z from "zod";

const SubgraphState = new StateSchema({
  bar: z.string(),
});

// Subgraph
const subgraphBuilder = new StateGraph(SubgraphState)
  .addNode("subgraphNode1", (state) => {
    return { bar: "hi! " + state.bar };
  })
  .addEdge(START, "subgraphNode1");

const subgraph = subgraphBuilder.compile();

// Parent graph
const State = new StateSchema({
  foo: z.string(),
});

// Transform the state to the subgraph state and back
const builder = new StateGraph(State)
  .addNode("node1", async (state) => {
    const subgraphOutput = await subgraph.invoke({ bar: state.foo });
    return { foo: subgraphOutput.bar };
  })
  .addEdge(START, "node1");

const graph = builder.compile();
Full example: different state schemas
import { StateGraph, StateSchema, START } from "@langchain/langgraph";
import * as z from "zod";

// Define subgraph
const SubgraphState = new StateSchema({
  // note that none of these keys are shared with the parent graph state
  bar: z.string(),
  baz: z.string(),
});

const subgraphBuilder = new StateGraph(SubgraphState)
  .addNode("subgraphNode1", (state) => {
    return { baz: "baz" };
  })
  .addNode("subgraphNode2", (state) => {
    return { bar: state.bar + state.baz };
  })
  .addEdge(START, "subgraphNode1")
  .addEdge("subgraphNode1", "subgraphNode2");

const subgraph = subgraphBuilder.compile();

// Define parent graph
const ParentState = new StateSchema({
  foo: z.string(),
});

const builder = new StateGraph(ParentState)
  .addNode("node1", (state) => {
    return { foo: "hi! " + state.foo };
  })
  .addNode("node2", async (state) => {
    const response = await subgraph.invoke({ bar: state.foo });   // [!code highlight]
    return { foo: response.bar };   // [!code highlight]
  })
  .addEdge(START, "node1")
  .addEdge("node1", "node2");

const graph = builder.compile();

const stream = await graph.streamEvents(
  { foo: "foo" },
  { subgraphs: true, version: "v3" }
);
for await (const message of stream.messages) {
  for await (const token of message.text) {
    process.stdout.write(token);
  }
}- Transform the state to the subgraph state
- Transform response back to the parent state
[[], { node1: { foo: 'hi! foo' } }]
[['node2:9c36dd0f-151a-cb42-cbad-fa2f851f9ab7'], { subgraphNode1: { baz: 'baz' } }]
[['node2:9c36dd0f-151a-cb42-cbad-fa2f851f9ab7'], { subgraphNode2: { bar: 'hi! foobaz' } }]
[[], { node2: { foo: 'hi! foobaz' } }]
Full example: different state schemas (two levels of subgraphs)
This is an example with two levels of subgraphs: parent -> child -> grandchild.
import { StateGraph, StateSchema, START, END } from "@langchain/langgraph";
import * as z from "zod";

// Grandchild graph
const GrandChildState = new StateSchema({
  myGrandchildKey: z.string(),
});

const grandchild = new StateGraph(GrandChildState)
  .addNode("grandchild1", (state) => {
    // NOTE: child or parent keys will not be accessible here
    return { myGrandchildKey: state.myGrandchildKey + ", how are you" };
  })
  .addEdge(START, "grandchild1")
  .addEdge("grandchild1", END);

const grandchildGraph = grandchild.compile();

// Child graph
const ChildState = new StateSchema({
  myChildKey: z.string(),
});

const child = new StateGraph(ChildState)
  .addNode("child1", async (state) => {
    // NOTE: parent or grandchild keys won't be accessible here
    const grandchildGraphInput = { myGrandchildKey: state.myChildKey };   // [!code highlight]
    const grandchildGraphOutput = await grandchildGraph.invoke(grandchildGraphInput);
    return { myChildKey: grandchildGraphOutput.myGrandchildKey + " today?" };   // [!code highlight]
  })   // [!code highlight]
  .addEdge(START, "child1")
  .addEdge("child1", END);

const childGraph = child.compile();

// Parent graph
const ParentState = new StateSchema({
  myKey: z.string(),
});

const parent = new StateGraph(ParentState)
  .addNode("parent1", (state) => {
    // NOTE: child or grandchild keys won't be accessible here
    return { myKey: "hi " + state.myKey };
  })
  .addNode("child", async (state) => {
    const childGraphInput = { myChildKey: state.myKey };   // [!code highlight]
    const childGraphOutput = await childGraph.invoke(childGraphInput);
    return { myKey: childGraphOutput.myChildKey };   // [!code highlight]
  })   // [!code highlight]
  .addNode("parent2", (state) => {
    return { myKey: state.myKey + " bye!" };
  })
  .addEdge(START, "parent1")
  .addEdge("parent1", "child")
  .addEdge("child", "parent2")
  .addEdge("parent2", END);

const parentGraph = parent.compile();

const stream = await parentGraph.streamEvents(
  { myKey: "Bob" },
  { subgraphs: true, version: "v3" }
);
for await (const message of stream.messages) {
  for await (const token of message.text) {
    process.stdout.write(token);
  }
}- We're transforming the state from the child state channels (
myChildKey) to the grandchild state channels (myGrandchildKey) - We're transforming the state from the grandchild state channels (
myGrandchildKey) back to the child state channels (myChildKey) - We're passing a function here instead of just compiled graph (
grandchildGraph) - We're transforming the state from the parent state channels (
myKey) to the child state channels (myChildKey) - We're transforming the state from the child state channels (
myChildKey) back to the parent state channels (myKey) - We're passing a function here instead of just a compiled graph (
childGraph)
[[], { parent1: { myKey: 'hi Bob' } }]
[['child:2e26e9ce-602f-862c-aa66-1ea5a4655e3b', 'child1:781bb3b1-3971-84ce-810b-acf819a03f9c'], { grandchild1: { myGrandchildKey: 'hi Bob, how are you' } }]
[['child:2e26e9ce-602f-862c-aa66-1ea5a4655e3b'], { child1: { myChildKey: 'hi Bob, how are you today?' } }]
[[], { child: { myKey: 'hi Bob, how are you today?' } }]
[[], { parent2: { myKey: 'hi Bob, how are you today? bye!' } }]
Add a subgraph as a node
When the parent graph and subgraph share state keys, you can pass a compiled subgraph directly to add_node. No wrapper function is needed—the subgraph reads from and writes to the parent's state channels automatically. For example, in multi-agent systems, the agents often communicate over a shared messages key.
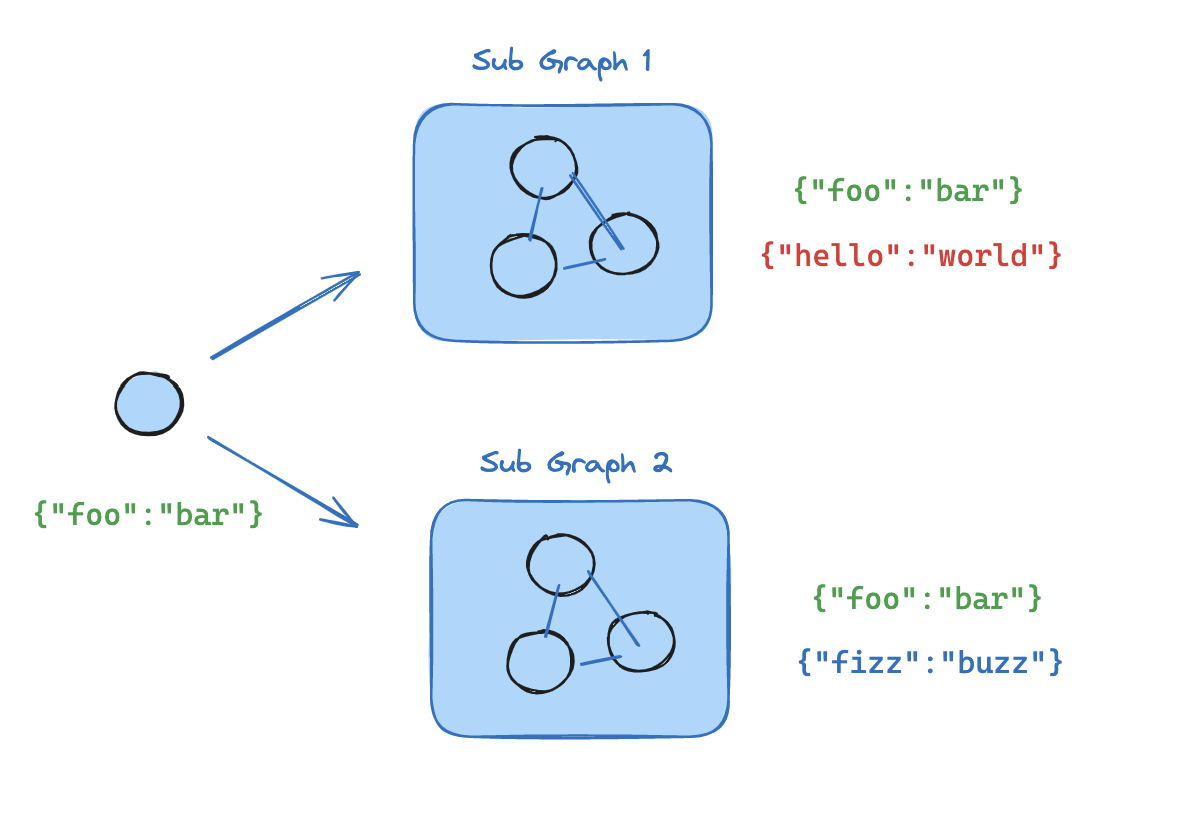
If your subgraph shares state keys with the parent graph, you can follow these steps to add it to your graph:
- Define the subgraph workflow (
subgraphBuilderin the example below) and compile it - Pass compiled subgraph to the
.addNodemethod when defining the parent graph workflow
import { StateGraph, StateSchema, START } from "@langchain/langgraph";
import * as z from "zod";

const State = new StateSchema({
  foo: z.string(),
});

// Subgraph
const subgraphBuilder = new StateGraph(State)
  .addNode("subgraphNode1", (state) => {
    return { foo: "hi! " + state.foo };
  })
  .addEdge(START, "subgraphNode1");

const subgraph = subgraphBuilder.compile();

// Parent graph
const builder = new StateGraph(State)
  .addNode("node1", subgraph)
  .addEdge(START, "node1");

const graph = builder.compile();
Full example: shared state schemas
import { StateGraph, StateSchema, START } from "@langchain/langgraph";
import * as z from "zod";

// Define subgraph
const SubgraphState = new StateSchema({
  foo: z.string(),    // [!code highlight]
  bar: z.string(),    // [!code highlight]
});

const subgraphBuilder = new StateGraph(SubgraphState)
  .addNode("subgraphNode1", (state) => {
    return { bar: "bar" };
  })
  .addNode("subgraphNode2", (state) => {
    // note that this node is using a state key ('bar') that is only available in the subgraph
    // and is sending update on the shared state key ('foo')
    return { foo: state.foo + state.bar };
  })
  .addEdge(START, "subgraphNode1")
  .addEdge("subgraphNode1", "subgraphNode2");

const subgraph = subgraphBuilder.compile();

// Define parent graph
const ParentState = new StateSchema({
  foo: z.string(),
});

const builder = new StateGraph(ParentState)
  .addNode("node1", (state) => {
    return { foo: "hi! " + state.foo };
  })
  .addNode("node2", subgraph)
  .addEdge(START, "node1")
  .addEdge("node1", "node2");

const graph = builder.compile();

const stream = await graph.streamEvents({ foo: "foo" }, { version: "v3" });
for await (const message of stream.messages) {
  for await (const token of message.text) {
    process.stdout.write(token);
  }
}- This key is shared with the parent graph state
- This key is private to the
SubgraphStateand is not visible to the parent graph
{ node1: { foo: 'hi! foo' } }
{ node2: { foo: 'hi! foobar' } }
Subgraph persistence
When you use a subgraph, you need to decide what happens to its internal data between calls. Consider a customer support bot that delegates to specialist subagents: should the "billing expert" subagent remember the customer's earlier questions, or start fresh each time it's called?
The checkpointer parameter on .compile() controls subgraph persistence:
| Mode | checkpointer= | Behavior |
|---|---|---|
| Per-invocation | None (default) | Each call starts fresh and inherits the parent's checkpointer to support interrupts and durable execution within a single call. |
| Per-thread | True | State accumulates across calls on the same thread. Each call picks up where the last one left off. |
| Stateless | False | No checkpointing at all—runs like a plain function call. No interrupts or durable execution. |
Per-invocation is the right choice for most applications, including multi-agent systems where subagents handle independent requests. Use per-thread when a subagent needs multi-turn conversation memory (for example, a research assistant that builds context over several exchanges).
Note
The parent graph must be compiled with a checkpointer for subgraph persistence features (interrupts, state inspection, per-thread memory) to work. See persistence.
Info
The examples below use LangChain's create_agent, which is a common way to build agents. create_agent produces a LangGraph graph under the hood, so all subgraph persistence concepts apply directly. If you're building with raw LangGraph StateGraph, the same patterns and configuration options apply—see the Graph API for details.
Stateful
Stateful subgraphs inherit the parent graph's checkpointer, which enables interrupts, persistence, and state inspection. The two stateful modes differ in how long state is retained.
Per-invocation (default)
Tip
This is the recommended mode for most applications, including multi-agent systems where subagents are invoked as tools. It supports interrupts, persistence, and parallel calls while keeping each invocation isolated.
Use per-invocation persistence when each call to the subgraph is independent and the subagent doesn't need to remember anything from previous calls. This is the most common pattern, especially for multi-agent systems where subagents handle one-off requests like "look up this customer's order" or "summarize this document."
Omit checkpointer or set it to None. Each call starts fresh, but within a single call the subgraph inherits the parent's checkpointer and can use interrupt() to pause and resume.
The following examples use two subagents (fruit expert, veggie expert) wrapped as tools for an outer agent:
import { createAgent, tool } from "langchain";
import { MemorySaver, Command, interrupt } from "@langchain/langgraph";
import * as z from "zod";

const fruitInfo = tool(
  (input) => `Info about ${input.fruitName}`,
  {
    name: "fruit_info",
    description: "Look up fruit info.",
    schema: z.object({ fruitName: z.string() }),
  }
);

const veggieInfo = tool(
  (input) => `Info about ${input.veggieName}`,
  {
    name: "veggie_info",
    description: "Look up veggie info.",
    schema: z.object({ veggieName: z.string() }),
  }
);

// Subagents - no checkpointer setting (inherits parent)
const fruitAgent = createAgent({
  model: "gpt-5.4-mini",
  tools: [fruitInfo],
  prompt: "You are a fruit expert. Use the fruit_info tool. Respond in one sentence.",
});

const veggieAgent = createAgent({
  model: "gpt-5.4-mini",
  tools: [veggieInfo],
  prompt: "You are a veggie expert. Use the veggie_info tool. Respond in one sentence.",
});

// Wrap subagents as tools for the outer agent
const askFruitExpert = tool(
  async (input) => {
    const response = await fruitAgent.invoke({
      messages: [{ role: "user", content: input.question }],
    });
    return response.messages[response.messages.length - 1].content;
  },
  {
    name: "ask_fruit_expert",
    description: "Ask the fruit expert. Use for ALL fruit questions.",
    schema: z.object({ question: z.string() }),
  }
);

const askVeggieExpert = tool(
  async (input) => {
    const response = await veggieAgent.invoke({
      messages: [{ role: "user", content: input.question }],
    });
    return response.messages[response.messages.length - 1].content;
  },
  {
    name: "ask_veggie_expert",
    description: "Ask the veggie expert. Use for ALL veggie questions.",
    schema: z.object({ question: z.string() }),
  }
);

// Outer agent with checkpointer
const agent = createAgent({
  model: "gpt-5.4-mini",
  tools: [askFruitExpert, askVeggieExpert],
  prompt:
    "You have two experts: ask_fruit_expert and ask_veggie_expert. " +
    "ALWAYS delegate questions to the appropriate expert.",
  checkpointer: new MemorySaver(),
});Each invocation can use interrupt() to pause and resume. Add interrupt() to a tool function to require user approval before proceeding:
const fruitInfo = tool(
  (input) => {
    interrupt("continue?");  // [!code highlight]
    return `Info about ${input.fruitName}`;
  },
  {
    name: "fruit_info",
    description: "Look up fruit info.",
    schema: z.object({ fruitName: z.string() }),
  }
);
const config = { configurable: { thread_id: "1" } };
// Invoke - the subagent's tool calls interrupt()
let response = await agent.invoke(
{ messages: [{ role: "user", content: "Tell me about apples" }] },
config,
);
// response contains __interrupt__
// Resume - approve the interrupt
response = await agent.invoke(new Command({ resume: true }), config); // [!code highlight]
// Subagent message count: 4Each invocation starts with a fresh subagent state. The subagent does not remember previous calls:
const config = { configurable: { thread_id: "1" } };

// First call
let response = await agent.invoke(
  { messages: [{ role: "user", content: "Tell me about apples" }] },
  config,
);
// Subagent message count: 4

// Second call - subagent starts fresh, no memory of apples
response = await agent.invoke(
  { messages: [{ role: "user", content: "Now tell me about bananas" }] },
  config,
);
// Subagent message count: 4 (still fresh!)
Multiple calls to the same subgraph work without conflicts, since each invocation gets its own checkpoint namespace:
const config = { configurable: { thread_id: "1" } };

// LLM calls ask_fruit_expert for both apples and bananas
const response = await agent.invoke(
  { messages: [{ role: "user", content: "Tell me about apples and bananas" }] },
  config,
);
// Subagent message count: 4 (apples - fresh)
// Subagent message count: 4 (bananas - fresh)
Per-thread
Use per-thread persistence when a subagent needs to remember previous interactions. For example, a research assistant that builds up context over several exchanges, or a coding assistant that tracks what files it has already edited. The subagent's conversation history and data accumulate across calls on the same thread. Each call picks up where the last one left off.
Compile with checkpointer=True to enable this behavior.
Warning
Per-thread subgraphs do not support parallel tool calls. When an LLM has access to a per-thread subagent as a tool, it may try to call that tool multiple times in parallel (for example, asking the fruit expert about apples and bananas simultaneously). This causes checkpoint conflicts because both calls write to the same namespace.
The examples below use LangChain's ToolCallLimitMiddleware to prevent this. If you're building with pure LangGraph StateGraph, you need to prevent parallel tool calls yourself—for example, by configuring your model to disable parallel tool calling or by adding logic to ensure the same subgraph is not invoked multiple times in parallel.
The following examples use a fruit expert subagent compiled with checkpointer=True:
import { createAgent, tool, toolCallLimitMiddleware } from "langchain";
import { MemorySaver, Command, interrupt } from "@langchain/langgraph";
import * as z from "zod";

const fruitInfo = tool(
  (input) => `Info about ${input.fruitName}`,
  {
    name: "fruit_info",
    description: "Look up fruit info.",
    schema: z.object({ fruitName: z.string() }),
  }
);

// Subagent with checkpointer=true for persistent state
const fruitAgent = createAgent({
  model: "gpt-5.4-mini",
  tools: [fruitInfo],
  prompt: "You are a fruit expert. Use the fruit_info tool. Respond in one sentence.",
  checkpointer: true,  // [!code highlight]
});

// Wrap subagent as a tool for the outer agent
const askFruitExpert = tool(
  async (input) => {
    const response = await fruitAgent.invoke({
      messages: [{ role: "user", content: input.question }],
    });
    return response.messages[response.messages.length - 1].content;
  },
  {
    name: "ask_fruit_expert",
    description: "Ask the fruit expert. Use for ALL fruit questions.",
    schema: z.object({ question: z.string() }),
  }
);

// Outer agent with checkpointer
// Use toolCallLimitMiddleware to prevent parallel calls to per-thread subagents,
// which would cause checkpoint conflicts.
const agent = createAgent({
  model: "gpt-5.4-mini",
  tools: [askFruitExpert],
  prompt: "You have a fruit expert. ALWAYS delegate fruit questions to ask_fruit_expert.",
  middleware: [  // [!code highlight]
    toolCallLimitMiddleware({ toolName: "ask_fruit_expert", runLimit: 1 }),  // [!code highlight]
  ],  // [!code highlight]
  checkpointer: new MemorySaver(),
});
Per-thread subagents support interrupt() just like per-invocation. Add interrupt() to a tool function to require user approval:
const fruitInfo = tool(
  (input) => {
    interrupt("continue?");  // [!code highlight]
    return `Info about ${input.fruitName}`;
  },
  {
    name: "fruit_info",
    description: "Look up fruit info.",
    schema: z.object({ fruitName: z.string() }),
  }
);
const config = { configurable: { thread_id: "1" } };
// Invoke - the subagent's tool calls interrupt()
let response = await agent.invoke(
{ messages: [{ role: "user", content: "Tell me about apples" }] },
config,
);
// response contains __interrupt__
// Resume - approve the interrupt
response = await agent.invoke(new Command({ resume: true }), config); // [!code highlight]
// Subagent message count: 4
State accumulates across invocations—the subagent remembers past conversations:
const config = { configurable: { thread_id: "1" } };

// First call
let response = await agent.invoke(
  { messages: [{ role: "user", content: "Tell me about apples" }] },
  config,
);
// Subagent message count: 4

// Second call - subagent REMEMBERS apples conversation
response = await agent.invoke(
  { messages: [{ role: "user", content: "Now tell me about bananas" }] },
  config,
);
// Subagent message count: 8 (accumulated!)
When you have multiple different per-thread subgraphs (for example, a fruit expert and a veggie expert), each one needs its own storage space so their checkpoints don't overwrite each other. This is called namespace isolation.
If you call subgraphs inside a node, LangGraph assigns namespaces based on call order (first call, second call, etc.). This means reordering your calls can mix up which subgraph loads which state. To avoid this, wrap each subagent in its own StateGraph with a unique node name—this gives each subgraph a stable, unique namespace:
import { StateGraph, StateSchema, MessagesValue, START } from "@langchain/langgraph";

function createSubAgent(model: string, { name, ...kwargs }: { name: string; [key: string]: any }) {
  const agent = createAgent({ model, name, ...kwargs });
  return new StateGraph(new StateSchema({ messages: MessagesValue }))
    .addNode(name, agent)  // unique name → stable namespace  // [!code highlight]
    .addEdge(START, name)
    .compile();
}

const fruitAgent = createSubAgent("gpt-5.4-mini", {
  name: "fruit_agent", tools: [fruitInfo], prompt: "...", checkpointer: true,
});
const veggieAgent = createSubAgent("gpt-5.4-mini", {
  name: "veggie_agent", tools: [veggieInfo], prompt: "...", checkpointer: true,
});
const config = { configurable: { thread_id: "1" } };

// First call - LLM calls both fruit and veggie experts
let response = await agent.invoke(
  { messages: [{ role: "user", content: "Tell me about cherries and broccoli" }] },
  config,
);
// Fruit subagent message count: 4
// Veggie subagent message count: 4

// Second call - both agents accumulate independently
response = await agent.invoke(
  { messages: [{ role: "user", content: "Now tell me about oranges and carrots" }] },
  config,
);
// Fruit subagent message count: 8 (remembers cherries!)
// Veggie subagent message count: 8 (remembers broccoli!)
Subgraphs added as nodes already get name-based namespaces automatically, so they don't need this wrapper.
Stateless
Use this when you want to run a subagent like a plain function call with no checkpointing overhead. The subgraph cannot pause/resume and does not benefit from durable execution. Compile with checkpointer=False.
Warning
Without checkpointing, the subgraph has no durable execution. If the process crashes mid-run, the subgraph cannot recover and must be re-run from the beginning.
const subgraphBuilder = new StateGraph(...);
const subgraph = subgraphBuilder.compile({ checkpointer: false });  // [!code highlight]
Checkpointer reference
Control subgraph persistence with the checkpointer parameter on .compile():
const subgraph = builder.compile({ checkpointer: false }); // or true, or null
| Feature | Per-invocation (default) | Per-thread | Stateless |
|---|---|---|---|
checkpointer= | None | True | False |
| Interrupts (HITL) | ✅ | ✅ | ❌ |
| Multi-turn memory | ❌ | ✅ | ❌ |
| Multiple calls (different subgraphs) | ✅ | ⚠️ | ✅ |
| Multiple calls (same subgraph) | ✅ | ❌ | ✅ |
| State inspection | ⚠️ | ✅ | ❌ |
- Interrupts (HITL): The subgraph can use interrupt() to pause execution and wait for user input, then resume where it left off.
- Multi-turn memory: The subgraph retains its state across multiple invocations within the same thread. Each call picks up where the last one left off rather than starting fresh.
- Multiple calls (different subgraphs): Multiple different subgraph instances can be invoked within a single node without checkpoint namespace conflicts.
- Multiple calls (same subgraph): The same subgraph instance can be invoked multiple times within a single node. With stateful persistence, these calls write to the same checkpoint namespace and conflict—use per-invocation persistence instead.
- State inspection: The subgraph's state is available via
get_state(config, subgraphs=True)for debugging and monitoring.
View subgraph state
When you enable persistence, you can inspect the subgraph state using the subgraphs option. With stateless checkpointing (checkpointer=False), no subgraph checkpoints are saved, so subgraph state is not available.
Note
Viewing subgraph state requires that LangGraph can statically discover the subgraph—i.e., it is added as a node or called inside a node. It does not work when a subgraph is called inside a tool function or other indirection (e.g., the subagents pattern). Interrupts still propagate to the top-level graph regardless of nesting.
Returns subgraph state for the current invocation only. Each invocation starts fresh.
import { StateGraph, StateSchema, START, MemorySaver, interrupt, Command } from "@langchain/langgraph";
import * as z from "zod";

const State = new StateSchema({
  foo: z.string(),
});

// Subgraph
const subgraphBuilder = new StateGraph(State)
  .addNode("subgraphNode1", (state) => {
    const value = interrupt("Provide value:");
    return { foo: state.foo + value };
  })
  .addEdge(START, "subgraphNode1");

const subgraph = subgraphBuilder.compile();  // inherits parent checkpointer

// Parent graph
const builder = new StateGraph(State)
  .addNode("node1", subgraph)
  .addEdge(START, "node1");

const checkpointer = new MemorySaver();
const graph = builder.compile({ checkpointer });

const config = { configurable: { thread_id: "1" } };

await graph.invoke({ foo: "" }, config);

// View subgraph state for the current invocation
const subgraphState = (await graph.getState(config, { subgraphs: true })).tasks[0].state;  // [!code highlight]

// Resume the subgraph
await graph.invoke(new Command({ resume: "bar" }), config);
Returns accumulated subgraph state across all invocations on this thread.
import { StateGraph, StateSchema, MessagesValue, START, MemorySaver } from "@langchain/langgraph";

// Subgraph with its own persistent state
const SubgraphState = new StateSchema({
  messages: MessagesValue,
});

const subgraphBuilder = new StateGraph(SubgraphState);
// ... add nodes and edges
const subgraph = subgraphBuilder.compile({ checkpointer: true });  // [!code highlight]

// Parent graph
const builder = new StateGraph(SubgraphState)
  .addNode("agent", subgraph)
  .addEdge(START, "agent");

const checkpointer = new MemorySaver();
const graph = builder.compile({ checkpointer });

const config = { configurable: { thread_id: "1" } };

await graph.invoke({ messages: [{ role: "user", content: "hi" }] }, config);
await graph.invoke({ messages: [{ role: "user", content: "what did I say?" }] }, config);

// View accumulated subgraph state (includes messages from both invocations)
const subgraphState = (await graph.getState(config, { subgraphs: true })).tasks[0].state;  // [!code highlight]
Stream subgraph outputs
To observe nested graph executions, we recommend event streaming: the stream.subgraphs projection discovers each nested run and exposes its path, messages, and values without parsing namespace strings.
const stream = await graph.streamEvents(
  { foo: "foo" },
  {
    subgraphs: true,   // [!code highlight]
    version: "v3",
  }
);
for await (const snapshot of stream.values) {
  console.log(snapshot);
}
- Set
subgraphs: trueto stream outputs from subgraphs.
Stream from subgraphs
import { StateGraph, StateSchema, START } from "@langchain/langgraph";
import * as z from "zod";

// Define subgraph
const SubgraphState = new StateSchema({
  foo: z.string(),
  bar: z.string(),
});

const subgraphBuilder = new StateGraph(SubgraphState)
  .addNode("subgraphNode1", (state) => {
    return { bar: "bar" };
  })
  .addNode("subgraphNode2", (state) => {
    // note that this node is using a state key ('bar') that is only available in the subgraph
    // and is sending update on the shared state key ('foo')
    return { foo: state.foo + state.bar };
  })
  .addEdge(START, "subgraphNode1")
  .addEdge("subgraphNode1", "subgraphNode2");

const subgraph = subgraphBuilder.compile();

// Define parent graph
const ParentState = new StateSchema({
  foo: z.string(),
});

const builder = new StateGraph(ParentState)
  .addNode("node1", (state) => {
    return { foo: "hi! " + state.foo };
  })
  .addNode("node2", subgraph)
  .addEdge(START, "node1")
  .addEdge("node1", "node2");

const graph = builder.compile();

const stream = await graph.streamEvents(
  { foo: "foo" },
  {
    subgraphs: true,   // [!code highlight]
    version: "v3",
  }
);
for await (const snapshot of stream.values) {
  console.log(snapshot);
}
- Set
subgraphs: trueto stream outputs from subgraphs.
[[], { node1: { foo: 'hi! foo' } }]
[['node2:e58e5673-a661-ebb0-70d4-e298a7fc28b7'], { subgraphNode1: { bar: 'bar' } }]
[['node2:e58e5673-a661-ebb0-70d4-e298a7fc28b7'], { subgraphNode2: { foo: 'hi! foobar' } }]
[[], { node2: { foo: 'hi! foobar' } }]