本页还没有译文
本页 217 段还没译成日本語,下面显示的是英文原文。ChatOpenAI integration
还没翻译译自英文(docs.langchain.com)本页 217 段都还没译
You can find information about OpenAI's latest models, their costs, context windows, and supported input types in the OpenAI Platform docs.
Tip
API Reference
For detailed documentation of all features and configuration options, head to the ChatOpenAI API reference.
Warning
API scope
ChatOpenAI targets official OpenAI API specifications only. Non-standard response fields from third-party providers (e.g., reasoning_content, reasoning, reasoning_details) are not extracted or preserved. If you are using a provider that extends the Chat Completions or Responses formats, such as OpenRouter, LiteLLM, vLLM, or DeepSeek, use a provider-specific package instead. See Chat Completions API compatibility for details.
Overview
Integration details
| Class | Package | Serializable | JS/TS Support | Downloads | Latest Version |
|---|---|---|---|---|---|
ChatOpenAI | langchain-openai | beta | ✅ (npm) |  |  |
Model features
| Tool calling | Structured output | Image input | Audio input | Video input | Token-level streaming | Native async | Token usage | Logprobs |
|---|---|---|---|---|---|---|---|---|
| ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ✅ |
Setup
To access OpenAI models you'll need to install the langchain-openai integration package and acquire an OpenAI Platform API key.
Installation
pip install -U langchain-openaiuv add langchain-openaiCredentials
Head to the OpenAI Platform to sign up and generate an API key. Once you've done this set the OPENAI_API_KEY environment variable in your environment:
import getpass
import os

if not os.environ.get("OPENAI_API_KEY"):
    os.environ["OPENAI_API_KEY"] = getpass.getpass("Enter your OpenAI API key: ")
If you're routing requests through a proxy or service emulator, you can set the base URL via env var instead of passing base_url. Resolution order (first match wins):
- Explicit
base_url(oropenai_api_base) kwarg. OPENAI_API_BASE— read by LangChain at init.OPENAI_BASE_URL— read by the underlyingopenaiSDK client. LangChain also inspects this to decide whether to default-enablestream_usage; when set, the default is left off because many non-OpenAI endpoints don't support streaming token usage.
If you want to get automated tracing of your model calls you can also set your LangSmith API key:
os.environ["LANGSMITH_API_KEY"] = getpass.getpass("Enter your LangSmith API key: ")
os.environ["LANGSMITH_TRACING"] = "true"
Instantiation
Now we can instantiate our model object and generate responses:
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(
    model="gpt-5-nano",
    # stream_usage=True,
    # temperature=None,
    # max_tokens=None,
    # timeout=None,
    # reasoning_effort="low",
    # max_retries=2,
    # api_key="...",  # If you prefer to pass api key in directly
    # base_url="...",
    # organization="...",
    # other params...
)
See the ChatOpenAI API Reference for the full set of available model parameters.
Note
Token parameter deprecation
OpenAI deprecated max_tokens in favor of max_completion_tokens in September 2024. While max_tokens is still supported for backwards compatibility, it's automatically converted to max_completion_tokens internally.
Invocation
messages = [
    (
        "system",
        "You are a helpful assistant that translates English to French. Translate the user sentence.",
    ),
    ("human", "I love programming."),
]
ai_msg = llm.invoke(messages)
ai_msg
AIMessage(content="J'adore la programmation.", additional_kwargs={'refusal': None}, response_metadata={'token_usage': {'completion_tokens': 5, 'prompt_tokens': 31, 'total_tokens': 36}, 'model_name': 'gpt-4o-2024-05-13', 'system_fingerprint': 'fp_3aa7262c27', 'finish_reason': 'stop', 'logprobs': None}, id='run-63219b22-03e3-4561-8cc4-78b7c7c3a3ca-0', usage_metadata={'input_tokens': 31, 'output_tokens': 5, 'total_tokens': 36})print(ai_msg.text)J'adore la programmation.Streaming usage metadata
OpenAI's Chat Completions API does not stream token usage statistics by default (see the OpenAI API reference for stream options).
To recover token counts when streaming with ChatOpenAI or AzureChatOpenAI, set stream_usage=True as an initialization parameter or on invocation:
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(model="gpt-5.4-mini", stream_usage=True)  # [!code highlight]
Using with Azure OpenAI
Info
Azure OpenAI v1 API support
As of langchain-openai>=1.0.1, ChatOpenAI can be used directly with Azure OpenAI endpoints using the new v1 API. This provides a unified way to use OpenAI models whether hosted on OpenAI or Azure.
For the traditional Azure-specific implementation, continue to use AzureChatOpenAI.
Using Azure OpenAI v1 API with API Key
To use ChatOpenAI with Azure OpenAI, set the base_url to your Azure endpoint with /openai/v1/ appended:
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(
    model="gpt-5-mini",  # Your Azure deployment name
    base_url="https://{your-resource-name}.openai.azure.com/openai/v1/",
    api_key="your-azure-api-key"
)

response = llm.invoke("Hello, how are you?")
print(response.content)
Using Azure OpenAI with Microsoft Entra ID
The v1 API adds native support for Microsoft Entra ID (formerly Azure AD) authentication with automatic token refresh. Pass a token provider callable to the api_key parameter:
from azure.identity import DefaultAzureCredential, get_bearer_token_provider
from langchain_openai import ChatOpenAI

# Create a token provider that handles automatic refresh
token_provider = get_bearer_token_provider(
    DefaultAzureCredential(),
    "https://cognitiveservices.azure.com/.default"
)

llm = ChatOpenAI(
    model="gpt-5-mini",  # Your Azure deployment name
    base_url="https://{your-resource-name}.openai.azure.com/openai/v1/",
    api_key=token_provider  # Callable that handles token refresh
)

# Use the model as normal
messages = [
    ("system", "You are a helpful assistant."),
    ("human", "Translate 'I love programming' to French.")
]
response = llm.invoke(messages)
print(response.content)
The token provider is a callable that automatically retrieves and refreshes authentication tokens, eliminating the need to manually manage token expiration.
Tip
Installation requirements
To use Microsoft Entra ID authentication, install the Azure Identity library:
pip install azure-identityYou can also pass a token provider callable to the api_key parameter when using
asynchronous functions. You must import DefaultAzureCredential from azure.identity.aio:
from azure.identity.aio import DefaultAzureCredential
from langchain_openai import ChatOpenAI

credential = DefaultAzureCredential()

llm_async = ChatOpenAI(
    model="gpt-5-nano",
    api_key=credential
)

# Use async methods when using async callable
response = await llm_async.ainvoke("Hello!")
Note
When using an async callable for the API key, you must use async methods (ainvoke, astream, etc.). Sync methods will raise an error.
Tool calling
OpenAI has a tool calling (we use "tool calling" and "function calling" interchangeably here) API that lets you describe tools and their arguments, and have the model return a JSON object with a tool to invoke and the inputs to that tool. tool-calling is extremely useful for building tool-using chains and agents, and for getting structured outputs from models more generally.
Bind tools
With ChatOpenAI.bind_tools, we can easily pass in Pydantic classes, dict schemas, LangChain tools, or even functions as tools to the model. Under the hood these are converted to an OpenAI tool schemas, which looks like:
{
    "name": "...",
    "description": "...",
    "parameters": {...}  # JSONSchema
}
...and are passed in every model invocation.
from pydantic import BaseModel, Field


class GetWeather(BaseModel):
    """Get the current weather in a given location"""

    location: str = Field(description="The city and state, e.g. San Francisco, CA")


llm_with_tools = llm.bind_tools([GetWeather])
ai_msg = llm_with_tools.invoke(
"what is the weather like in San Francisco",
)
ai_msgAIMessage(content='', additional_kwargs={'refusal': None}, response_metadata={'token_usage': {'completion_tokens': 17, 'prompt_tokens': 68, 'total_tokens': 85}, 'model_name': 'gpt-4o-2024-05-13', 'system_fingerprint': 'fp_3aa7262c27', 'finish_reason': 'tool_calls', 'logprobs': None}, id='run-1617c9b2-dda5-4120-996b-0333ed5992e2-0', tool_calls=[{'name': 'GetWeather', 'args': {'location': 'San Francisco, CA'}, 'id': 'call_o9udf3EVOWiV4Iupktpbpofk', 'type': 'tool_call'}], usage_metadata={'input_tokens': 68, 'output_tokens': 17, 'total_tokens': 85})Strict mode
Info
Requires langchain-openai>=0.1.21
As of Aug 6, 2024, OpenAI supports a strict argument when calling tools that will enforce that the tool argument schema is respected by the model. See more.
Note
If strict=True the tool definition will also be validated, and a subset of JSON schema are accepted. Crucially, schema cannot have optional args (those with default values).
Read the full docs on what types of schema are supported.
llm_with_tools = llm.bind_tools([GetWeather], strict=True)
ai_msg = llm_with_tools.invoke(
    "what is the weather like in San Francisco",
)
ai_msg
AIMessage(content='', additional_kwargs={'tool_calls': [{'id': 'call_jUqhd8wzAIzInTJl72Rla8ht', 'function': {'arguments': '{"location":"San Francisco, CA"}', 'name': 'GetWeather'}, 'type': 'function'}], 'refusal': None}, response_metadata={'token_usage': {'completion_tokens': 17, 'prompt_tokens': 68, 'total_tokens': 85}, 'model_name': 'gpt-4o-2024-05-13', 'system_fingerprint': 'fp_3aa7262c27', 'finish_reason': 'tool_calls', 'logprobs': None}, id='run-5e3356a9-132d-4623-8e73-dd5a898cf4a6-0', tool_calls=[{'name': 'GetWeather', 'args': {'location': 'San Francisco, CA'}, 'id': 'call_jUqhd8wzAIzInTJl72Rla8ht', 'type': 'tool_call'}], usage_metadata={'input_tokens': 68, 'output_tokens': 17, 'total_tokens': 85})Tool calls
Notice that the AIMessage has a tool_calls attribute. This contains in a standardized ToolCall format that is model-provider agnostic.
ai_msg.tool_calls[{'name': 'GetWeather',
'args': {'location': 'San Francisco, CA'},
'id': 'call_jUqhd8wzAIzInTJl72Rla8ht',
'type': 'tool_call'}]For more on binding tools and tool call outputs, head to the tool calling docs.
Async tools
Async tool calling lets the model continue working after issuing a tool call, without waiting for the result. When using the Responses API, ChatOpenAI supports this by passing extras={"async": True} to @tool:
from langchain.tools import tool

@tool(extras={"async": True})  # [!code highlight]
def lookup_price(sku: str) -> str:
    """Look up the price of a product."""
    return "1200"
Note
Async tools are only supported via the Responses API (use_responses_api=True). The async flag is round-tripped through the message history so that prompt-cache prefixes remain intact across turns.
Custom tools
Info
Requires langchain-openai>=0.3.29
Custom tools support tools with arbitrary string inputs. They can be particularly useful when you expect your string arguments to be long or complex.
from langchain_openai import ChatOpenAI, custom_tool
from langchain.agents import create_agent


@custom_tool
def execute_code(code: str) -> str:
    """Execute python code."""
    return "27"


llm = ChatOpenAI(model="gpt-5.5", use_responses_api=True)

agent = create_agent(llm, [execute_code])

input_message = {"role": "user", "content": "Use the tool to calculate 3^3."}
stream = agent.stream_events(
    {"messages": [input_message]},
    version="v3",
)
for snapshot in stream.values:
    snapshot["messages"][-1].pretty_print()
================================ Human Message =================================
Use the tool to calculate 3^3.
================================== Ai Message ==================================
[{'id': 'rs_68b7336cb72081a080da70bf5e980e4e0d6082d28f91357a', 'summary': [], 'type': 'reasoning'}, {'call_id': 'call_qyKsJ4XlGRudbIJDrXVA2nQa', 'input': 'print(3**3)', 'name': 'execute_code', 'type': 'custom_tool_call', 'id': 'ctc_68b7336f718481a0b39584cd35fbaa5d0d6082d28f91357a', 'status': 'completed'}]
Tool Calls:
execute_code (call_qyKsJ4XlGRudbIJDrXVA2nQa)
Call ID: call_qyKsJ4XlGRudbIJDrXVA2nQa
Args:
__arg1: print(3**3)
================================= Tool Message =================================
Name: execute_code
[{'type': 'custom_tool_call_output', 'output': '27'}]
================================== Ai Message ==================================
[{'type': 'text', 'text': '27', 'annotations': [], 'id': 'msg_68b73371e9e081a0927f54f88f2cd7a20d6082d28f91357a'}]Context-free grammars
OpenAI supports the specification of a context-free grammar for custom tool inputs in lark or regex format. See OpenAI docs for details. The format parameter can be passed into @custom_tool as shown below:
from langchain_openai import ChatOpenAI, custom_tool
from langchain.agents import create_agent


grammar = """
start: expr
expr: term (SP ADD SP term)* -> add
| term
term: factor (SP MUL SP factor)* -> mul
| factor
factor: INT
SP: " "
ADD: "+"
MUL: "*"
%import common.INT
"""

format_ = {"type": "grammar", "syntax": "lark", "definition": grammar}


@custom_tool(format=format_)  # [!code highlight]
def do_math(input_string: str) -> str:
    """Do a mathematical operation."""
    return "27"


llm = ChatOpenAI(model="gpt-5.5", use_responses_api=True)

agent = create_agent(llm, [do_math])

input_message = {"role": "user", "content": "Use the tool to calculate 3^3."}
stream = agent.stream_events(
    {"messages": [input_message]},
    version="v3",
)
for snapshot in stream.values:
    snapshot["messages"][-1].pretty_print()
================================ Human Message =================================
Use the tool to calculate 3^3.
================================== Ai Message ==================================
[{'id': 'rs_68b733f066a48194a41001c0cc1081760811f11b6f4bae47', 'summary': [], 'type': 'reasoning'}, {'call_id': 'call_7hTYtlTj9NgWyw8AQGqETtV9', 'input': '3 * 3 * 3', 'name': 'do_math', 'type': 'custom_tool_call', 'id': 'ctc_68b733f3a0a08194968b8338d33ad89f0811f11b6f4bae47', 'status': 'completed'}]
Tool Calls:
do_math (call_7hTYtlTj9NgWyw8AQGqETtV9)
Call ID: call_7hTYtlTj9NgWyw8AQGqETtV9
Args:
__arg1: 3 * 3 * 3
================================= Tool Message =================================
Name: do_math
[{'type': 'custom_tool_call_output', 'output': '27'}]
================================== Ai Message ==================================
[{'type': 'text', 'text': '27', 'annotations': [], 'id': 'msg_68b733f4bb008194937130796372bd0f0811f11b6f4bae47'}]Structured output
OpenAI supports a native structured output feature, which guarantees that its responses adhere to a given schema.
You can access this feature in individual model calls, or by specifying the response format of a LangChain agent. See below for examples.
Individual model calls
Use the with_structured_output method to generate a structured model response. Specify method="json_schema" to enable OpenAI's native structured output feature; otherwise the method defaults to using function calling.
from langchain_openai import ChatOpenAI
from pydantic import BaseModel, Field

llm = ChatOpenAI(model="gpt-5.5")

class Movie(BaseModel):
    """A movie with details."""
    title: str = Field(description="The title of the movie")
    year: int = Field(description="The year the movie was released")
    director: str = Field(description="The director of the movie")
    rating: float = Field(description="The movie's rating out of 10")

structured_llm = llm.with_structured_output(Movie, method="json_schema")  # [!code highlight]
response = structured_llm.invoke("Provide details about the movie Inception")
responseMovie(title='Inception', year=2010, director='Christopher Nolan', rating=8.8)Agent response format
Specify response_format with ProviderStrategy to engage OpenAI's structured output feature when generating its final response.
from langchain.agents import create_agent
from langchain.agents.structured_output import ProviderStrategy
from pydantic import BaseModel

class Weather(BaseModel):
    temperature: float
    condition: str

def weather_tool(location: str) -> str:
    """Get the weather at a location."""
    return "Sunny and 75 degrees F."

agent = create_agent(
    model="openai:gpt-5.5",
    tools=[weather_tool],
    response_format=ProviderStrategy(Weather),  # [!code highlight]
)

result = agent.invoke({
    "messages": [{"role": "user", "content": "What's the weather in SF?"}]
})

result["structured_response"]Weather(temperature=75.0, condition='Sunny')Structured output with tool calls
OpenAI's structured output feature can be used simultaneously with tool-calling. The model will either generate tool calls or a response adhering to a desired schema. See example below:
from langchain_openai import ChatOpenAI
from pydantic import BaseModel


def get_weather(location: str) -> None:
    """Get weather at a location."""
    return "It's sunny."


class OutputSchema(BaseModel):
    """Schema for response."""

    answer: str
    justification: str


llm = ChatOpenAI(model="gpt-5.5")

structured_llm = llm.bind_tools(
    [get_weather],
    response_format=OutputSchema,
    strict=True,
)

# Response contains tool calls:
tool_call_response = structured_llm.invoke("What is the weather in SF?")

# structured_response.additional_kwargs["parsed"] contains parsed output
structured_response = structured_llm.invoke(
    "What weighs more, a pound of feathers or a pound of gold?"
)
Responses API
Info
Requires langchain-openai>=0.3.9
OpenAI supports a Responses API that is oriented toward building agentic applications. It includes a suite of built-in tools, including web and file search. It also supports management of conversation state, allowing you to continue a conversational thread without explicitly passing in previous messages, as well as the output from reasoning processes.
ChatOpenAI will route to the Responses API if one of these features is used. You can also specify use_responses_api=True when instantiating ChatOpenAI.
Web search
To trigger a web search, pass {"type": "web_search"} to the model as you would another tool.
Tip
You can also pass built-in tools as invocation params:
llm.invoke("...", tools=[{"type": "web_search"}])from langchain_openai import ChatOpenAI
llm = ChatOpenAI(model="gpt-5.4-mini")
tool = {"type": "web_search"}
llm_with_tools = llm.bind_tools([tool])
response = llm_with_tools.invoke("What was a positive news story from today?")Note that the response includes structured content blocks that include both the text of the response and OpenAI annotations citing its sources. The output message will also contain information from any tool invocations:
response.content_blocks[{'type': 'server_tool_call',
'name': 'web_search',
'args': {'query': 'positive news stories today', 'type': 'search'},
'id': 'ws_68cd6f8d72e4819591dab080f4b0c340080067ad5ea8144a'},
{'type': 'server_tool_result',
'tool_call_id': 'ws_68cd6f8d72e4819591dab080f4b0c340080067ad5ea8144a',
'status': 'success'},
{'type': 'text',
'text': 'Here are some positive news stories from today...',
'annotations': [{'end_index': 410,
'start_index': 337,
'title': 'Positive News | Real Stories. Real Positive Impact',
'type': 'citation',
'url': 'https://www.positivenews.press/?utm_source=openai'},
{'end_index': 969,
'start_index': 798,
'title': "From Green Innovation to Community Triumphs: Uplifting US Stories Lighting Up September 2025 | That's Great News",
'type': 'citation',
'url': 'https://info.thatsgreatnews.com/from-green-innovation-to-community-triumphs-uplifting-us-stories-lighting-up-september-2025/?utm_source=openai'},
'id': 'msg_68cd6f8e8d448195a807b89f483a1277080067ad5ea8144a'}]
Tip
You can recover just the text content of the response as a string by using response.text. For example, to stream response text:
stream = llm_with_tools.stream_events("...", version="v3")
for token in stream.text:
    print(token, end="|")
See the streaming guide for more detail.
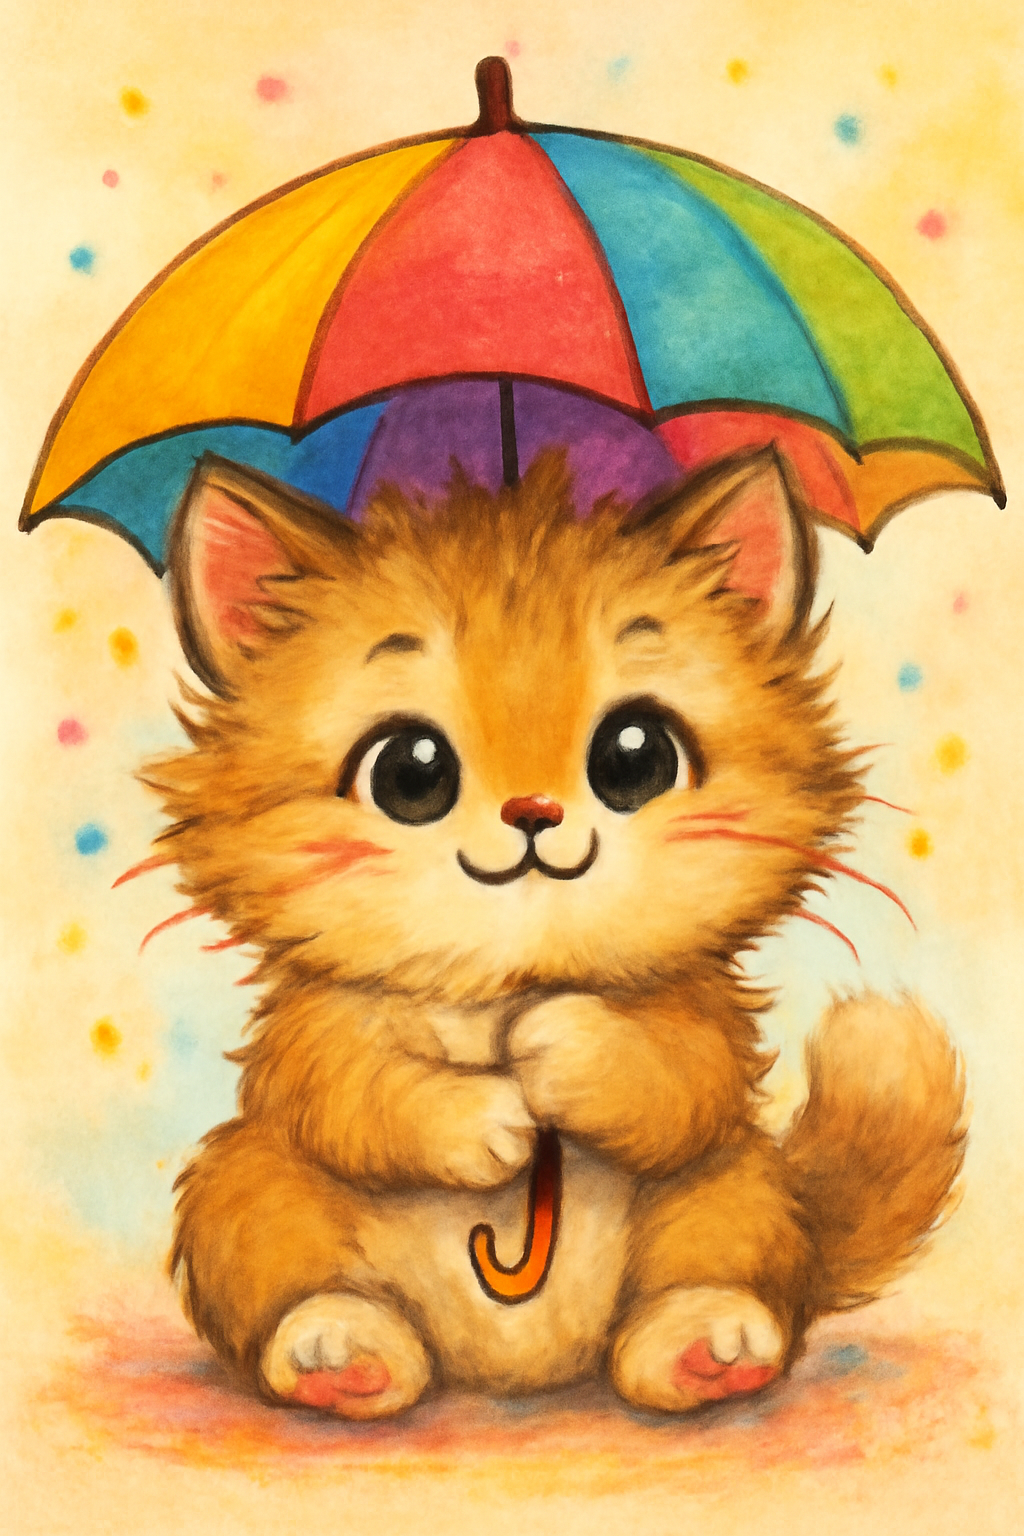
Image generation
Info
Requires langchain-openai>=0.3.19
To trigger an image generation, pass {"type": "image_generation"} to the model as you would another tool.
Tip
You can also pass built-in tools as invocation params:
llm.invoke("...", tools=[{"type": "image_generation"}])from langchain_openai import ChatOpenAI
llm = ChatOpenAI(model="gpt-5.4-mini")
tool = {"type": "image_generation", "quality": "low"}
llm_with_tools = llm.bind_tools([tool])
ai_message = llm_with_tools.invoke(
"Draw a picture of a cute fuzzy cat with an umbrella"
)
import base64

from IPython.display import Image

image = next(
    item for item in ai_message.content_blocks if item["type"] == "image"
)
Image(base64.b64decode(image["base64"]), width=200)
File search
To trigger a file search, pass a file search tool to the model as you would another tool. You will need to populate an OpenAI-managed vector store and include the vector store ID in the tool definition. See OpenAI documentation for more detail.
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(
    model="gpt-5.4-mini",
    include=["file_search_call.results"],  # optionally include search results
)

openai_vector_store_ids = [
    "vs_...",  # your IDs here
]

tool = {
    "type": "file_search",
    "vector_store_ids": openai_vector_store_ids,
}
llm_with_tools = llm.bind_tools([tool])

response = llm_with_tools.invoke("What is deep research by OpenAI?")
print(response.text)
Deep Research by OpenAI is...As with web search, the response will include content blocks with citations:
[block["type"] for block in response.content_blocks]
['server_tool_call', 'server_tool_result', 'text']
text_block = next(block for block in response.content_blocks if block["type"] == "text")

text_block["annotations"][:2]
[{'type': 'citation',
  'title': 'deep_research_blog.pdf',
  'extras': {'file_id': 'file-3UzgX7jcC8Dt9ZAFzywg5k', 'index': 2712}},
 {'type': 'citation',
  'title': 'deep_research_blog.pdf',
  'extras': {'file_id': 'file-3UzgX7jcC8Dt9ZAFzywg5k', 'index': 2712}}]
It will also include information from the built-in tool invocations:
response.content_blocks[0]
{'type': 'server_tool_call',
 'name': 'file_search',
 'id': 'fs_68cd704c191c81959281b3b2ec6b139908f8f7fb31b1123c',
 'args': {'queries': ['deep research by OpenAI']}}
Tool search
Info
Requires langchain-openai>=1.1.11
OpenAI supports a tool search feature allowing models to search for and load tools into its context as needed. OpenAI injects the retrieved tool definitions at the end of the active context to preserve its cache.
To engage tool search, mark tools with @tool(extras={"defer_loading": True}) and add OpenAI's search tool to available tools. See below for examples.
Server-side tool search
OpenAI can search across available tools and return the loaded tool (together with a tool call if appropriate) in the same response:
@tool(extras={"defer_loading": True})  # [!code highlight]
def get_weather(location: str) -> str:
    """Get the current weather for a location."""
    return f"The weather in {location} is sunny and 72°F"

@tool(extras={"defer_loading": True})  # [!code highlight]
def get_recipe(query: str) -> None:
    """Get a recipe for chicken soup."""

model = ChatOpenAI(model="gpt-5.5", use_responses_api=True)

agent = create_agent(
    model=model,
    tools=[
        get_weather,
        get_recipe,
        {"type": "tool_search"}  # [!code highlight]
    ],
)
input_message = {"role": "user", "content": "What's the weather in San Francisco?"}
result = agent.invoke({"messages": [input_message]})

for message in result["messages"]:
    message.pretty_print()
================================ Human Message =================================

What's the weather in San Francisco?
================================== Ai Message ==================================

[
  {
    "id": "tsc_0667642bae2ae6c70069ad6cb31f0c819c838b18b0e1cf1279",
    "arguments": {
      "paths": [
        "get_weather"
      ]
    },
    "execution": "server",
    "status": "completed",
    "type": "tool_search_call"
  },
  {
    "id": "tso_0667642bae2ae6c70069ad6cb339dc819c9bbc05cb432f347e",
    "execution": "server",
    "status": "completed",
    "tools": [
      {
        "name": "get_weather",
        "parameters": {
          "properties": {
            "location": {
              "type": "string"
            }
          },
          "required": [
            "location"
          ],
          "type": "object",
          "additionalProperties": false
        },
        "strict": true,
        "type": "function",
        "defer_loading": true,
        "description": "Get the current weather for a location."
      }
    ],
    "type": "tool_search_output"
  },
  {
    "arguments": "{\"location\":\"San Francisco\"}",
    "call_id": "call_nwy9NDI24fTe8qESIRqZGtYm",
    "name": "get_weather",
    "type": "function_call",
    "id": "fc_0667642bae2ae6c70069ad6cb37adc819cbc55cde85e111e32",
    "namespace": "get_weather",
    "status": "completed"
  }
]
Tool Calls:
  get_weather (call_nwy9NDI24fTe8qESIRqZGtYm)
 Call ID: call_nwy9NDI24fTe8qESIRqZGtYm
  Args:
    location: San Francisco
================================= Tool Message =================================
Name: get_weather

The weather in San Francisco is sunny and 72°F
================================== Ai Message ==================================

[
  {
    "type": "text",
    "text": "It\u2019s currently sunny and 72\u00b0F in San Francisco.",
    "annotations": [],
    "id": "msg_0667642bae2ae6c70069ad6cb4829c819c8e26bc7ccc68dcd7"
  }
]
Client-executed tool search
For full control of the underlying tool search process, you can specify "execution": "client" in the search tool definition. If the model elects to search for a tool, it will include a tool_search_call block in its response. You can then supply a tool_search_output block that includes the tool definition.
The following example shows how you can orchestrate this using custom middleware. The example implements a callable defining the search logic. The middleware then includes:
- An
after_modelhook to check fortool_search_callblocks and invoke our callable - A
wrap_tool_callhook for runtime tool registration
@tool
def get_weather(location: str) -> str:
    """Get the current weather for a location."""
    return f"The weather in {location} is sunny and 72°F"

# Implement a callable that returns a tool definition
def search_tools(goal: str) -> list[dict]:
    """Search for available tools to help answer the question."""
    # Arbitrary logic here
    return [
        {
            "type": "function",
            "defer_loading": True,
            **convert_to_openai_tool(get_weather)["function"],
        }
    ]

tool_search_schema = convert_to_openai_tool(search_tools, strict=True)
tool_search_config: dict = {
    "type": "tool_search",
    "execution": "client",
    "description": tool_search_schema["function"]["description"],
    "parameters": tool_search_schema["function"]["parameters"],
}

# Implement middleware to invoke the callable and register the tool.
class ClientToolSearchMiddleware(AgentMiddleware):

    @hook_config(can_jump_to=["model"])
    def after_model(self, state: AgentState, runtime: Any) -> dict[str, Any] | None:
        last_message = state["messages"][-1]
        if not isinstance(last_message, AIMessage):
            return None
        for block in last_message.content:
            if isinstance(block, dict) and block.get("type") == "tool_search_call":
                call_id = block.get("call_id")
                args = block.get("arguments", {})
                goal = args.get("goal", "") if isinstance(args, dict) else ""
                loaded_tools = search_tools(goal)
                tool_search_output = {
                    "type": "tool_search_output",
                    "execution": "client",
                    "call_id": call_id,
                    "status": "completed",
                    "tools": loaded_tools,
                }
                return {
                    "messages": [HumanMessage(content=[tool_search_output])],
                    "jump_to": "model",
                }
        return None

    def wrap_tool_call(
        self,
        request: ToolCallRequest,
        handler: Any,
    ) -> Any:
        if request.tool_call["name"] == "get_weather":
            return handler(request.override(tool=get_weather))
        return handler(request)

llm = ChatOpenAI(model="gpt-5.5", use_responses_api=True)

agent = create_agent(
    model=llm,
    tools=[tool_search_config],
    middleware=[ClientToolSearchMiddleware()],
)

result = agent.invoke(
    {"messages": [HumanMessage("What's the weather in San Francisco?")]}
)

for message in result["messages"]:
    message.pretty_print()
================================ Human Message =================================

What's the weather in San Francisco?
================================== Ai Message ==================================

[
  {
    "id": "tsc_0311ca847e392d540069acdd40394c8196a99345e2992eb657",
    "arguments": {
      "goal": "Find available tool(s) or weather capability to get current weather for San Francisco."
    },
    "call_id": "call_EcvKsh3r9IamaBW4Zz9r7RiK",
    "execution": "client",
    "status": "completed",
    "type": "tool_search_call"
  }
]
================================ Human Message =================================

[
  {
    "type": "tool_search_output",
    "execution": "client",
    "call_id": "call_EcvKsh3r9IamaBW4Zz9r7RiK",
    "status": "completed",
    "tools": [
      {
        "type": "function",
        "defer_loading": true,
        "name": "get_weather",
        "description": "Get the current weather for a location.",
        "parameters": {
          "properties": {
            "location": {
              "type": "string"
            }
          },
          "required": [
            "location"
          ],
          "type": "object"
        }
      }
    ]
  }
]
================================== Ai Message ==================================

[
  {
    "arguments": "{\"location\":\"San Francisco\"}",
    "call_id": "call_wH09dZpqDoVtpeu7uBdvY91l",
    "name": "get_weather",
    "type": "function_call",
    "id": "fc_0311ca847e392d540069acdd41502881968b29d96840633746",
    "namespace": "get_weather",
    "status": "completed"
  }
]
Tool Calls:
  get_weather (call_wH09dZpqDoVtpeu7uBdvY91l)
 Call ID: call_wH09dZpqDoVtpeu7uBdvY91l
  Args:
    location: San Francisco
================================= Tool Message =================================
Name: get_weather

The weather in San Francisco is sunny and 72°F
================================== Ai Message ==================================

[
  {
    "type": "text",
    "text": "San Francisco is sunny and 72\u00b0F.",
    "annotations": [],
    "id": "msg_0311ca847e392d540069acdd420b648196a603306f5546fabd"
  }
]
To add tools at a specific point in the conversation without tool search, see Add tools mid-conversation.
Computer use
ChatOpenAI supports the "computer-use-preview" model, which is a specialized model for the built-in computer use tool. To enable, pass a computer use tool as you would pass another tool.
Currently, tool outputs for computer use are present in the message content field. To reply to the computer use tool call, construct a ToolMessage with {"type": "computer_call_output"} in its additional_kwargs. The content of the message will be a screenshot. Below, we demonstrate a simple example.
First, load two screenshots:
import base64


def load_png_as_base64(file_path):
    with open(file_path, "rb") as image_file:
        encoded_string = base64.b64encode(image_file.read())
        return encoded_string.decode("utf-8")


screenshot_1_base64 = load_png_as_base64(
    "/path/to/screenshot_1.png"
)  # perhaps a screenshot of an application
screenshot_2_base64 = load_png_as_base64(
    "/path/to/screenshot_2.png"
)  # perhaps a screenshot of the Desktop
from langchain_openai import ChatOpenAI

# Initialize model
llm = ChatOpenAI(model="computer-use-preview", truncation="auto")

# Bind computer-use tool
tool = {
    "type": "computer_use_preview",
    "display_width": 1024,
    "display_height": 768,
    "environment": "browser",
}
llm_with_tools = llm.bind_tools([tool])

# Construct input message
input_message = {
    "role": "user",
    "content": [
        {
            "type": "text",
            "text": (
                "Click the red X to close and reveal my Desktop. "
                "Proceed, no confirmation needed."
            ),
        },
        {
            "type": "input_image",
            "image_url": f"data:image/png;base64,{screenshot_1_base64}",
        },
    ],
}

# Invoke model
response = llm_with_tools.invoke(
    [input_message],
    reasoning={
        "generate_summary": "concise",
    },
)
The response will include a call to the computer-use tool in its content:
response.content
[{'id': 'rs_685da051742c81a1bb35ce46a9f3f53406b50b8696b0f590',
  'summary': [{'text': "Clicking red 'X' to show desktop",
    'type': 'summary_text'}],
  'type': 'reasoning'},
 {'id': 'cu_685da054302481a1b2cc43b56e0b381706b50b8696b0f590',
  'action': {'button': 'left', 'type': 'click', 'x': 14, 'y': 38},
  'call_id': 'call_zmQerFBh4PbBE8mQoQHkfkwy',
  'pending_safety_checks': [],
  'status': 'completed',
  'type': 'computer_call'}]
We next construct a ToolMessage with these properties:
- It has a
tool_call_idmatching thecall_idfrom the computer-call. - It has
{"type": "computer_call_output"}in itsadditional_kwargs. - Its content is either an
image_urlor aninput_imageoutput block (see OpenAI docs for formatting).
from langchain.messages import ToolMessage

tool_call_id = next(
    item["call_id"] for item in response.content if item["type"] == "computer_call"
)

tool_message = ToolMessage(
    content=[
        {
            "type": "input_image",
            "image_url": f"data:image/png;base64,{screenshot_2_base64}",
        }
    ],
    # content=f"data:image/png;base64,{screenshot_2_base64}",  # <-- also acceptable
    tool_call_id=tool_call_id,
    additional_kwargs={"type": "computer_call_output"},
)
We can now invoke the model again using the message history:
messages = [
    input_message,
    response,
    tool_message,
]

response_2 = llm_with_tools.invoke(
    messages,
    reasoning={
        "generate_summary": "concise",
    },
)
response_2.text
'VS Code has been closed, and the desktop is now visible.'
Instead of passing back the entire sequence, we can also use the previous_response_id:
previous_response_id = response.response_metadata["id"]

response_2 = llm_with_tools.invoke(
    [tool_message],
    previous_response_id=previous_response_id,
    reasoning={
        "generate_summary": "concise",
    },
)
response_2.text
'The VS Code window is closed, and the desktop is now visible. Let me know if you need any further assistance.'
Code interpreter
OpenAI implements a code interpreter tool to support the sandboxed generation and execution of code.
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(
    model="gpt-5.4-mini",
    include=["code_interpreter_call.outputs"],  # optionally include outputs
)

llm_with_tools = llm.bind_tools(
    [
        {
            "type": "code_interpreter",
            # Create a new container
            "container": {"type": "auto"},
        }
    ]
)
response = llm_with_tools.invoke(
    "Write and run code to answer the question: what is 3^3?"
)
Note that the above command created a new container. We can also specify an existing container ID:
code_interpreter_calls = [
    item for item in response.content if item["type"] == "code_interpreter_call"
]
assert len(code_interpreter_calls) == 1
container_id = code_interpreter_calls[0]["extras"]["container_id"]  # [!code highlight]

llm_with_tools = llm.bind_tools(
    [
        {
            "type": "code_interpreter",
            # Use an existing container
            "container": container_id,  # [!code highlight]
        }
    ]
)
Apply patch
Info
Requires langchain-openai>=1.3.0
OpenAI implements an apply patch tool that lets the model create, update, or delete files using unified diffs. The tool is client-executed: the model proposes a file operation, your application applies it locally, and you return the result so the model can continue.
To engage it, pass {"type": "apply_patch"} to the model as you would another tool. No input schema is required — the model knows how to construct the operation object.
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(model="gpt-5.5")

llm_with_tools = llm.bind_tools([{"type": "apply_patch"}])

response = llm_with_tools.invoke(
    "Create a new file named hello.txt containing the line: hello world"
)
The model returns one or more apply_patch_call content blocks, each describing a single file operation (create_file, update_file, or delete_file):
apply_patch_calls = [
    block
    for block in response.content_blocks
    if block["type"] == "apply_patch_call"
]
[{'type': 'apply_patch_call',
  'id': 'apply_patch_...',
  'call_id': 'call_...',
  'operation': {'type': 'create_file',
   'path': 'hello.txt',
   'diff': '+hello world\n'},
  'status': 'completed'}]
Apply each operation to your filesystem, then send the result back as an apply_patch_call_output block keyed by the same call_id. Set status to "completed" on success, or "failed" with a descriptive output so the model can adjust and retry:
from langchain.messages import HumanMessage

call = apply_patch_calls[0]
# ... apply the operation to disk here ...

output_message = HumanMessage(
    content=[
        {
            "type": "apply_patch_call_output",
            "call_id": call["call_id"],
            "status": "completed",
            "output": f"Created {call['operation']['path']}",
        }
    ]
)

follow_up = llm_with_tools.invoke(
    [
        HumanMessage("Create a new file named hello.txt containing: hello world"),
        response,
        output_message,
    ]
)
Tip
You can also continue the conversation with OpenAI's stateful API by passing previous_response_id instead of the full message history. See Managing conversation state.
Remote MCP
OpenAI implements a remote MCP tool that allows for model-generated calls to MCP servers.
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(model="gpt-5.4-mini")

llm_with_tools = llm.bind_tools(
    [
        {
            "type": "mcp",
            "server_label": "deepwiki",
            "server_url": "https://mcp.deepwiki.com/mcp",
            "require_approval": "never",
        }
    ]
)
response = llm_with_tools.invoke(
    "What transport protocols does the 2025-03-26 version of the MCP "
    "spec (modelcontextprotocol/modelcontextprotocol) support?"
)
MCP Approvals
OpenAI will at times request approval before sharing data with a remote MCP server.
In the above command, we instructed the model to never require approval. We can also configure the model to always request approval, or to always request approval for specific tools:
llm_with_tools = llm.bind_tools(
    [
        {
            "type": "mcp",
            "server_label": "deepwiki",
            "server_url": "https://mcp.deepwiki.com/mcp",
            "require_approval": {
                "always": {
                    "tool_names": ["read_wiki_structure"]
                }
            }
        }
    ]
)
response = llm_with_tools.invoke(
    "What transport protocols does the 2025-03-26 version of the MCP "
    "spec (modelcontextprotocol/modelcontextprotocol) support?"
)
Responses may then include blocks with type "mcp_approval_request".
To submit approvals for an approval request, structure it into a content block in an input message:
approval_message = {
    "role": "user",
    "content": [
        {
            "type": "mcp_approval_response",
            "approve": True,
            "approval_request_id": block["id"],
        }
        for block in response.content
        if block["type"] == "mcp_approval_request"
    ]
}

next_response = llm_with_tools.invoke(
    [approval_message],
    # continue existing thread
    previous_response_id=response.response_metadata["id"]
)
Managing conversation state
The Responses API supports management of conversation state.
Manually manage state
You can manage the state manually or using LangGraph, as with other chat models:
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(model="gpt-5.4-mini", use_responses_api=True)

first_query = "Hi, I'm Bob."
messages = [{"role": "user", "content": first_query}]

response = llm.invoke(messages)
print(response.text)
Hi Bob! Nice to meet you. How can I assist you today?
second_query = "What is my name?"

messages.extend(
    [
        response,
        {"role": "user", "content": second_query},
    ]
)
second_response = llm.invoke(messages)
print(second_response.text)
You mentioned that your name is Bob. How can I assist you further, Bob?
Tip
You can use LangGraph to manage conversational threads for you in a variety of backends, including in-memory and Postgres. See this tutorial to get started.
Passing previous_response_id
When using the Responses API, LangChain messages will include an "id" field in its metadata. Passing this ID to subsequent invocations will continue the conversation. Note that this is equivalent to manually passing in messages from a billing perspective.
second_response = llm.invoke(
    "What is my name?",
    previous_response_id=response.id,  # [!code highlight]
)
print(second_response.text)
Your name is Bob. How can I help you today, Bob?
ChatOpenAI can also automatically specify previous_response_id using the last response in a message sequence:
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(
    model="gpt-5.4-mini",
    use_previous_response_id=True,  # [!code highlight]
)
If we set use_previous_response_id=True, input messages up to the most recent response will be dropped from request payloads, and previous_response_id will be set using the ID of the most recent response.
That is,
llm.invoke(
    [
        HumanMessage("Hello"),
        AIMessage("Hi there!", id="resp_123"),
        HumanMessage("How are you?"),
    ]
)
...is equivalent to:
llm.invoke([HumanMessage("How are you?")], previous_response_id="resp_123")
Context management
The Responses API supports automatic server-side context compaction. This reduces conversation size when it reaches a token threshold, allowing for support of long-running interactions:
from langchain_openai import ChatOpenAI

model = ChatOpenAI(
    model="gpt-5.5",
    context_management=[  # [!code highlight]
        {"type": "compaction", "compact_threshold": 100_000}  # [!code highlight]
    ],  # [!code highlight]
)
When enabled, AIMessage responses may contain blocks with "type": "compaction" in content. These should be retained in the conversation history, and can be appended to the message sequence in the usual way. Messages prior to the most recent compaction item can be kept, or discarded to improve latency.
Reasoning output
Some OpenAI models will generate separate text content illustrating their reasoning process. See OpenAI's reasoning documentation for details.
OpenAI can return a summary of the model's reasoning (although it doesn't expose the raw reasoning tokens). To configure ChatOpenAI to return this summary, specify the reasoning parameter. ChatOpenAI will automatically route to the Responses API if this parameter is set.
from langchain_openai import ChatOpenAI

reasoning = {
    "effort": "medium",  # 'low', 'medium', or 'high'
    "summary": "auto",  # 'detailed', 'auto', or None
}

llm = ChatOpenAI(model="gpt-5-nano", reasoning=reasoning)
response = llm.invoke("What is 3^3?")

# Output
response.text
'3³ = 3 × 3 × 3 = 27.'
# Reasoning
for block in response.content_blocks:
    if block["type"] == "reasoning":
        print(block["reasoning"])
**Calculating the power of three**

The user is asking about 3 raised to the power of 3. That's a pretty simple calculation! I know that 3^3 equals 27, so I can say, "3 to the power of 3 equals 27." I might also include a quick explanation that it's 3 multiplied by itself three times: 3 × 3 × 3 = 27. So, the answer is definitely 27.
For a simpler equivalent, use the standard reasoning_effort parameter, which translates to reasoning.effort and adds summary: "auto":
llm = ChatOpenAI(model="gpt-5-nano", reasoning_effort="medium")
Note
reasoning_effort as a standard parameter requires langchain-openai>=1.4.1.
Changing reasoning effort mid-conversation
Use a configuration_update content block to change reasoning effort between turns without modifying the request-level reasoning_effort parameter — keeping the prompt prefix cacheable. Embed the block directly in a HumanMessage:
from langchain_openai import ChatOpenAI
from langchain.messages import HumanMessage

llm = ChatOpenAI(model="gpt-6-astra", use_responses_api=True, reasoning_effort="low")

first = llm.invoke("Hello")

# Raise reasoning effort from this message onward
response = llm.invoke(
    [
        "Hello",
        first,
        HumanMessage(
            [
                {"type": "configuration_update", "reasoning": {"effort": "high"}},  # [!code highlight]
                {"type": "text", "text": "How many distinct 5-card poker hands are a full house?"},
            ]
        ),
    ]
)
Tip
Troubleshooting: Empty responses from reasoning models
If you're getting empty responses from reasoning models like gpt-5-nano, this is likely due to restrictive token limits. The model uses tokens for internal reasoning and may not have any left for the final output.
Ensure max_tokens is set to None or increase the token limit to allow sufficient tokens for both reasoning and output generation.
Add tools mid-conversation
Note
additional_tools requires langchain-openai>=1.6.5.
Use an additional_tools content block to make tools available from a point in the conversation onward. This is useful when your application loads tools outside the tool search flow. Put the block in a SystemMessage:
from langchain.messages import HumanMessage, SystemMessage
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(model="gpt-6-astra", use_responses_api=True)

response = llm.invoke(
    [
        HumanMessage("What time is it?"),
        SystemMessage(
            [
                {
                    "type": "additional_tools",  # [!code highlight]
                    "role": "developer",  # [!code highlight]
                    "tools": [
                        {
                            "type": "function",
                            "name": "get_time",
                            "description": "Get the current time.",
                            "parameters": {"type": "object", "properties": {}},
                        }
                    ],
                },
            ]
        ),
    ]
)
The block requires the Responses API, so set use_responses_api=True. On Chat Completions, or on a message other than a SystemMessage, ChatOpenAI raises a ValueError. You can also write the block wrapped in a non_standard block, which is how content_blocks returns it.
Fine-tuning
You can call fine-tuned OpenAI models by passing in your corresponding modelName parameter.
This generally takes the form of ft:{OPENAI_MODEL_NAME}:{ORG_NAME}::{MODEL_ID}. For example:
fine_tuned_model = ChatOpenAI(
    temperature=0, model_name="ft:gpt-3.5-turbo-0613:langchain::7qTVM5AR"
)

fine_tuned_model.invoke(messages)
AIMessage(content="J'adore la programmation.", additional_kwargs={'refusal': None}, response_metadata={'token_usage': {'completion_tokens': 8, 'prompt_tokens': 31, 'total_tokens': 39}, 'model_name': 'ft:gpt-3.5-turbo-0613:langchain::7qTVM5AR', 'system_fingerprint': None, 'finish_reason': 'stop', 'logprobs': None}, id='run-0f39b30e-c56e-4f3b-af99-5c948c984146-0', usage_metadata={'input_tokens': 31, 'output_tokens': 8, 'total_tokens': 39})
Multimodal inputs (images, PDFs, audio)
OpenAI has models that support multimodal inputs. You can pass in images, PDFs, or audio to these models. For more information on how to do this in LangChain, head to the multimodal inputs docs.
You can see the list of models that support different modalities in OpenAI's documentation.
For all modalities, LangChain supports both its cross-provider standard as well as OpenAI's native content-block format.
To pass multimodal data into ChatOpenAI, create a content block containing the data and incorporate it into a message, e.g., as below:
message = {
    "role": "user",
    "content": [
        {
            "type": "text",
            # Update prompt as desired
            "text": "Describe the (image / PDF / audio...)",
        },
        content_block,  # [!code highlight]
    ],
}
See below for examples of content blocks.
Images
Refer to examples in the multimodal messages how-to guide.
# LangChain format
content_block = {
    "type": "image",
    "url": url_string,
}

# OpenAI Chat Completions format
content_block = {
    "type": "image_url",
    "image_url": {"url": url_string},
}
# LangChain format
content_block = {
    "type": "image",
    "base64": base64_string,
    "mime_type": "image/jpeg",
}

# OpenAI Chat Completions format
content_block = {
    "type": "image_url",
    "image_url": {
        "url": f"data:image/jpeg;base64,{base64_string}",
    },
}
PDFs
Note: OpenAI requires file-names be specified for PDF inputs. When using LangChain's format, include the filename key.
Read more about OpenAI file names for multimodal messages.
Refer to examples in the PDF documents how-to guide.
# LangChain format
content_block = {
    "type": "file",
    "base64": base64_string,
    "mime_type": "application/pdf",
    "filename": "my-file.pdf",  # [!code highlight]
}

# OpenAI Chat Completions format
content_block = {
    "type": "file",
    "file": {
        "filename": "my-file.pdf",
        "file_data": f"data:application/pdf;base64,{base64_string}",
    }
}
Audio
See supported models, e.g., "gpt-4o-audio-preview".
Refer to examples in the audio how-to guide.
# LangChain format
content_block = {
    "type": "audio",
    "mime_type": "audio/wav",  # or appropriate mime-type
    "base64": base64_string,
}

# OpenAI Chat Completions format
content_block = {
    "type": "input_audio",
    "input_audio": {"data": base64_string, "format": "wav"},
}
Predicted output
Info
Requires langchain-openai>=0.2.6
Some OpenAI models (such as their gpt-4o and gpt-4o-mini series) support Predicted Outputs, which allow you to pass in a known portion of the LLM's expected output ahead of time to reduce latency. This is useful for cases such as editing text or code, where only a small part of the model's output will change.
Here's an example:
code = """
/// <summary>
/// Represents a user with a first name, last name, and username.
/// </summary>
public class User
{
    /// <summary>
    /// Gets or sets the user's first name.
    /// </summary>
    public string FirstName { get; set; }

    /// <summary>
    /// Gets or sets the user's last name.
    /// </summary>
    public string LastName { get; set; }

    /// <summary>
    /// Gets or sets the user's username.
    /// </summary>
    public string Username { get; set; }
}
"""

llm = ChatOpenAI(model="gpt-5.5")
query = (
    "Replace the Username property with an Email property. "
    "Respond only with code, and with no markdown formatting."
)
response = llm.invoke(
    [{"role": "user", "content": query}, {"role": "user", "content": code}],
    prediction={"type": "content", "content": code},
)
print(response.content)
print(response.response_metadata)
/// <summary>
/// Represents a user with a first name, last name, and email.
/// </summary>
public class User
{
    /// <summary>
    /// Gets or sets the user's first name.
    /// </summary>
    public string FirstName { get; set; }

    /// <summary>
    /// Gets or sets the user's last name.
    /// </summary>
    public string LastName { get; set; }

    /// <summary>
    /// Gets or sets the user's email.
    /// </summary>
    public string Email { get; set; }
}
{'token_usage': {'completion_tokens': 226, 'prompt_tokens': 166, 'total_tokens': 392, 'completion_tokens_details': {'accepted_prediction_tokens': 49, 'audio_tokens': None, 'reasoning_tokens': 0, 'rejected_prediction_tokens': 107}, 'prompt_tokens_details': {'audio_tokens': None, 'cached_tokens': 0}}, 'model_name': 'gpt-4o-2024-08-06', 'system_fingerprint': 'fp_45cf54deae', 'finish_reason': 'stop', 'logprobs': None}
Note
Predictions are billed as additional tokens and may increase your usage and costs in exchange for this reduced latency.
Audio generation (Preview)
Info
Requires langchain-openai>=0.2.3
OpenAI has a new audio generation feature that allows you to use audio inputs and outputs with the gpt-4o-audio-preview model.
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(
    model="gpt-4o-audio-preview",
    temperature=0,
    model_kwargs={
        "modalities": ["text", "audio"],
        "audio": {"voice": "alloy", "format": "wav"},
    },
)

output_message = llm.invoke(
    [
        ("human", "Are you made by OpenAI? Just answer yes or no"),
    ]
)
output_message.additional_kwargs['audio'] will contain a dictionary like
{
    'data': '<audio data b64-encoded',
    'expires_at': 1729268602,
    'id': 'audio_67127d6a44348190af62c1530ef0955a',
    'transcript': 'Yes.'
}
...and the format will be what was passed in model_kwargs['audio']['format'].
We can also pass this message with audio data back to the model as part of a message history before openai expires_at is reached.
Note
**Output audio is stored under the audio key in AIMessage.additional_kwargs, but input content blocks are typed with an input_audio type and key in HumanMessage.content lists. **
For more information, see OpenAI's audio docs.
history = [
    ("human", "Are you made by OpenAI? Just answer yes or no"),
    output_message,
    ("human", "And what is your name? Just give your name."),
]
second_output_message = llm.invoke(history)
Prompt caching
OpenAI's prompt caching feature automatically caches prompts longer than 1024 tokens to reduce costs and improve response times. This feature is enabled for all recent models (gpt-4o and newer).
Manual caching
You can use the prompt_cache_key parameter to influence OpenAI's caching and optimize cache hit rates:
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(model="gpt-5.5")

# Use a cache key for repeated prompts
messages = [
    {"role": "system", "content": "You are a helpful assistant that translates English to French."},
    {"role": "user", "content": "I love programming."},
]

response = llm.invoke(
    messages,
    prompt_cache_key="translation-assistant-v1"
)

# Check cache usage
cache_read_tokens = response.usage_metadata.input_token_details.cache_read
print(f"Cached tokens used: {cache_read_tokens}")
Warning
Cache hits require the prompt prefix to match exactly
Cache key strategies
You can use different cache key strategies based on your application's needs:
# Static cache keys for consistent prompt templates
customer_response = llm.invoke(
    messages,
    prompt_cache_key="customer-support-v1"
)

support_response = llm.invoke(
    messages,
    prompt_cache_key="internal-support-v1"
)

# Dynamic cache keys based on context
user_type = "premium"
cache_key = f"assistant-{user_type}-v1"
response = llm.invoke(messages, prompt_cache_key=cache_key)
Model-level caching
You can also set a default cache key at the model level using model_kwargs:
llm = ChatOpenAI(
    model="gpt-5.4-mini",
    model_kwargs={"prompt_cache_key": "default-cache-v1"}
)

# Uses default cache key
response1 = llm.invoke(messages)

# Override with specific cache key
response2 = llm.invoke(messages, prompt_cache_key="override-cache-v1")
Explicit caching with breakpoints
Note
Requires langchain-openai>=1.3.5. Supported on both the Chat Completions API and the Responses API.
OpenAI supports explicit prompt-cache breakpoints, which let you designate specific content blocks as cache boundaries. This gives you fine-grained control over which parts of a prompt are cached, rather than relying solely on automatic prefix caching.
To mark a content block as a cache breakpoint, add "prompt_cache_breakpoint": {"mode": "explicit"} to the block. Explicit breakpoints require GPT-5.6 or later model families.
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(
    model="gpt-5.6-sol",
    prompt_cache_options={"mode": "explicit"},
)

messages = [
    {
        "role": "system",
        "content": [
            {
                "type": "text",
                "text": (
                    "You are a helpful assistant with access to a large knowledge base."
                ),
                "prompt_cache_breakpoint": {"mode": "explicit"},  # [!code highlight]
            }
        ],
    },
    {"role": "user", "content": "Summarize the key points."},
]

response = llm.invoke(messages, prompt_cache_key="docs-breakpoint-v1")
Open a public LangSmith run for this example.
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(
    model="gpt-5.6-sol",
    use_responses_api=True,
    prompt_cache_options={"mode": "explicit"},
)

messages = [
    {
        "role": "system",
        "content": [
            {
                "type": "text",
                "text": (
                    "You are a helpful assistant with access to a large knowledge base."
                ),
                "prompt_cache_breakpoint": {"mode": "explicit"},  # [!code highlight]
            }
        ],
    },
    {"role": "user", "content": "Summarize the key points."},
]

response = llm.invoke(messages, prompt_cache_key="docs-breakpoint-v1")
Open a public LangSmith run for this example.
Breakpoints are supported on text, image, and file content blocks. You can also nest prompt_cache_breakpoint inside an extras dict if you prefer to keep the LangChain content block structure clean:
content_block = {
    "type": "text",
    "text": "Long system prompt...",
    "extras": {"prompt_cache_breakpoint": {"mode": "explicit"}},
}
Open a public LangSmith run for this example.
Request-level cache options
Note
Requires langchain-openai>=1.3.5. prompt_cache_options applies to GPT-5.6 and later model families.
You can pass request-level prompt cache options using the prompt_cache_options parameter on the model or per invocation:
mode:"implicit"(default) or"explicit". In"implicit"mode, OpenAI places a cache breakpoint on the latest message and also uses any explicit breakpoints you provide. In"explicit"mode, only your breakpoints are used for cache reads and writes. If the request has no explicit breakpoints, it does not use prompt caching.ttl: Minimum cache lifetime for breakpoints written by the request. The only supported value is"30m", which is also the default.
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(
    model="gpt-5.6-sol",
    prompt_cache_options={"mode": "explicit", "ttl": "30m"},
)

messages = [{"role": "user", "content": "Hello"}]

# Override per request
response = llm.invoke(
    messages,
    prompt_cache_options={"mode": "implicit"},
)
Open a public LangSmith run for this example.
For models before the GPT-5.6 family, use prompt_cache_retention instead ("in_memory" or "24h"). That field is separate from prompt_cache_options and is deprecated on GPT-5.6 and later model families.
Cache write tokens
When OpenAI writes new content to the prompt cache, it reports cache_write_tokens in the response. ChatOpenAI surfaces this as cache_creation in input_token_details:
response = llm.invoke(messages)

cache_read = response.usage_metadata["input_token_details"].get("cache_read")
cache_creation = response.usage_metadata["input_token_details"].get("cache_creation")
print(f"Cache read tokens:     {cache_read}")
print(f"Cache creation tokens: {cache_creation}")
Open a public LangSmith run for this example.
On the "priority" and "flex" service tiers, these keys are prefixed with the tier name — for example, "priority_cache_read" and "priority_cache_creation".
Flex processing
OpenAI offers a variety of service tiers. The "flex" tier offers cheaper pricing for requests, with the trade-off that responses may take longer and resources might not always be available. This approach is best suited for non-critical tasks, including model testing, data enhancement, or jobs that can be run asynchronously.
To use it, initialize the model with service_tier="flex":
llm = ChatOpenAI(model="o4-mini", service_tier="flex")
Note that this is a beta feature that is only available for a subset of models. See OpenAI docs for more detail.
API reference
For detailed documentation of all features and configuration options, head to the ChatOpenAI API reference.