本页还没有译文
本页 107 段还没译成日本語,下面显示的是英文原文。Interrupts
还没翻译译自英文(docs.langchain.com)本页 107 段都还没译
Interrupts allow you to pause graph execution at specific points and wait for external input before continuing. This enables human-in-the-loop patterns where you need external input to proceed. When an interrupt is triggered, LangGraph saves the graph state using its persistence layer and waits indefinitely until you resume execution.
Interrupts work by calling the interrupt() function at any point in your graph nodes. The function accepts any JSON-serializable value which is surfaced to the caller. When you're ready to continue, you resume execution by re-invoking the graph using Command, which then becomes the return value of the interrupt() call from inside the node.
Unlike static breakpoints (which pause before or after specific nodes), interrupts are dynamic: they can be placed anywhere in your code and can be conditional based on your application logic.
- Checkpointing keeps your place: the checkpointer writes the exact graph state so you can resume later, even when in an error state.
thread_idis your pointer: use{ configurable: { thread_id: ... } }as options to theinvokemethod to tell the checkpointer which state to load.- Interrupt payloads surface as
__interrupt__: the values you pass tointerrupt()return to the caller in the__interrupt__field so you know what the graph is waiting on.
The thread_id you choose is effectively your persistent cursor. Reusing it resumes the same checkpoint; using a new value starts a brand-new thread with an empty state.
Pause using interrupt
The interrupt function pauses graph execution and returns a value to the caller. When you call interrupt within a node, LangGraph saves the current graph state and waits for you to resume execution with input.
To use interrupt, you need:
- A checkpointer to persist the graph state (use a durable checkpointer in production)
- A thread ID in your config so the runtime knows which state to resume from
- To call
interrupt()where you want to pause (payload must be JSON-serializable)
import { interrupt } from "@langchain/langgraph";

async function approvalNode(state: State) {
    // Pause and ask for approval
    const approved = interrupt("Do you approve this action?");

    // Command({ resume: ... }) provides the value returned into this variable
    return { approved };
}
When you call interrupt, here's what happens:
-
Graph execution gets suspended at the exact point where
interruptis called -
State is saved using the checkpointer so execution can be resumed later, In production, this should be a persistent checkpointer (e.g. backed by a database)
-
Value is returned to the caller under
__interrupt__; it can be any JSON-serializable value (string, object, array, etc.) -
Graph waits indefinitely until you resume execution with a response
-
Response is passed back into the node when you resume, becoming the return value of the
interrupt()call
Resuming interrupts
After an interrupt pauses execution, you resume the graph by invoking it again with a Command that contains the resume value. The resume value is passed back to the interrupt call, allowing the node to continue execution with the external input.
import { Command } from "@langchain/langgraph";

// Initial run - hits the interrupt and pauses
// thread_id is the durable pointer back to the saved checkpoint
const config = { configurable: { thread_id: "thread-1" } };
const result = await graph.invoke({ input: "data" }, config);

// Check what was interrupted
// __interrupt__ mirrors every payload you passed to interrupt()
console.log(result.__interrupt__);
// [{ value: 'Do you approve this action?', ... }]

// Resume with the human's response
// Command({ resume }) returns that value from interrupt() in the node
await graph.invoke(new Command({ resume: true }), config);
Key points about resuming:
- You must use the same thread ID when resuming that was used when the interrupt occurred
- The value passed to
new Command({ resume: ... })becomes the return value of theinterruptcall - The node restarts from the beginning of the node where the
interruptwas called when resumed, so any code before theinterruptruns again - You can pass any JSON-serializable value as the resume value, subject to validation when you specify a Zod
responseSchema
Warning
new Command({ resume: ... }) is the only Command pattern intended as input to invoke()/stream()/stream_events(). The other Command parameters (update, goto, graph) are designed for returning from node functions. Do not pass new Command({ update: ... }) as input to continue multi-turn conversations—pass a plain input object instead.
Define an interrupt response schema
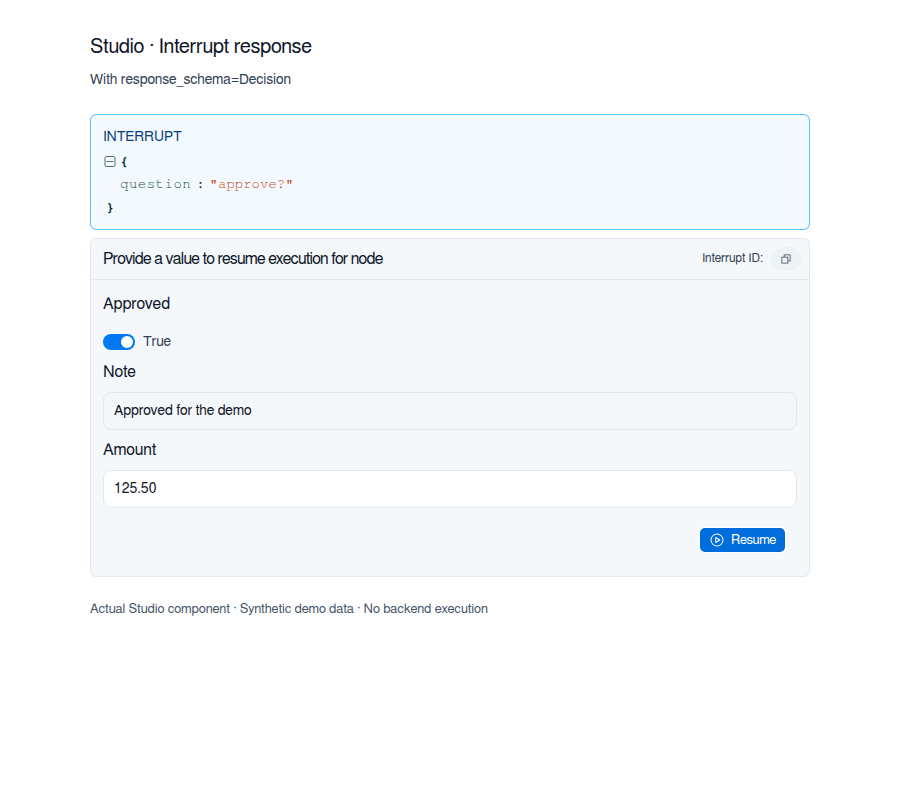
The responseSchema option to interrupt describes the input expected when you resume the graph. Clients can use the schema to render typed input forms.
Note
Interrupt response schemas require @langchain/langgraph version 1.4.16 or later.
Pass a Zod schema to validate resume values. LangGraph converts it to JSON Schema and includes it in Interrupt.response_schema, separately from the interrupt's value payload. The schema is available on interrupts returned to the caller and in checkpoint task interrupts.
This example uses the approval schema from LangGraph's interrupt tests:
import {
  Annotation,
  Command,
  MemorySaver,
  START,
  StateGraph,
  interrupt,
} from "@langchain/langgraph";
import { z } from "zod/v4";

const Decision = z.object({
  approved: z.boolean(),
  note: z.string().default(""),
});

const State = Annotation.Root({
  answer: Annotation<unknown>(),
});

const graph = new StateGraph(State)
  .addNode("node", () => ({
    answer: interrupt({ question: "approve?" }, { responseSchema: Decision }),
  }))
  .addEdge(START, "node")
  .compile({ checkpointer: new MemorySaver() });

const config = { configurable: { thread_id: "1" } };

const result = await graph.invoke({ answer: null }, config);
console.log(result.__interrupt__?.[0].response_schema);

const resumed = await graph.invoke(
  new Command({ resume: { approved: true } }),
  config
);
console.log(resumed.answer);
With a Zod schema, interrupt() returns the parsed value. In this example, the result is { approved: true, note: "" }, including the default note. Invalid input raises ZodError; you can retry with a corrected new Command({ resume: ... }) using the same thread ID.
You can also pass a JSON Schema object as responseSchema. LangGraph exposes that object unchanged but does not validate resume values against it. When you omit responseSchema, interrupts have no response_schema field, and resume values pass through without schema validation.
Studio renders interrupt response schemas as typed input fields instead of a JSON editor. This preview of the Studio component uses example data with approval, note, and numeric amount fields.
Common patterns
The key thing that interrupts unlock is the ability to pause execution and wait for external input. This is useful for a variety of use cases, including:
- Approval workflows: Pause before executing critical actions (API calls, database changes, financial transactions)
- Handling multiple interrupts: Pair interrupt IDs with resume values when resuming multiple interrupts in a single invocation
- Review and edit: Let humans review and modify LLM outputs or tool calls before continuing
- Interrupting tool calls: Pause before executing tool calls to review and edit the tool call before execution
- Validating human input: Pause before proceeding to the next step to validate human input
Stream with human-in-the-loop (HITL) interrupts
When building interactive agents with human-in-the-loop workflows, you can use event streaming to consume message chunks and state snapshots concurrently while handling interrupts.
Use the typed projections returned by graph.stream_events(..., version="v3") in a loop until the run finishes:
- Stream AI responses token-by-token via
stream.messages - Observe per-step state snapshots via
stream.values - Detect interrupts via
stream.interruptedand read their payloads fromstream.interrupts - Resume execution by calling
stream_eventsagain withCommand(resume=...)and repeat untilstream.interruptedis false
import { Command } from "@langchain/langgraph";

let streamInput: Record<string, unknown> | Command = initialInput;

while (true) {
  const stream = await graph.streamEvents(streamInput, {
    ...config,
    version: "v3",
  });

  // Stream LLM message chunks (including any in subgraphs) as they arrive.
  for await (const message of stream.messages) {
    for await (const token of message.text) {
      displayStreamingContent(token);
    }
  }

  // After the run finishes (or pauses), check for interrupts and resume.
  if (!stream.interrupted) {
    const finalState = await stream.output;
    break;
  }

  const interruptInfo = stream.interrupts[0].payload;
  const userResponse = await getUserInput(interruptInfo);
  streamInput = new Command({ resume: userResponse });
}Open a public LangSmith run for this example.
stream.messages: Chat-model output as content blocks; iteratemessage.textfor token deltas. For nested subgraphs, read message chunks fromstream.subgraphs[*].messages.stream.values: Full state snapshots after each stepstream.interrupted/stream.interrupts: After each run, check whether the graph paused; read payloads fromstream.interruptsCommand(resume=...): Pass as the nextstreamEventsinput to resume; loop until the run completes without interrupting
Handling multiple interrupts
When parallel branches interrupt simultaneously (for example, fan-out to multiple nodes that each call interrupt()), you may need to resume multiple interrupts in a single invocation.
When resuming multiple interrupts with a single invocation, map each interrupt ID to its resume value.
This ensures each response is paired with the correct interrupt at runtime.
import {
  Annotation,
  Command,
  END,
  INTERRUPT,
  MemorySaver,
  START,
  StateGraph,
  interrupt,
  isInterrupted,
} from "@langchain/langgraph";

const State = Annotation.Root({
  vals: Annotation<string[]>({
    reducer: (left, right) =>
      left.concat(Array.isArray(right) ? right : [right]),
    default: () => [],
  }),
});

function nodeA(_state: typeof State.State) {
  const answer = interrupt("question_a") as string;
  return { vals: [`a:${answer}`] };
}

function nodeB(_state: typeof State.State) {
  const answer = interrupt("question_b") as string;
  return { vals: [`b:${answer}`] };
}

const graph = new StateGraph(State)
  .addNode("a", nodeA)
  .addNode("b", nodeB)
  .addEdge(START, "a")
  .addEdge(START, "b")
  .addEdge("a", END)
  .addEdge("b", END)
  .compile({ checkpointer: new MemorySaver() });

const config = { configurable: { thread_id: "1" } };

async function main() {
  // Step 1: invoke - both parallel nodes hit interrupt() and pause
  const interruptedResult = await graph.invoke({ vals: [] }, config);
  console.log(interruptedResult);
  /*
  {
    vals: [],
    __interrupt__: [
      { id: '...', value: 'question_a' },
      { id: '...', value: 'question_b' }
    ]
  }
  */

  // Step 2: resume all pending interrupts at once
  const resumeMap: Record<string, string> = {};
  if (isInterrupted(interruptedResult)) {
    for (const i of interruptedResult[INTERRUPT]) {
      if (i.id != null) {
        resumeMap[i.id] = `answer for ${i.value}`;
      }
    }
  }
  const result = await graph.invoke(new Command({ resume: resumeMap }), config);

  console.log("Final state:", result);
  //> Final state: { vals: ['a:answer for question_a', 'b:answer for question_b'] }
}

main().catch(console.error);
Approve or reject
One of the most common uses of interrupts is to pause before a critical action and ask for approval. For example, you might want to ask a human to approve an API call, a database change, or any other important decision.
import { interrupt, Command } from "@langchain/langgraph";

const approvalNode: typeof State.Node = (state) => {
  // Pause execution; payload surfaces in result.__interrupt__
  const isApproved = interrupt({
    question: "Do you want to proceed?",
    details: state.actionDetails
  });

  // Route based on the response
  if (isApproved) {
    return new Command({ goto: "proceed" }); // Runs after the resume payload is provided
  } else {
    return new Command({ goto: "cancel" });
  }
}
When you resume the graph, pass true to approve or false to reject:
// To approve
await graph.invoke(new Command({ resume: true }), config);

// To reject
await graph.invoke(new Command({ resume: false }), config);Review and edit state
Sometimes you want to let a human review and edit part of the graph state before continuing. This is useful for correcting LLMs, adding missing information, or making adjustments.
import { interrupt } from "@langchain/langgraph";

const reviewNode: typeof State.Node = (state) => {
  // Pause and show the current content for review (surfaces in result.__interrupt__)
  const editedContent = interrupt({
    instruction: "Review and edit this content",
    content: state.generatedText
  });

  // Update the state with the edited version
  return { generatedText: editedContent };
}
When resuming, provide the edited content:
await graph.invoke(
  new Command({ resume: "The edited and improved text" }), // Value becomes the return from interrupt()
  config
);Interrupts in tools
You can also place interrupts directly inside tool functions. This makes the tool itself pause for approval whenever it's called, and allows for human review and editing of the tool call before it is executed.
First, define a tool that uses interrupt:
import { tool } from "@langchain/core/tools";
import { interrupt } from "@langchain/langgraph";
import * as z from "zod";

const sendEmailTool = tool(
  async ({ to, subject, body }) => {
    // Pause before sending; payload surfaces in result.__interrupt__
    const response = interrupt({
      action: "send_email",
      to,
      subject,
      body,
      message: "Approve sending this email?",
    });

    if (response?.action === "approve") {
      // Resume value can override inputs before executing
      const finalTo = response.to ?? to;
      const finalSubject = response.subject ?? subject;
      const finalBody = response.body ?? body;
      return `Email sent to ${finalTo} with subject '${finalSubject}'`;
    }
    return "Email cancelled by user";
  },
  {
    name: "send_email",
    description: "Send an email to a recipient",
    schema: z.object({
      to: z.string(),
      subject: z.string(),
      body: z.string(),
    }),
  },
);
This approach is useful when you want the approval logic to live with the tool itself, making it reusable across different parts of your graph. The LLM can call the tool naturally, and the interrupt will pause execution whenever the tool is invoked, allowing you to approve, edit, or cancel the action.
Validating human input
Sometimes you need to validate input from humans and re-prompt if the value is invalid. The recommended approach is to call interrupt() once per node invocation, return from the node with the error message stored in state, and use a conditional edge to loop back to the node until a valid value is provided.
Warning
Avoid while True + interrupt() loops inside a single node. Because the node re-runs from the beginning on every resume (see Rules of interrupts), a loop that calls interrupt() multiple times causes each resume to replay all previous iterations: the first resume replays 1 iteration, the second replays 2, and so on. The result is exponential re-execution of any code inside the loop body.
The correct pattern:
- Store the re-prompt question in state (e.g.
pendingQuestion). - In the node, call
interrupt()exactly once, passing the current question from state. - If the answer is invalid, return the updated
pendingQuestionso the next invocation re-prompts. - Use
addConditionalEdgesto route back to the node until a valid value is collected.
import { interrupt } from "@langchain/langgraph";

const getAgeNode: typeof State.Node = (state) => {
  const question = state.pendingQuestion ?? "What is your age?";
  const answer = interrupt(question); // called exactly once per invocation

  if (typeof answer === "number" && answer > 0) {
    return { age: answer, pendingQuestion: null };
  }
  return {
    pendingQuestion: `'${answer}' is not a valid age. Please enter a positive number.`,
  };
};

// builder.addConditionalEdges("collectAge", (state) =>
//   state.age !== null ? END : "collectAge"
// );Open a public LangSmith run for this example.
Each resume invokes getAgeNode exactly once, runs the interrupt() call once, and exits. When the answer is invalid, the conditional edge loops back and the next interrupt re-prompts with the updated question.
Rules of interrupts
When you call interrupt within a node, LangGraph suspends execution by raising an exception that signals the runtime to pause. This exception propagates up through the call stack and is caught by the runtime, which notifies the graph to save the current state and wait for external input.
When execution resumes (after you provide the requested input), the runtime restarts the entire node from the beginning—it does not resume from the exact line where interrupt was called. This means any code that ran before the interrupt will execute again. Because of this, there's a few important rules to follow when working with interrupts to ensure they behave as expected.
Do not wrap interrupt calls in try/catch
The way that interrupt pauses execution at the point of the call is by throwing a special exception. If you wrap the interrupt call in a try/catch block, you will catch this exception and the interrupt will not be passed back to the graph.
- ✅ Separate
interruptcalls from error-prone code - ✅ Conditionally catch errors if needed
const nodeA: GraphNode<typeof State> = async (state) => {
  // ✅ Good: interrupting first, then handling error conditions separately
  const name = interrupt("What's your name?");
  try {
    await fetchData(); // This can fail
  } catch (err) {
    console.error(error);
  }
  return state;
}
const nodeA: GraphNode<typeof State> = async (state) => {
// ✅ Good: re-throwing the exception will
// allow the interrupt to be passed back to
// the graph
try {
const name = interrupt("What's your name?");
await fetchData(); // This can fail
} catch (err) {
if (error instanceof NetworkError) {
console.error(error);
}
throw error;
}
return state;
}
- 🔴 Do not wrap
interruptcalls in bare try/catch blocks
async function nodeA(state: State) {
    // ❌ Bad: wrapping interrupt in bare try/catch will catch the interrupt exception
    try {
        const name = interrupt("What's your name?");
    } catch (err) {
        console.error(error);
    }
    return state;
}
Do not reorder interrupt calls within a node
It's common to use multiple interrupts in a single node, however this can lead to unexpected behavior if not handled carefully.
When a node contains multiple interrupt calls, LangGraph keeps a list of resume values specific to the task executing the node. Whenever execution resumes, it starts at the beginning of the node. For each interrupt encountered, LangGraph checks if a matching value exists in the task's resume list. Matching is strictly index-based, so the order of interrupt calls within the node is important.
- ✅ Keep
interruptcalls consistent across node executions
async function nodeA(state: State) {
    // ✅ Good: interrupt calls happen in the same order every time
    const name = interrupt("What's your name?");
    const age = interrupt("What's your age?");
    const city = interrupt("What's your city?");

    return {
        name,
        age,
        city
    };
}
- 🔴 Do not conditionally skip
interruptcalls within a node - 🔴 Do not loop
interruptcalls using logic that isn't deterministic across executions, includingwhile Truevalidation loops. Use a conditional edge instead (see Validating human input)
const nodeA: GraphNode<typeof State> = async (state) => {
  // ❌ Bad: conditionally skipping interrupts changes the order
  const name = interrupt("What's your name?");

  // On first run, this might skip the interrupt
  // On resume, it might not skip it - causing index mismatch
  if (state.needsAge) {
    const age = interrupt("What's your age?");
  }

  const city = interrupt("What's your city?");

  return { name, city };
}
const nodeA: GraphNode<typeof State> = async (state) => {
  // ❌ Bad: looping based on non-deterministic data
  // The number of interrupts changes between executions
  const results = [];
  for (const item of state.dynamicList || []) {  // List might change between runs
    const result = interrupt(`Approve ${item}?`);
    results.push(result);
  }

  return { results };
}
Do not return complex values in interrupt calls
Depending on which checkpointer is used, complex values may not be serializable (e.g. you can't serialize a function). To make your graphs adaptable to any deployment, it's best practice to only use values that can be reasonably serialized.
- ✅ Pass simple, JSON-serializable types to
interrupt - ✅ Pass dictionaries/objects with simple values
const nodeA: GraphNode<typeof State> = async (state) => {
  // ✅ Good: passing simple types that are serializable
  const name = interrupt("What's your name?");
  const count = interrupt(42);
  const approved = interrupt(true);

  return { name, count, approved };
}
const nodeA: GraphNode<typeof State> = async (state) => {
  // ✅ Good: passing objects with simple values
  const response = interrupt({
    question: "Enter user details",
    fields: ["name", "email", "age"],
    currentValues: state.user || {}
  });

  return { user: response };
}
- 🔴 Do not pass functions, class instances, or other complex objects to
interrupt
function validateInput(value: string): boolean {
    return value.length > 0;
}

const nodeA: GraphNode<typeof State> = async (state) => {
  // ❌ Bad: passing a function to interrupt
  // The function cannot be serialized
  const response = interrupt({
    question: "What's your name?",
    validator: validateInput  // This will fail
  });
  return { name: response };
}
class DataProcessor {
    constructor(private config: any) {}
}

const nodeA: GraphNode<typeof State> = async (state) => {
  const processor = new DataProcessor({ mode: "strict" });

  // ❌ Bad: passing a class instance to interrupt
  // The instance cannot be serialized
  const response = interrupt({
    question: "Enter data to process",
    processor: processor  // This will fail
  });
  return { result: response };
}
Side effects called before interrupt must be idempotent
Because interrupts work by re-running the nodes they were called from, side effects called before interrupt should (ideally) be idempotent. For context, idempotency means that the same operation can be applied multiple times without changing the result beyond the initial execution.
As an example, you might have an API call to update a record inside of a node. If interrupt is called after that call is made, it will be re-run multiple times when the node is resumed, potentially overwriting the initial update or creating duplicate records.
- ✅ Use idempotent operations before
interrupt - ✅ Place side effects after
interruptcalls - ✅ Separate side effects into separate nodes when possible
const nodeA: GraphNode<typeof State> = async (state) => {
  // ✅ Good: using upsert operation which is idempotent
  // Running this multiple times will have the same result
  await db.upsertUser({
    userId: state.userId,
    status: "pending_approval"
  });

  const approved = interrupt("Approve this change?");

  return { approved };
}
const nodeA: GraphNode<typeof State> = async (state) => {
  // ✅ Good: placing side effect after the interrupt
  // This ensures it only runs once after approval is received
  const approved = interrupt("Approve this change?");

  if (approved) {
    await db.createAuditLog({
      userId: state.userId,
      action: "approved"
    });
  }

  return { approved };
}
const approvalNode: GraphNode<typeof State> = async (state) => {
  // ✅ Good: only handling the interrupt in this node
  const approved = interrupt("Approve this change?");

  return { approved };
}

const notificationNode: GraphNode<typeof State> = async (state) => {
  // ✅ Good: side effect happens in a separate node
  // This runs after approval, so it only executes once
  if (state.approved) {
    await sendNotification({
      userId: state.userId,
      status: "approved",
    });
  }

  return state;
}
- 🔴 Do not perform non-idempotent operations before
interrupt - 🔴 Do not create new records without checking if they exist
const nodeA: GraphNode<typeof State> = async (state) => {
  // ❌ Bad: creating a new record before interrupt
  // This will create duplicate records on each resume
  const auditId = await db.createAuditLog({
    userId: state.userId,
    action: "pending_approval",
    timestamp: new Date()
  });

  const approved = interrupt("Approve this change?");

  return { approved, auditId };
}
const nodeA: GraphNode<typeof State> = async (state) => {
  // ❌ Bad: appending to an array before interrupt
  // This will add duplicate entries on each resume
  await db.appendToHistory(state.userId, "approval_requested");

  const approved = interrupt("Approve this change?");

  return { approved };
}
Using with subgraphs called as functions
When invoking a subgraph within a node, the parent graph will resume execution from the beginning of the node where the subgraph was invoked and the interrupt was triggered. Similarly, the subgraph will also resume from the beginning of the node where interrupt was called.
async function nodeInParentGraph(state: State) {
    someCode(); // <-- This will re-execute when resumed
    // Invoke a subgraph as a function.
    // The subgraph contains an `interrupt` call.
    const subgraphResult = await subgraph.invoke(someInput);
    // ...
}

async function nodeInSubgraph(state: State) {
    someOtherCode(); // <-- This will also re-execute when resumed
    const result = interrupt("What's your name?");
    // ...
}
Debugging with interrupts
To debug and test a graph, you can use static interrupts as breakpoints to step through the graph execution one node at a time. Static interrupts are triggered at defined points either before or after a node executes. You can set these by specifying interruptBefore and interruptAfter when compiling the graph.
Note
Static interrupts are not recommended for human-in-the-loop workflows. Use the interrupt function instead.
const graph = builder.compile({
    interruptBefore: ["node_a"],  // [!code highlight]
    interruptAfter: ["node_b", "node_c"],  // [!code highlight]
    checkpointer,
});

// Pass a thread ID to the graph
const config = {
    configurable: {
        thread_id: "some_thread"
    }
};

// Run the graph until the breakpoint
await graph.invoke(inputs, config);# [!code highlight]

await graph.invoke(null, config);  # [!code highlight]
- The breakpoints are set during
compiletime. interruptBeforespecifies the nodes where execution should pause before the node is executed.interruptAfterspecifies the nodes where execution should pause after the node is executed.- A checkpointer is required to enable breakpoints.
- The graph is run until the first breakpoint is hit.
- The graph is resumed by passing in
nullfor the input. This will run the graph until the next breakpoint is hit.
// Run the graph until the breakpoint
graph.invoke(inputs, {
    interruptBefore: ["node_a"],  // [!code highlight]
    interruptAfter: ["node_b", "node_c"],  // [!code highlight]
    configurable: {
        thread_id: "some_thread"
    }
});

// Resume the graph
await graph.invoke(null, config);  // [!code highlight]
graph.invokeis called with theinterruptBeforeandinterruptAfterparameters. This is a run-time configuration and can be changed for every invocation.interruptBeforespecifies the nodes where execution should pause before the node is executed.interruptAfterspecifies the nodes where execution should pause after the node is executed.- The graph is run until the first breakpoint is hit.
- The graph is resumed by passing in
nullfor the input. This will run the graph until the next breakpoint is hit.
Tip
To debug your interrupts, use LangSmith.
Using LangSmith Studio
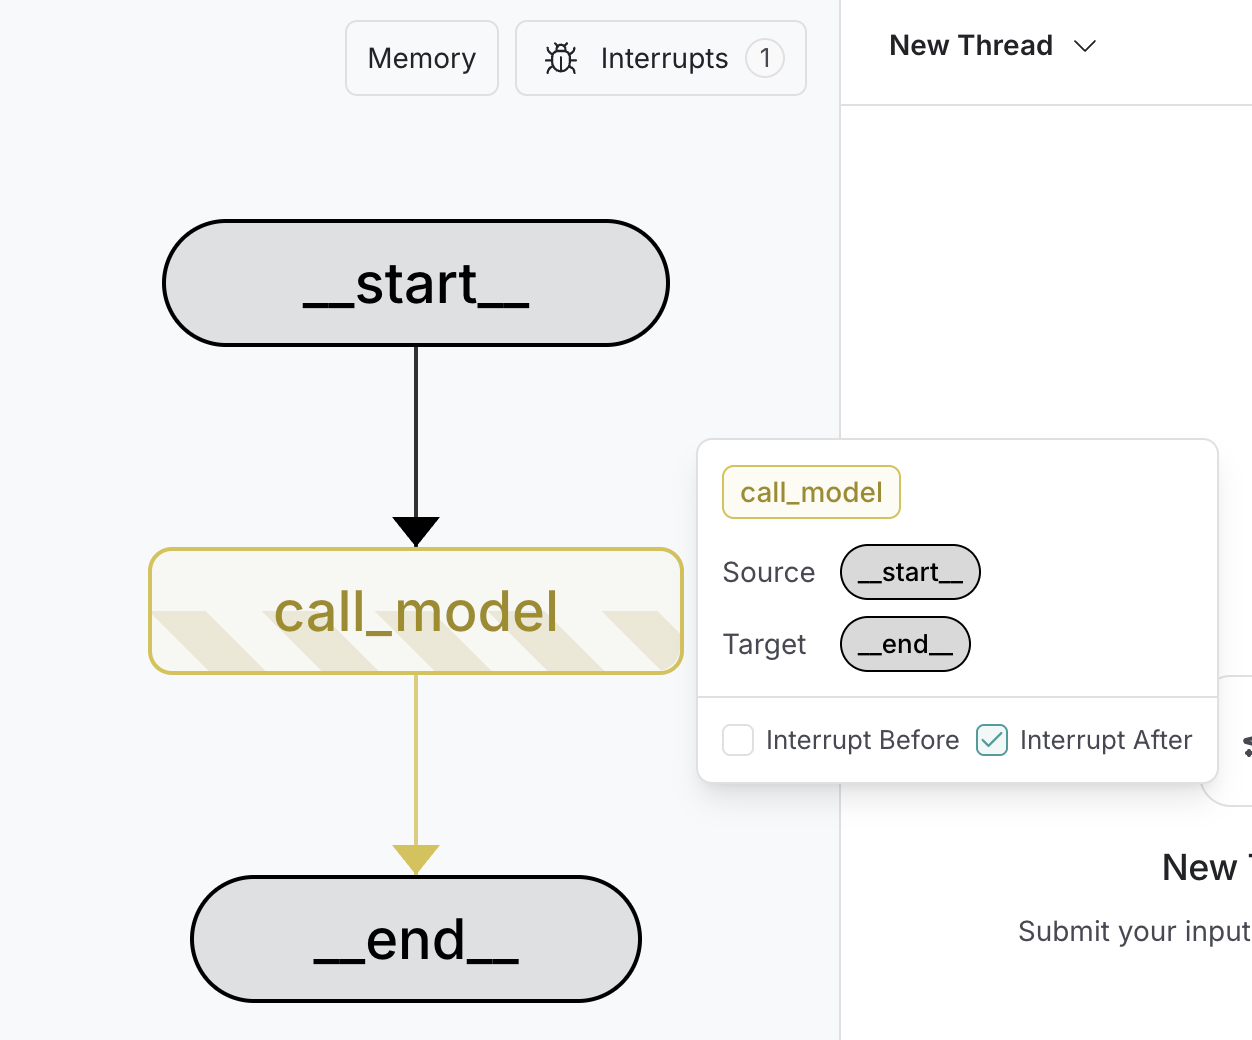
You can use LangSmith Studio to set static interrupts in your graph in the UI before running the graph. You can also use the UI to inspect the graph state at any point in the execution.