Checkpointing saves a snapshot of execution state during a run so a crew, flow, or agent can resume after a failure or be forked into an alternate branch.
A checkpoint captures everything CrewAI needs to recreate a run mid-flight: the full state of the crew, flow, or agent — configuration, agent memory and knowledge sources, task progress, intermediate outputs, internal state and attributes — alongside the kickoff inputs, the event history up to that point, and a lineage ID that ties the checkpoint to the run it came from.
Restoring rebuilds that state and continues. Completed tasks are skipped, memory and knowledge are rehydrated, and downstream work runs against the same outputs the original run produced. Forking does the same restore under a new lineage, so the new branch and the original run can write checkpoints side by side without overwriting each other.
When checkpoints are written
Checkpointing is event-driven. The runtime subscribes to events you select via on_events and writes a checkpoint each time one fires. The default task_completed produces one checkpoint per finished task — a sensible tradeoff between granularity and disk use. Higher-frequency events like llm_call_completed are available for fine-grained recovery but write far more files.
Storage
Two providers ship with CrewAI:
JsonProvider writes one file per checkpoint. Human-readable and easy to inspect.
SqliteProvider writes to a single SQLite database. Better for high-frequency checkpointing.
Both prune oldest checkpoints when max_checkpoints is set.
Note
Auto-checkpoint writes (event-driven) are best-effort: a failed write is logged and the run continues. Manual state.checkpoint() and state.acheckpoint() calls re-raise on failure.
Inheritance model
Crew, Flow, and Agent all accept a checkpoint argument. Children inherit from their parent unless they set their own value or pass False to opt out. Enable checkpointing once on the crew and every agent participates, or selectively exclude one agent.
Tutorial: Resume a failing crew
This walkthrough takes ~5 minutes. You will run a two-task crew, kill it midway, and resume from the saved checkpoint.
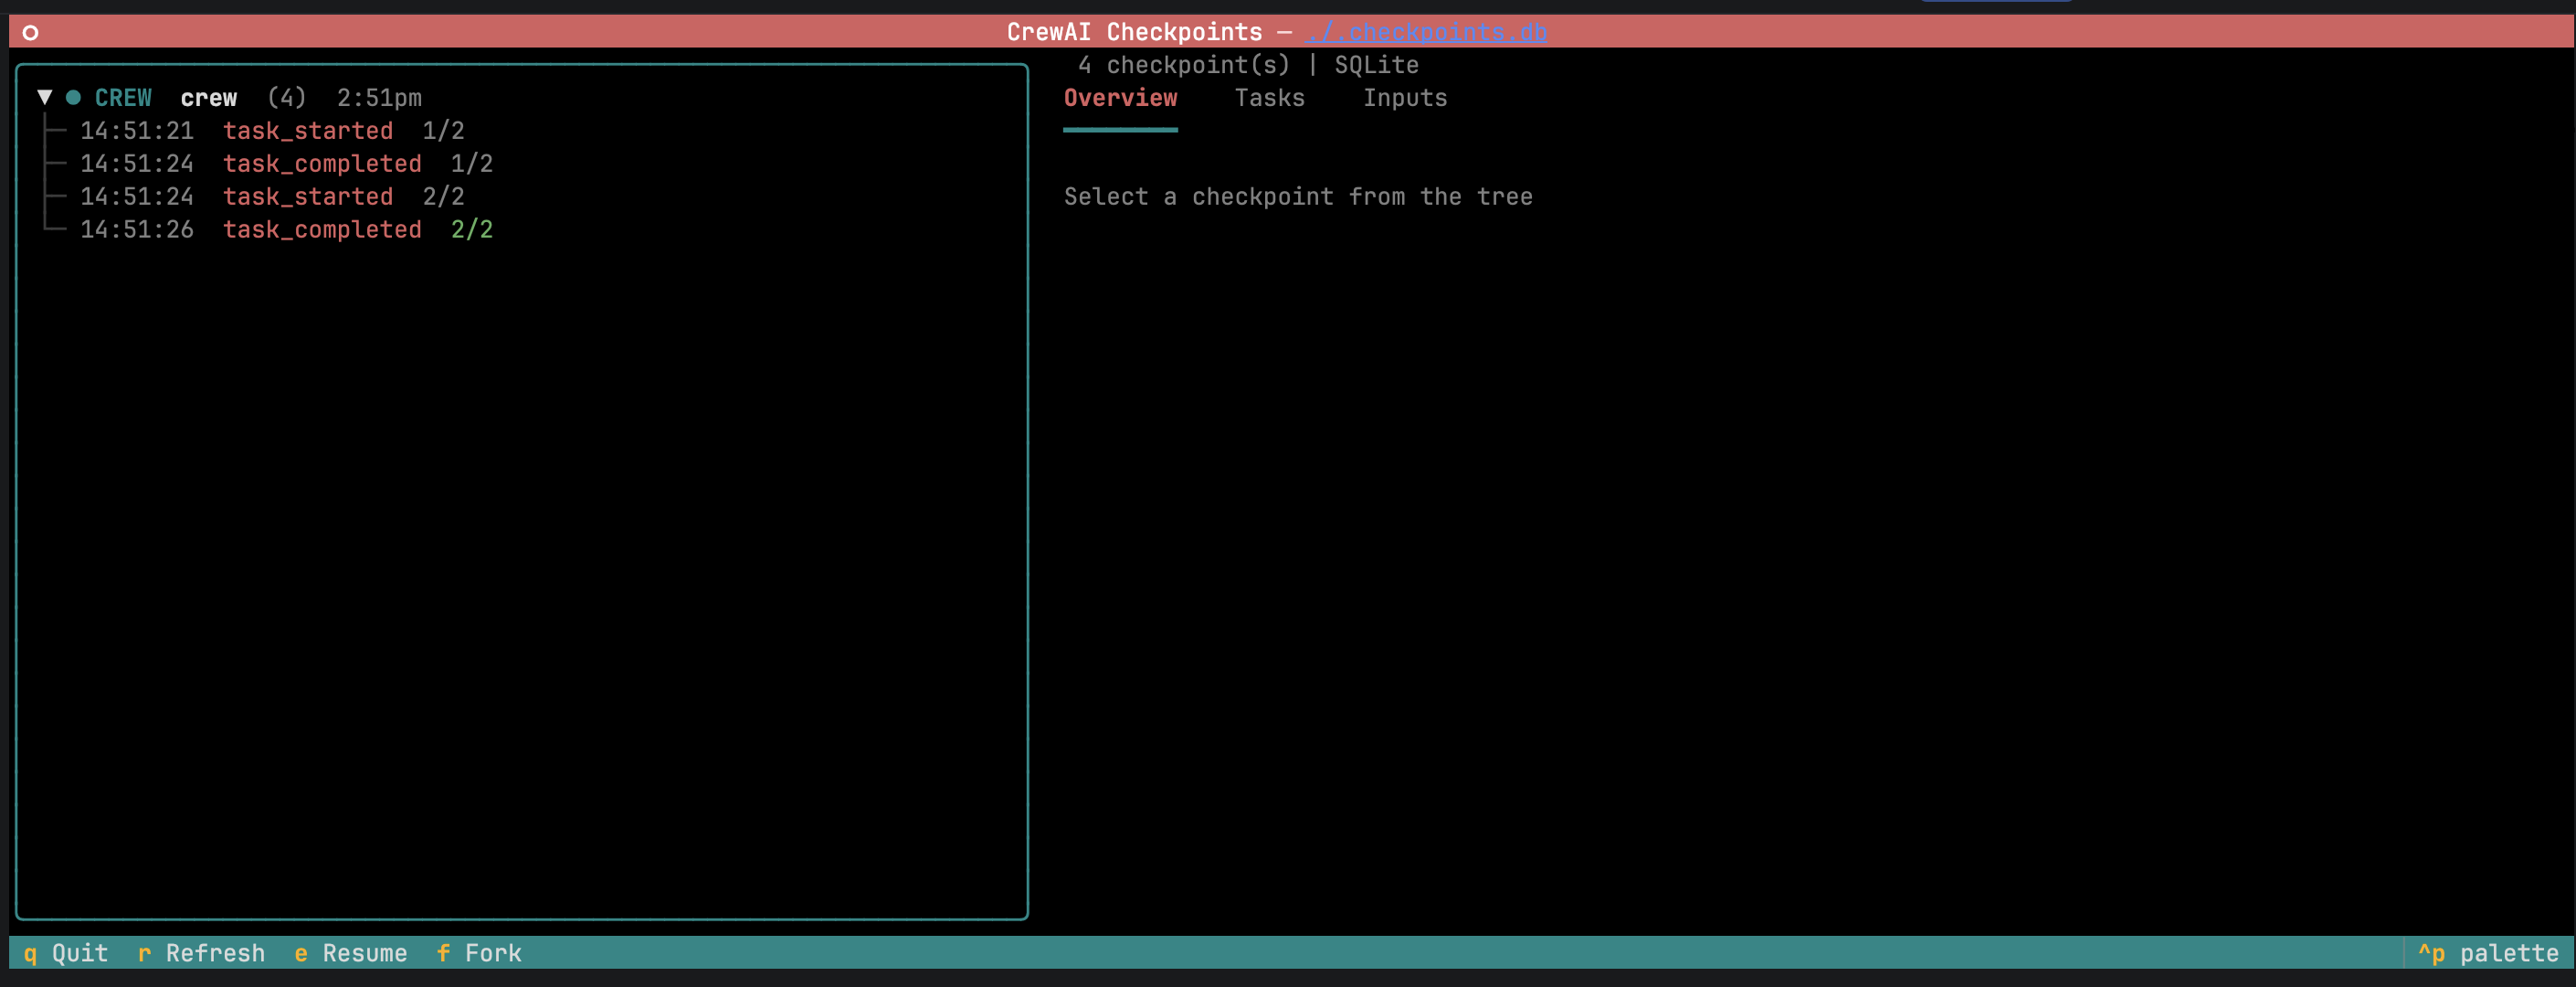
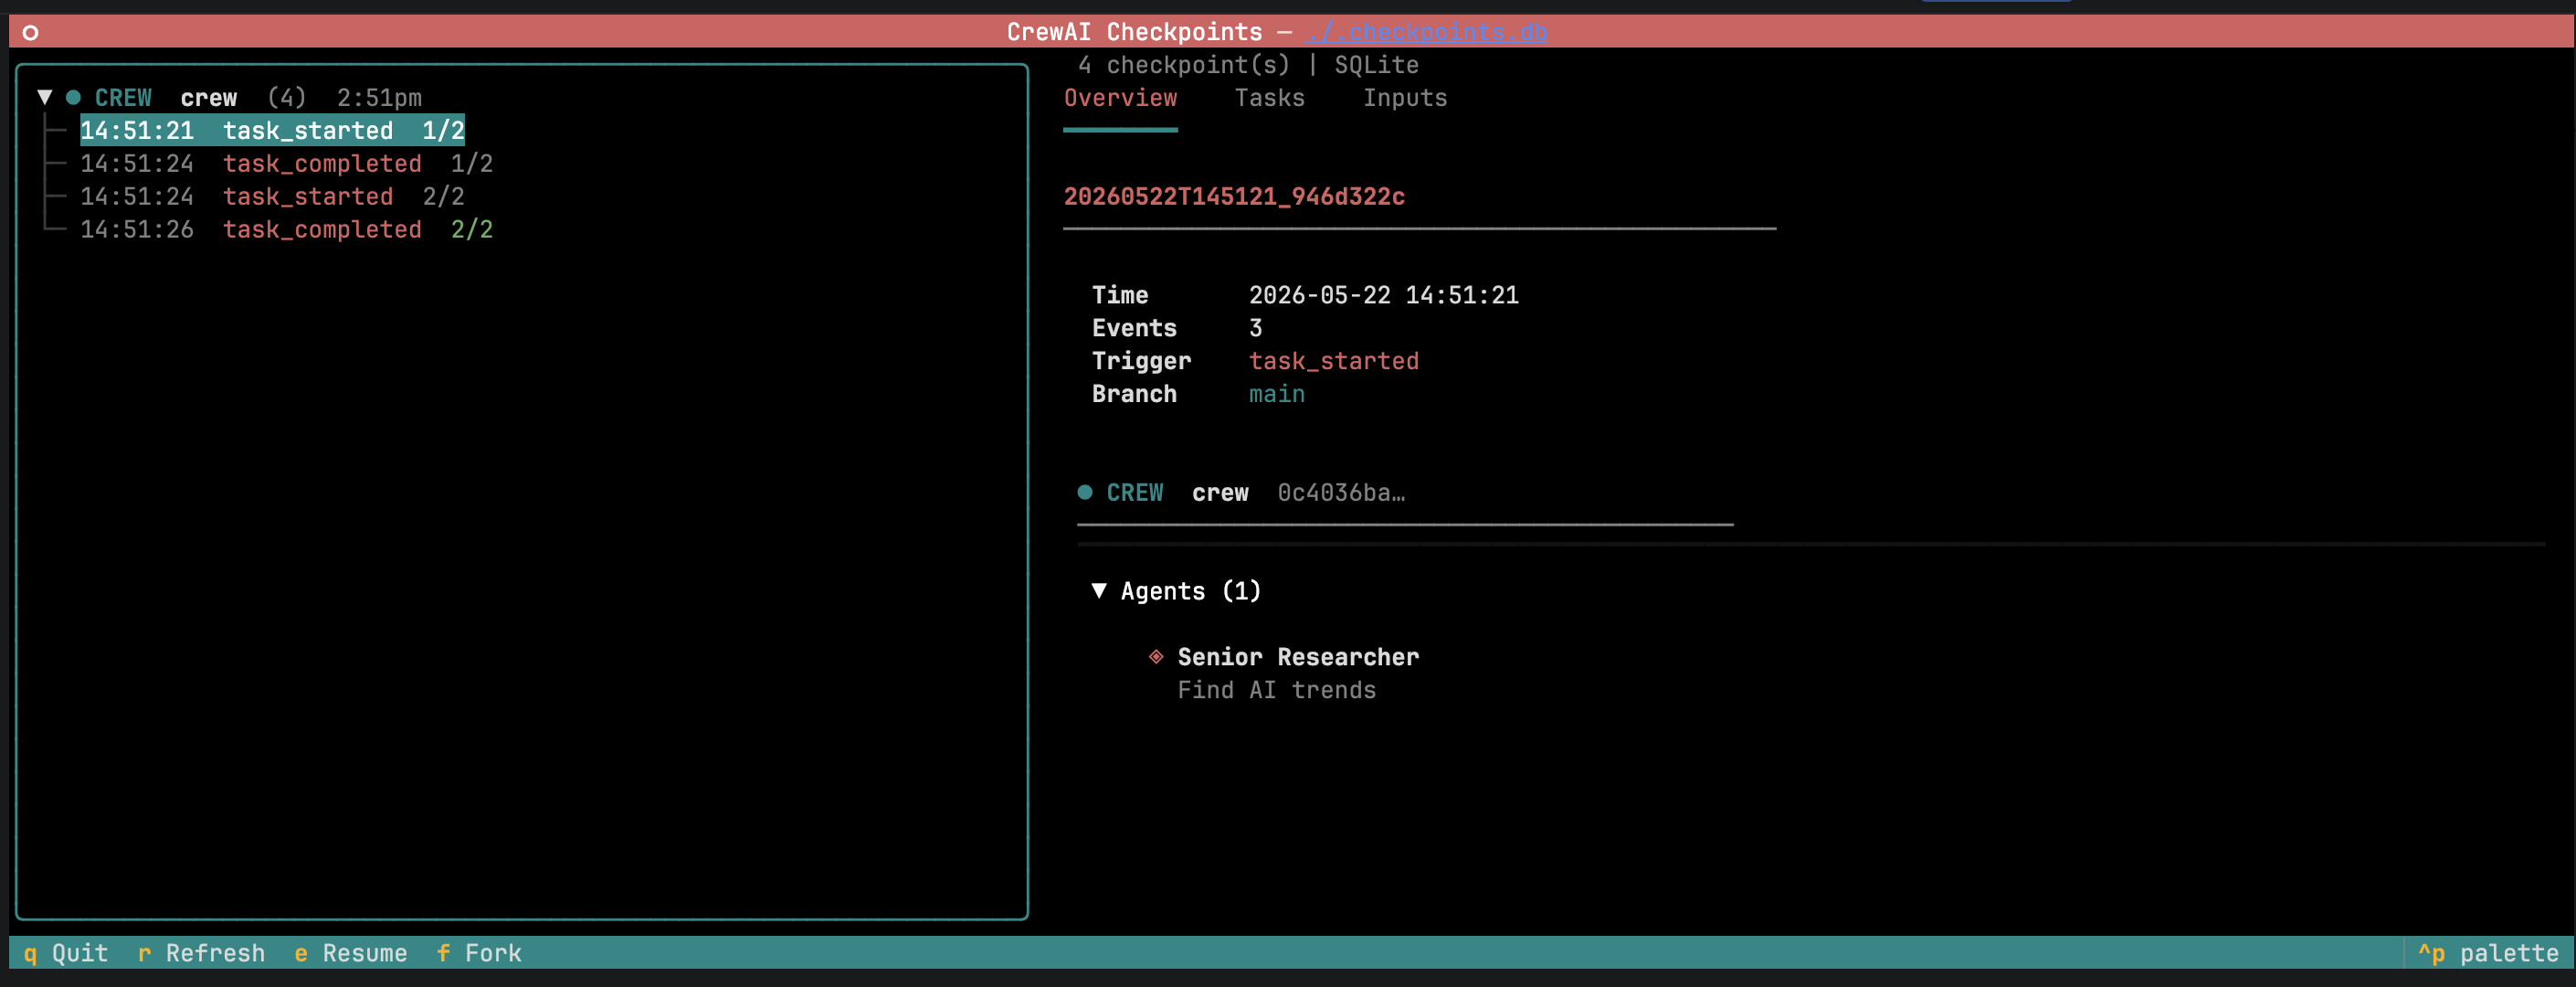
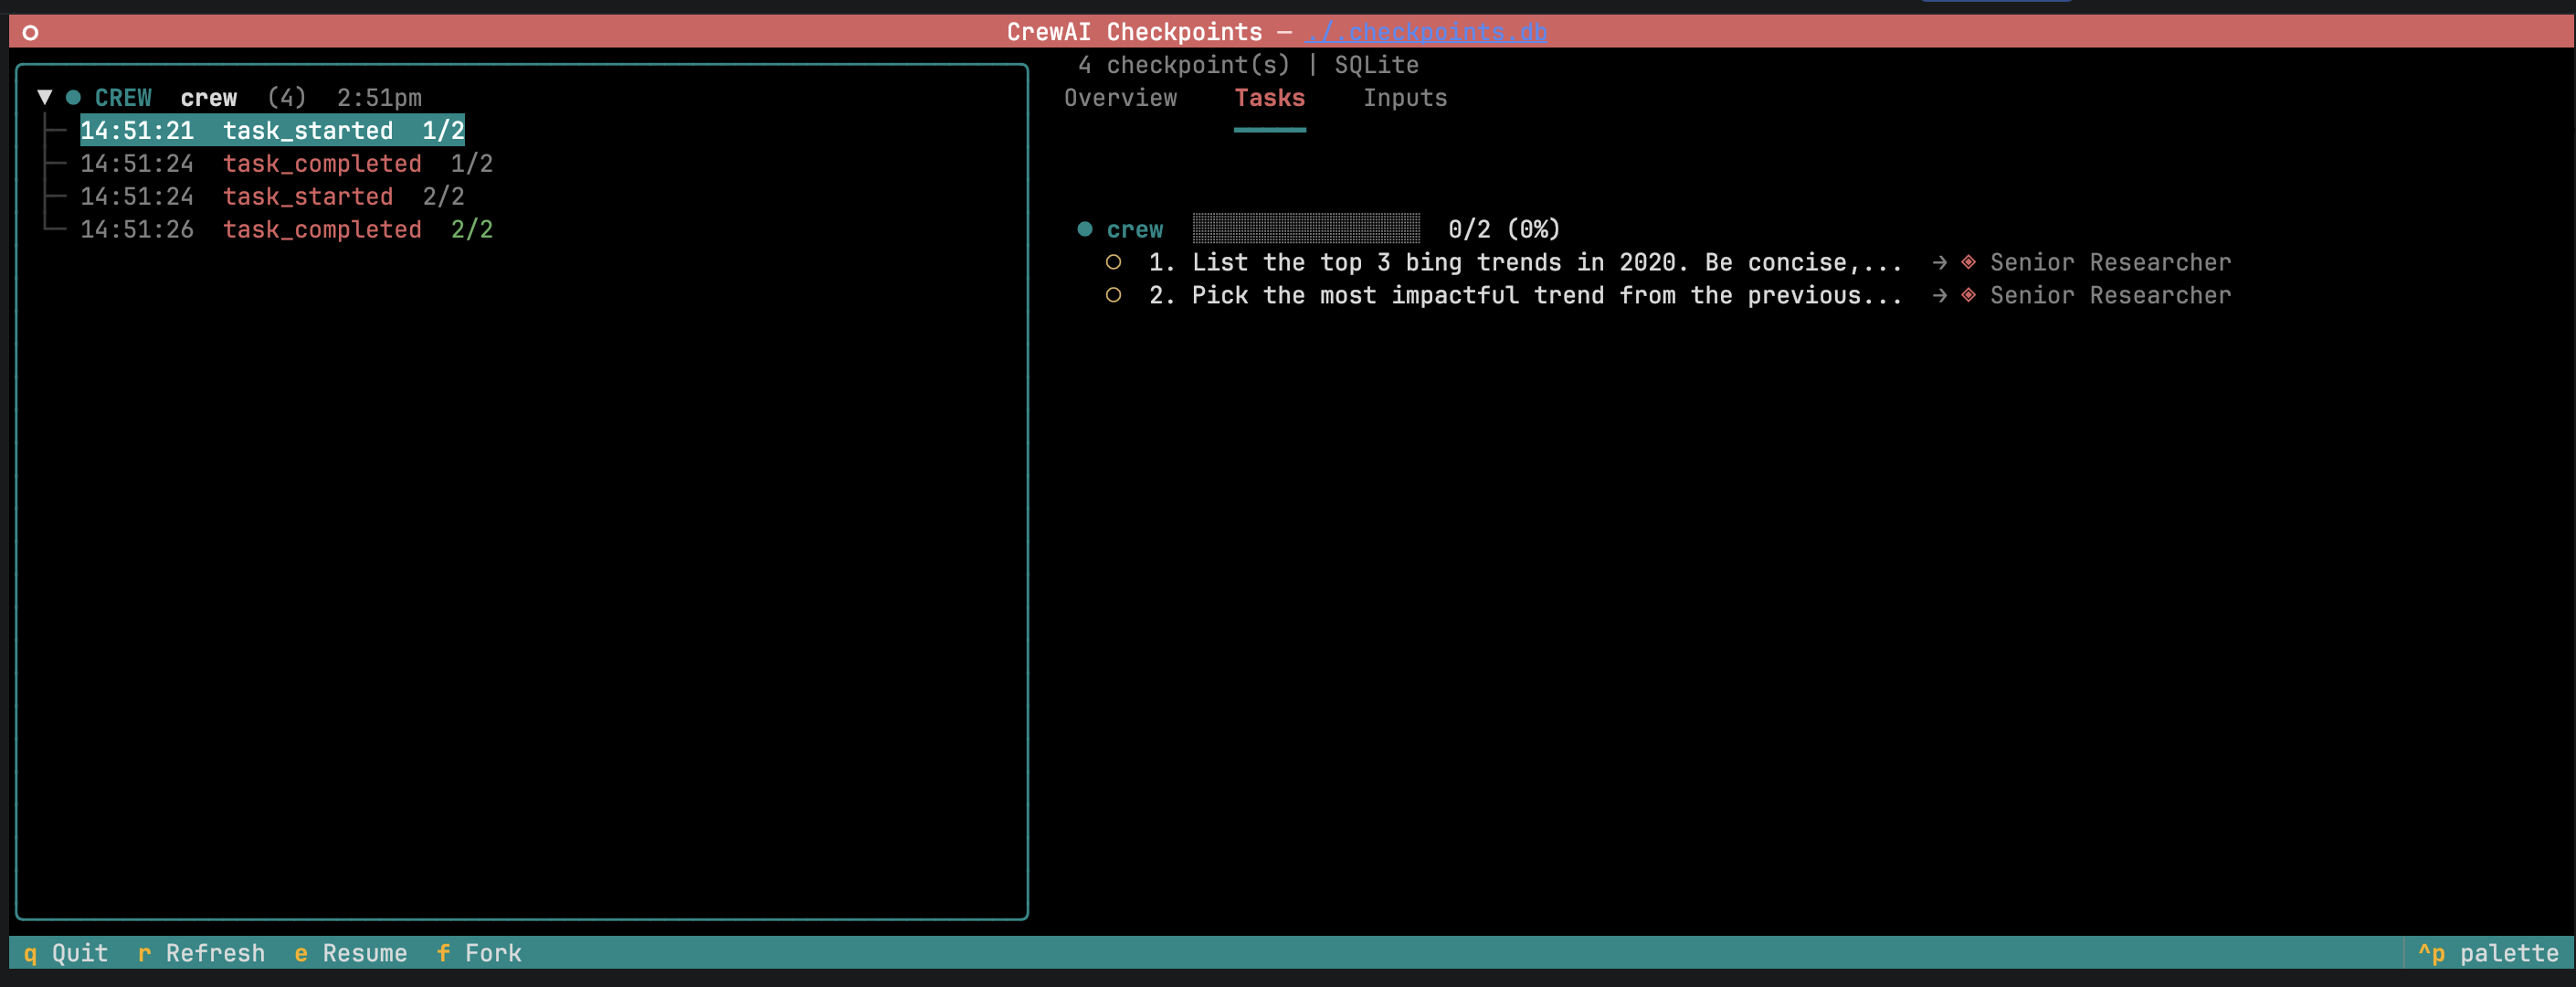
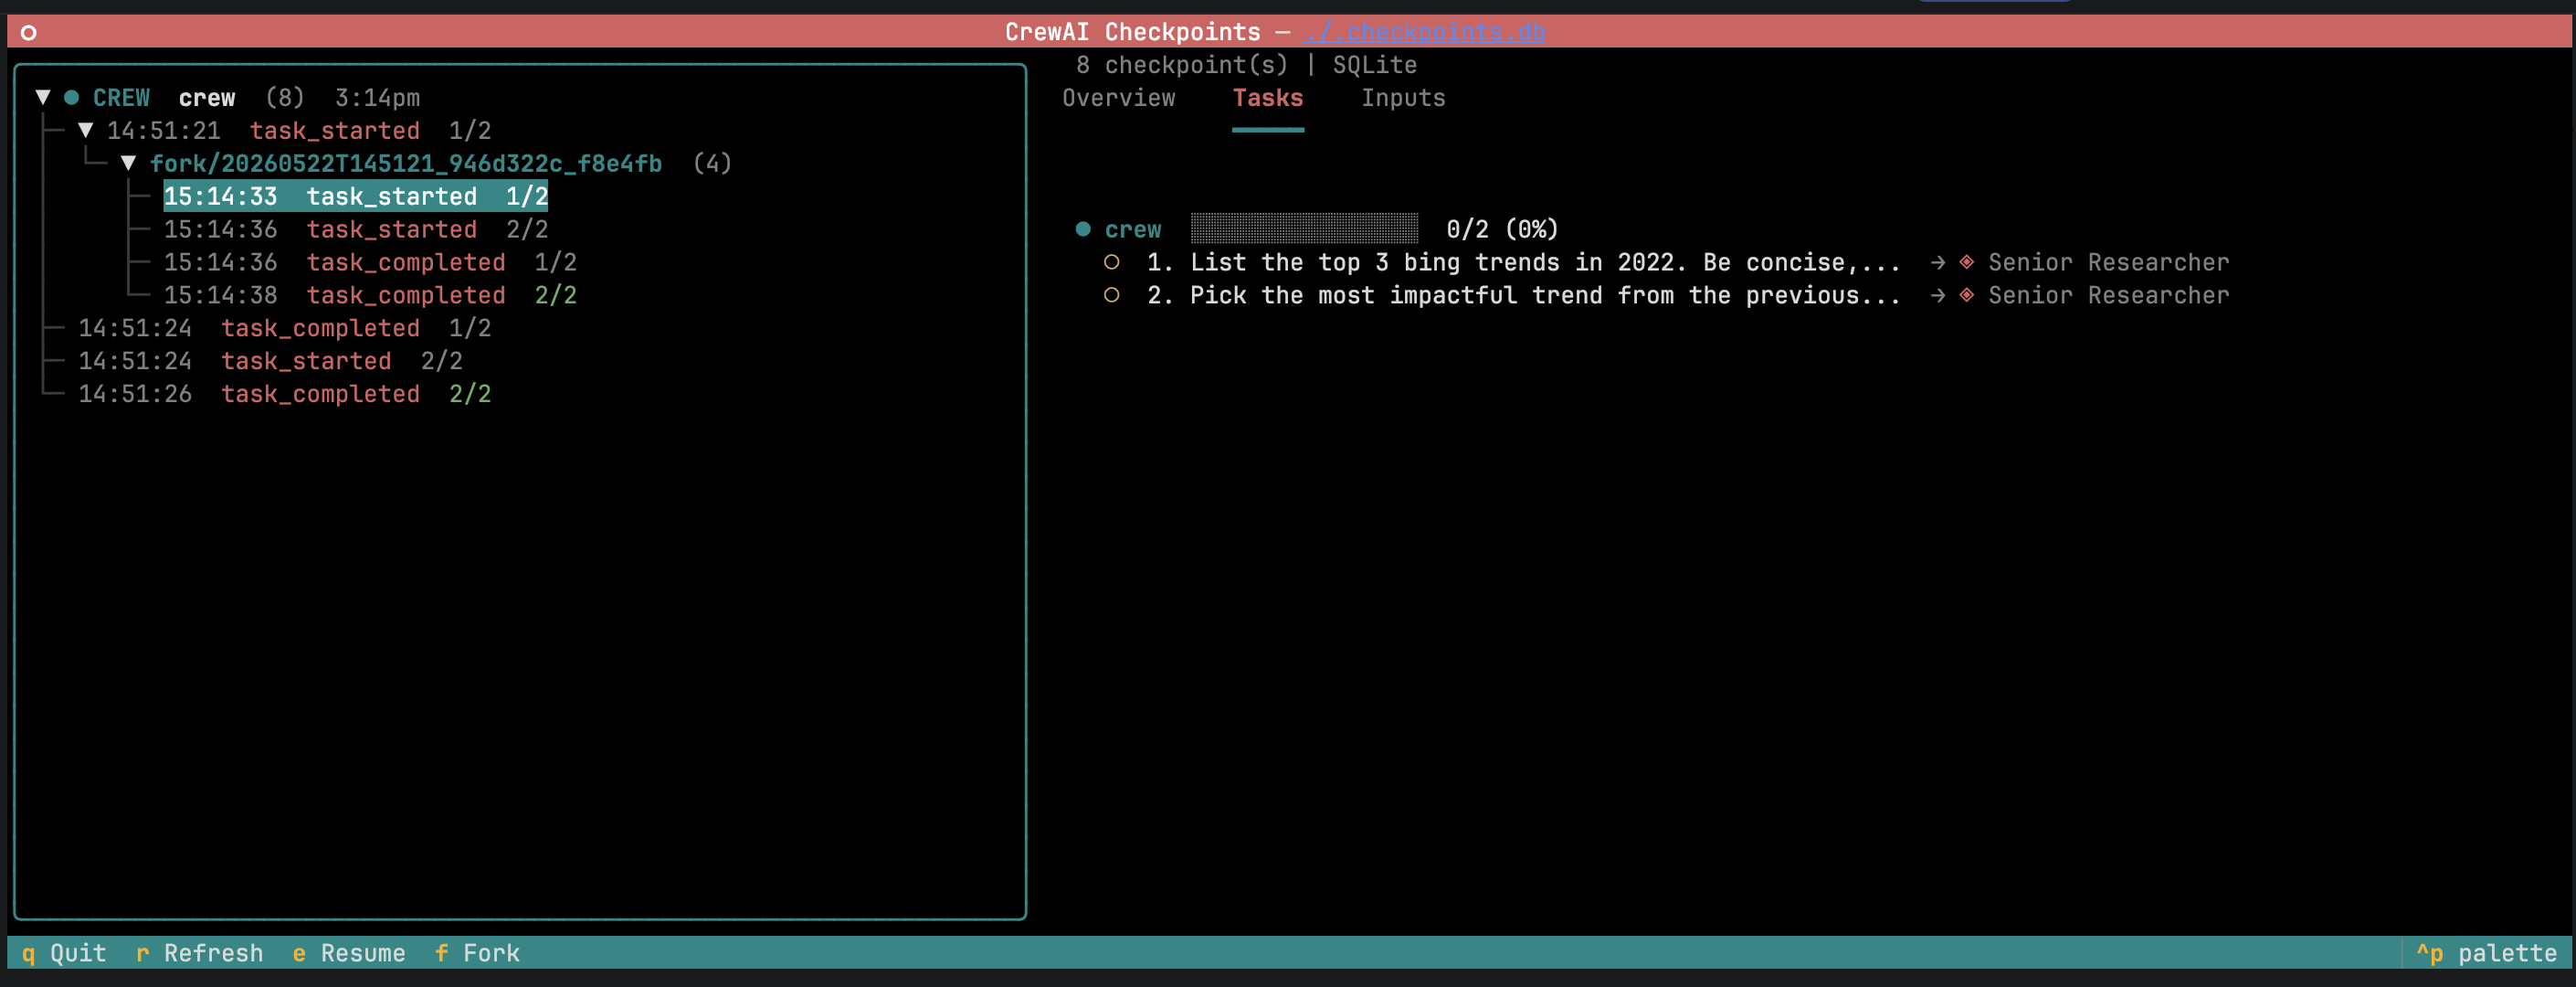
The left panel groups checkpoints by branch; forks nest under their parent. Selecting a checkpoint opens the detail panel with metadata, entity state, and task progress. Resume continues the run; Fork starts a new branch.
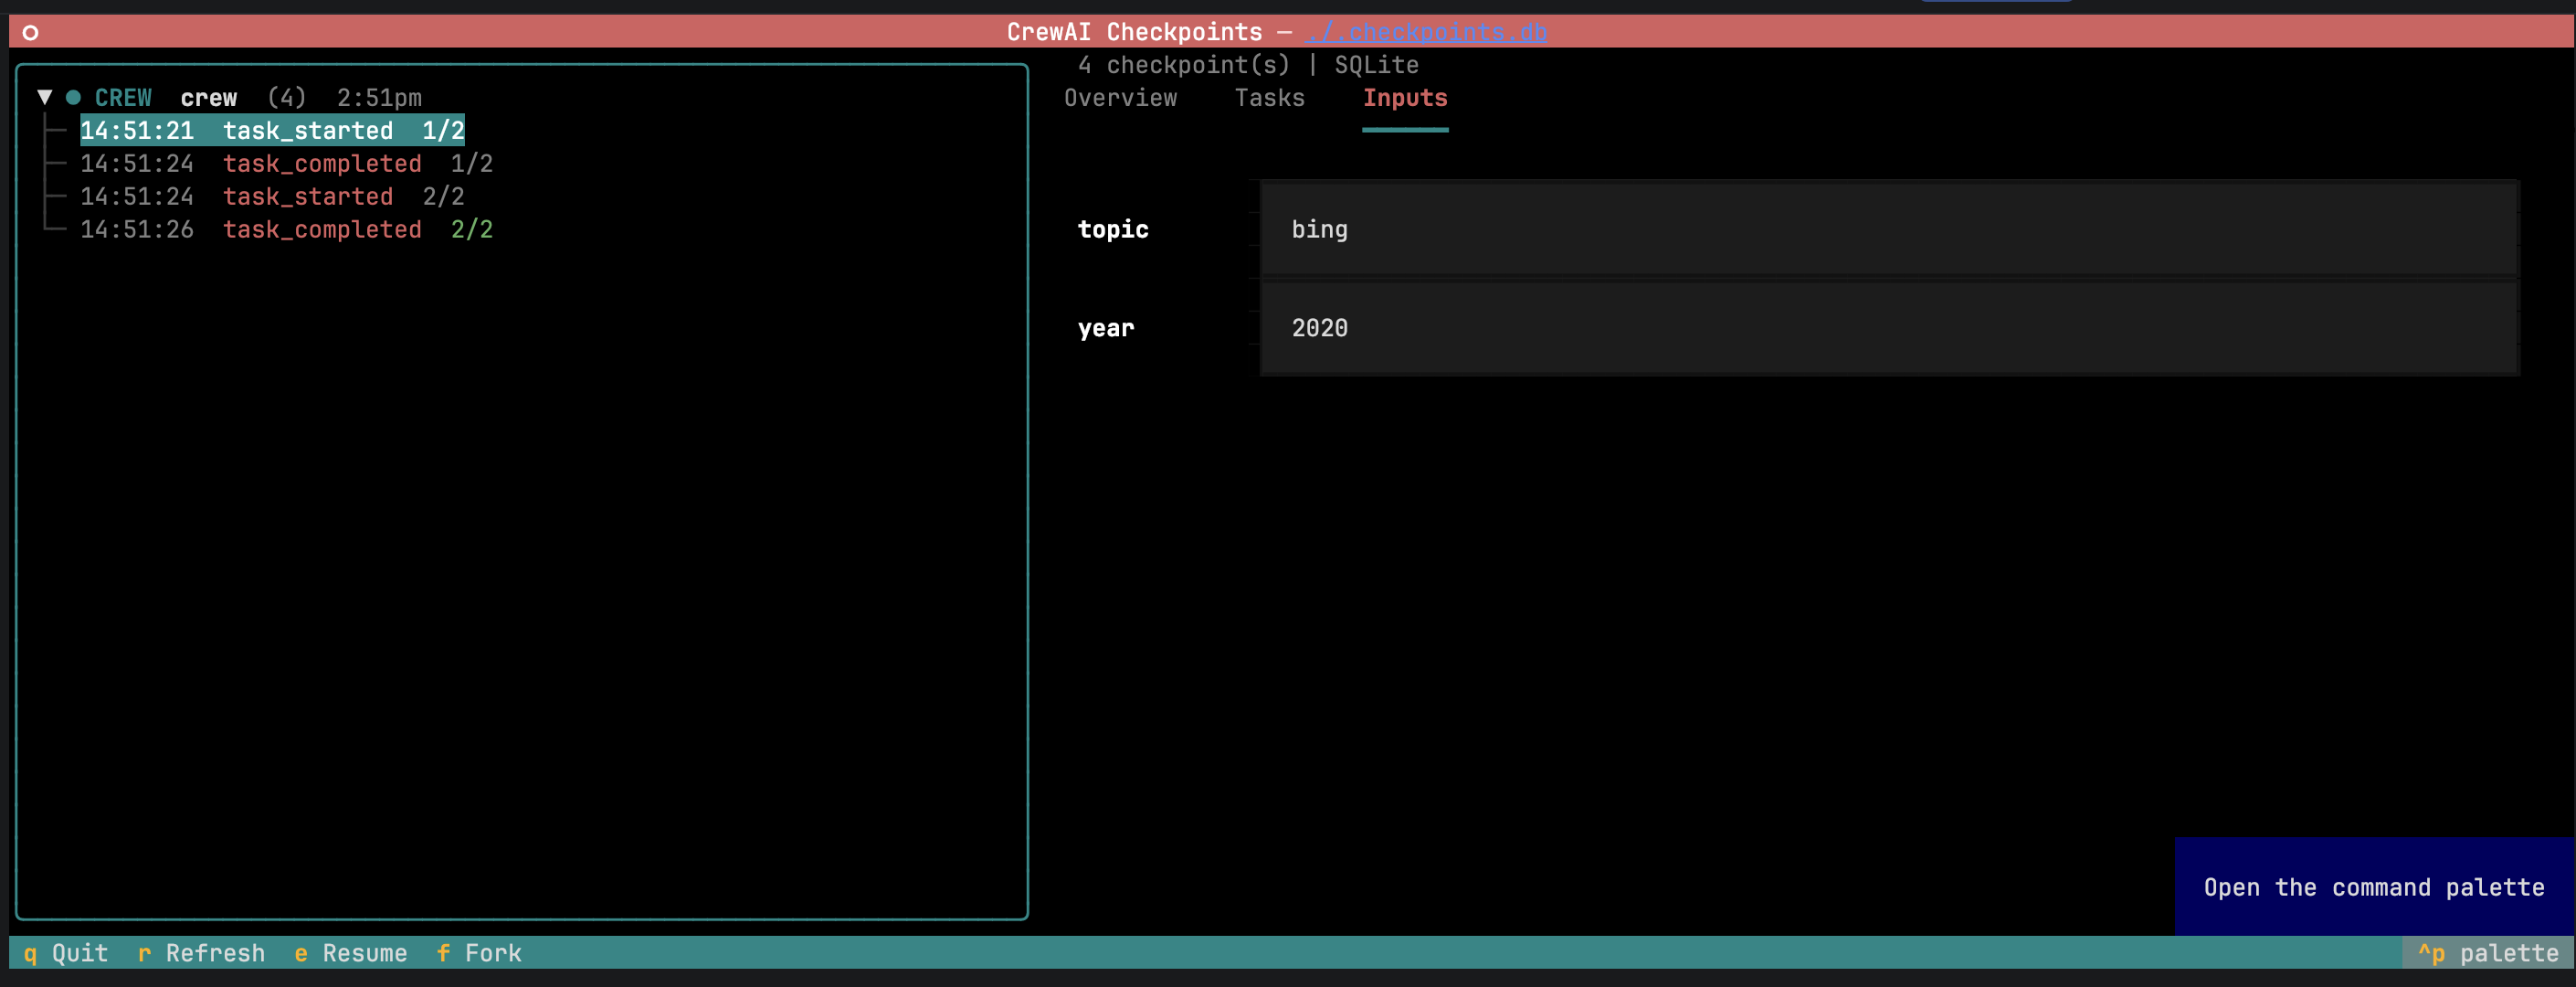
The detail panel exposes two editable areas:
Inputs — original kickoff inputs, pre-filled and editable.
Task outputs — outputs of completed tasks. Editing an output and hitting Fork invalidates downstream tasks so they re-run against the modified context.
Tip
Useful for "what if" exploration: fork, tweak, observe.
crewai checkpoint list ./my_checkpointscrewai checkpoint info ./my_checkpoints/<file>.jsoncrewai checkpoint info ./.checkpoints.db
Reference
CheckpointConfig
locationstrdefault: "./.checkpoints"
Storage destination. A directory for JsonProvider, a database file path for SqliteProvider.
Event types that trigger a checkpoint. CheckpointEventType is a Literal — your type checker will autocomplete and reject unsupported values. See event types for the full list.
providerBaseProviderdefault: JsonProvider()
Storage backend. Either JsonProvider or SqliteProvider.
max_checkpointsint | Nonedefault: None
Maximum checkpoints to retain. Oldest are pruned after each write.
restore_fromPath | str | Nonedefault: None
Checkpoint to restore from when passed via from_checkpoint.
checkpoint field values
Accepted by Crew, Flow, and Agent.
Nonedefault
Inherit from parent.
Truebool
Enable with defaults.
Falsebool
Explicit opt-out. Stops inheritance.
CheckpointConfig(...)CheckpointConfig
Custom configuration.
Event types
on_events accepts any combination of CheckpointEventType values. The default ["task_completed"] writes one checkpoint per finished task; ["*"] matches every event.
Warning
["*"] and high-frequency events like llm_call_completed write many checkpoints and can degrade performance. Pair them with max_checkpoints.